
The emergence of large reasoning models represents one of the most significant developments in modern AI. Unlike standard language model training, which optimizes for next-token prediction, reasoning-focused RL teaches models to think before answering—allocating additional computation at inference time to explore, verify, and refine intermediate steps. This section provides a comprehensive technical treatment of the methods, architectures, and scaling laws that underpin this paradigm.
Motivation and Background
Why Reasoning Requires Different RL Approaches
Standard RLHF (Section 4.3 The RLHF Pipeline) optimizes a single scalar reward over a complete response. For tasks requiring multi-step reasoning—mathematics, formal verification, competitive programming, scientific derivation—this formulation is insufficient for several reasons:
- Sparse rewards: A math problem may require 20 intermediate steps; a single outcome reward provides no gradient signal for the intermediate steps that led to an error.
- Long horizons: Reasoning chains can span hundreds to thousands of tokens, creating severe credit assignment problems.
- Combinatorial search: The space of valid reasoning paths is exponentially large; the model must learn to search this space efficiently.
- Verifiability: Unlike subjective text quality, mathematical and logical correctness is objectively verifiable, enabling automated reward computation without human annotation.
Chain-of-Thought: Emergent Behavior vs. Trained Capability
Chain-of-thought (CoT) reasoning was first observed as an emergent capability in sufficiently large language models [374]: when prompted with step-by-step examples, large models (typically 100B parameters) spontaneously produced intermediate reasoning steps that improved accuracy. This raised a fundamental question: is CoT an emergent property of scale, or can it be explicitly trained?
The answer, as demonstrated by DeepSeek-R1 and related work, is both—but with important nuances:
- Emergent CoT arises from in-context learning and requires large base models. It is brittle, prompt-sensitive, and does not generalize robustly.
- Trained CoT via RL produces models that intrinsically generate reasoning chains as part of their generation process, independent of prompting style. These chains are longer, more exploratory, and exhibit qualitatively different behaviors (self-correction, backtracking, verification).
Test-Time Compute Scaling Laws
A central empirical finding motivating reasoning model research is that test-time compute scales predictably with performance. Let denote training compute (FLOPs) and denote inference compute (tokens generated). The key observation is:
for some monotone function and constants . This implies that a smaller model with more inference compute can match a larger model with less inference compute—a fundamental shift in the compute-performance tradeoff.
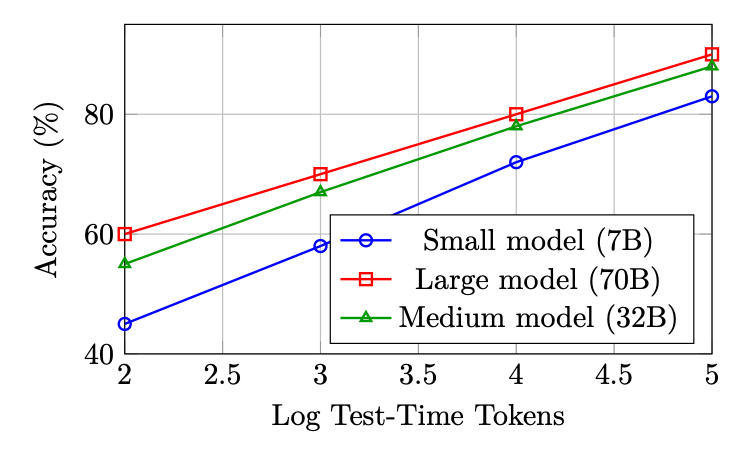
The practical implication is profound: reasoning models trade training compute for inference compute. Rather than always deploying the largest possible model, one can deploy a smaller, reasoning-capable model and allocate more tokens to “thinking” on hard problems.
Test-Time Scaling Methods
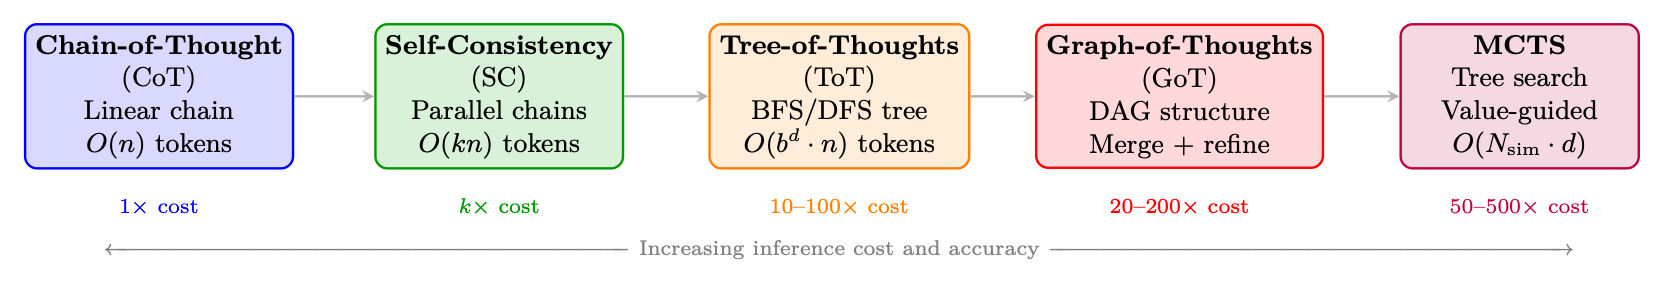
The scaling laws above show that investing more compute at inference can dramatically improve reasoning performance. This section provides a comprehensive treatment of the methods that operationalize test-time scaling — from simple chain-of-thought to sophisticated tree and graph search algorithms. These methods form a spectrum trading inference cost for accuracy, and understanding their structure is essential for designing modern reasoning systems.
Chain-of-Thought (CoT)
Chain-of-Thought prompting [374] is the foundation of all test-time scaling methods. Rather than directly outputting an answer, the model generates intermediate reasoning steps that decompose complex problems into manageable sub-problems.
Kojima et al. [189] demonstrated that appending “Let’s think step by step” to a prompt elicits reasoning behavior without any exemplars. This simple trigger activates latent reasoning capabilities in sufficiently large models (100B parameters).
Wei et al. [374] showed that providing a few exemplars with explicit reasoning traces enables smaller models to reason effectively:
where are hand-written reasoning traces for exemplar .
CoT converts a single-step prediction into a multi-step sequential generation:
where is the greedy reasoning chain. The summation over all possible chains is intractable; standard CoT uses a single sample (greedy or temperature sampling).
Single-chain CoT is fragile: if an early reasoning step is wrong, all subsequent steps build on a flawed foundation with no mechanism for recovery.
Self-Consistency (Majority Voting)
Self-Consistency [367] addresses CoT’s single-chain fragility by sampling multiple independent reasoning chains and taking a majority vote over the final answers:
Key properties:
- Uses temperature sampling to generate diverse chains (typically –)
- No interaction between chains — fully parallelizable
- Accuracy improves monotonically with (diminishing returns after )
- On GSM8K: CoT = 56.5%, Self-Consistency (=40) = 74.4% (with PaLM-540B [55])
- Equivalent to Best-of-N with outcome reward (majority vote acts as implicit ORM)
Tree-of-Thoughts (ToT)
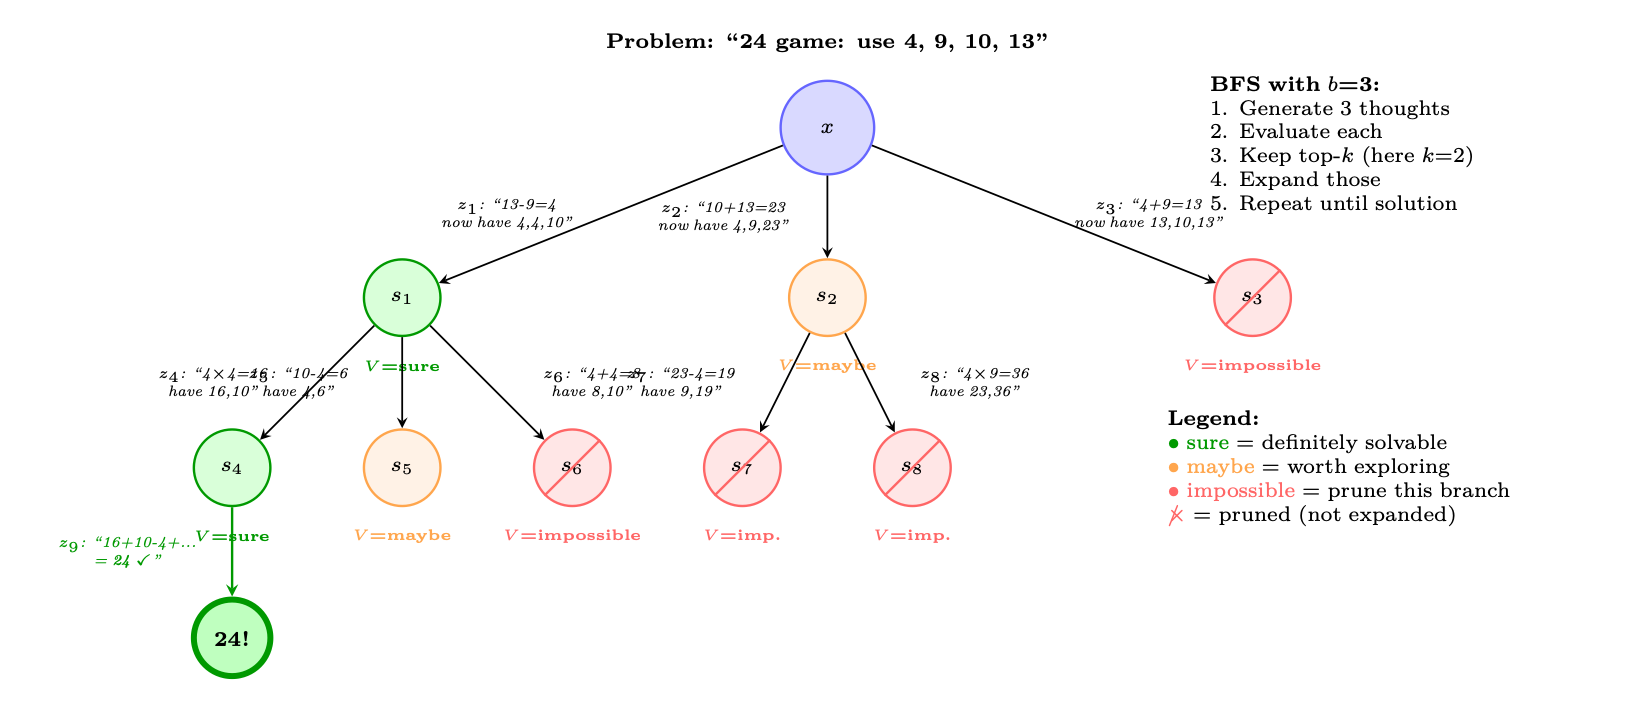
Tree-of-Thoughts [408] generalizes CoT from a linear chain to a tree structure, enabling the model to explore multiple reasoning paths, evaluate intermediate states, and backtrack from unpromising branches. This introduces deliberate planning into the reasoning process.
A reasoning problem is decomposed into a search over a tree where:
- Root: Initial problem statement
- Nodes: Partial reasoning states
- Edges: Individual reasoning steps (“thoughts”)
- Leaves: Complete solutions with final answers
- Value function: estimates how promising a partial solution is
where:
- : Thought generator — produces candidate next thoughts:
- : State evaluator — scores partial solutions: sure, maybe, impossible or
- : The language model generating thoughts
- Search: Search algorithm (BFS or DFS)
BFS (Breadth-First Search):
- Generate candidate thoughts for each node at current depth
- Evaluate all candidates with
- Keep top- most promising states (beam search)
- Advance all states to the next level
- Repeat until a solution is found or depth limit reached
DFS (Depth-First Search):
- Generate candidate thoughts for current state
- Evaluate: if impossible, backtrack immediately
- If sure/maybe, recurse deeper (pick the most promising)
- If depth limit reached without solution, backtrack
- Continue until solution found or all branches explored
For ToT with branching factor , depth , and beam width :
For the 24 game: LLM calls vs. 1 for standard CoT.
On the Game of 24 (a challenging arithmetic reasoning task), ToT achieves 74% success rate vs. CoT’s 4% — a massive improvement from structured search over the same base model (GPT-4).
Graph-of-Thoughts (GoT)
Graph-of-Thoughts [25] extends ToT from a tree to a directed acyclic graph (DAG), introducing a critical capability: merging partial solutions from different branches. This allows the model to synthesize insights from multiple reasoning paths into a single refined solution.
GoT introduces three operations beyond ToT:
- Generate: Produce new thoughts from a state (same as ToT)
- Aggregate/Merge: Combine multiple thoughts into one refined thought — this is impossible in a tree
- Refine: Iteratively improve a thought based on feedback
- Score: Evaluate thought quality (same as ToT’s value function)
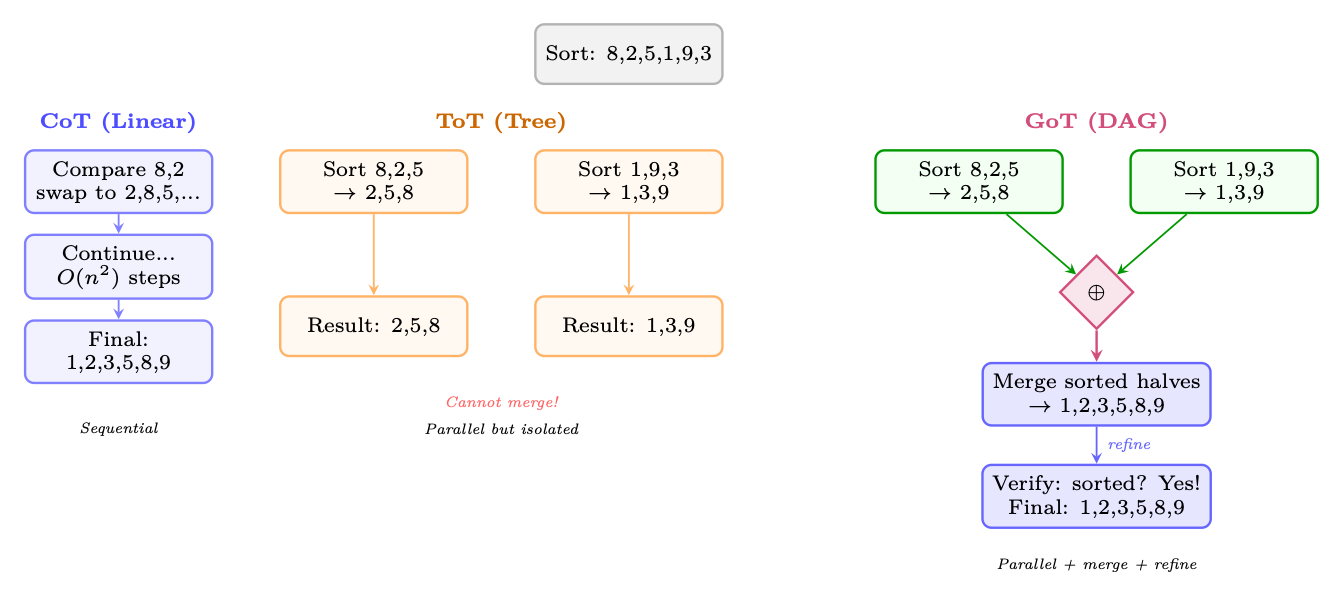
Let be thought vertices and be directed edges. GoT supports:
The Aggregate operation is the key differentiator: it creates edges from multiple parent nodes to a single child, forming a DAG rather than a tree. This enables:
- Divide-and-conquer: Split problem solve sub-problems in parallel merge solutions
- Ensemble reasoning: Generate multiple perspectives, then synthesize the best ideas
- Iterative refinement: Feed evaluation results back to improve earlier thoughts
On sorting (a task requiring merging), GoT achieves 62% cost reduction vs. ToT at equivalent quality. On set intersection and keyword counting, GoT matches ToT quality with 30–40% fewer LLM calls due to the merge operation enabling more efficient decomposition.
Best-of-N with Reward Models
Best-of-N (BoN) [262, 339] is the simplest scaling method that uses a learned reward model to select among candidates:
Variants by reward model type:
- BoN with ORM: Score complete solutions; select the highest-scoring one. Equivalent to Self-Consistency when ORM correctness check.
- BoN with PRM: Score at each reasoning step; select the solution with highest minimum step score (least likely to have an error at any step).
- Weighted BoN: Weight candidates by reward: .
Monte Carlo Tree Search (MCTS) for Reasoning
MCTS [187, 331] combines the structured exploration of ToT with learned value estimates and visit-count statistics to allocate inference compute optimally. Originally developed for game-playing (AlphaGo [331]), MCTS has been adapted for LLM reasoning by systems including AlphaProof [68] and rStar [297].
Each MCTS iteration consists of four phases:
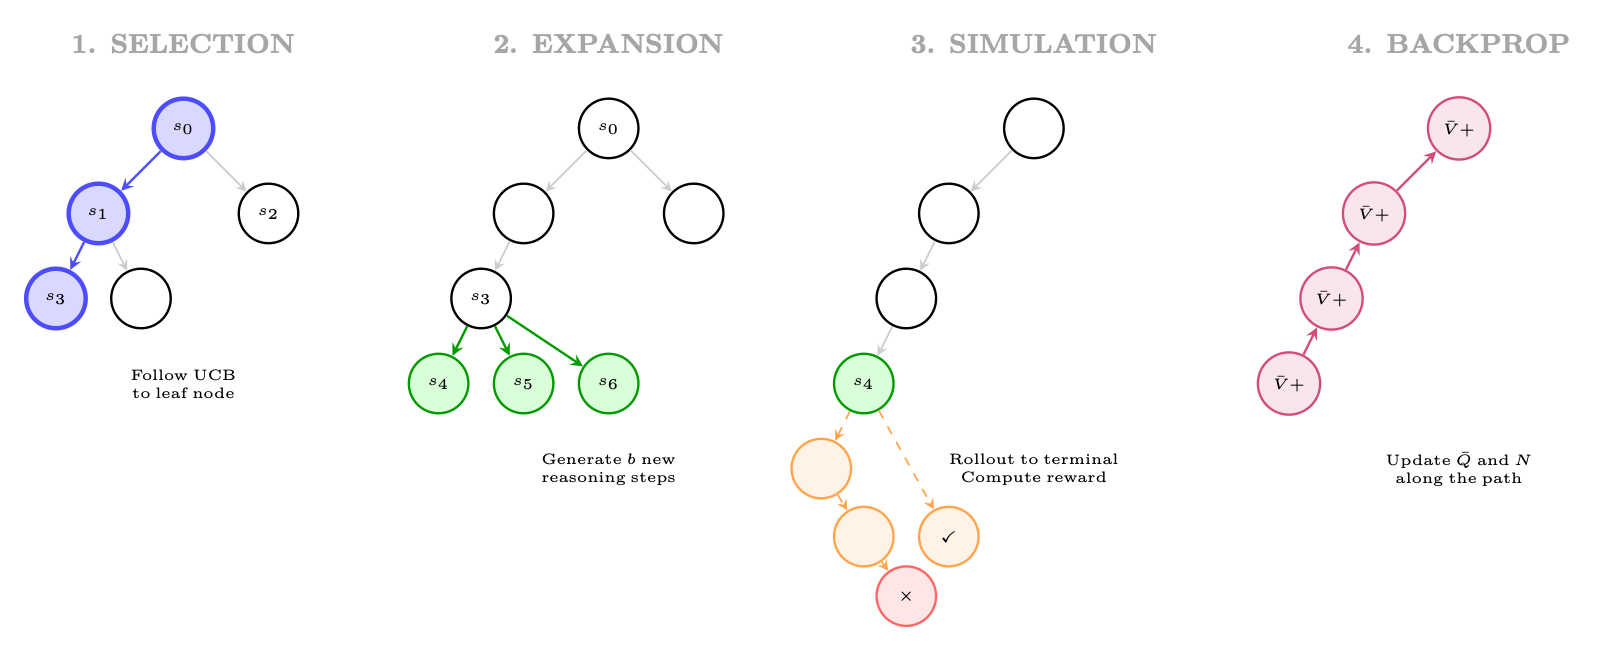
Node selection uses PUCT (Predictor + UCB applied to Trees):
where is the LLM’s prior probability of generating step from state . This biases exploration toward steps the LLM already considers likely, while the UCB term encourages trying under-explored alternatives.
| Dimension | ToT | MCTS |
|---|---|---|
| Value estimation | LLM prompt (“sure/maybe/impossible”) | Learned value network + rollout statistics |
| Exploration | Fixed beam width; no revisiting | UCB adaptively allocates budget to promising nodes |
| Compute allocation | Uniform across depth levels | Focused: more simulations on harder sub-problems |
| Training integration | No training; pure prompting | Can distill MCTS policy into the base model [331] |
| Best for | Simple branching problems (24 game) | Complex problems requiring deep exploration (proofs, code) |
Table 13.1:Tree-of-Thoughts vs. Monte Carlo Tree Search for reasoning.
Beam Search over Reasoning Steps
Beam search — long standard in NMT and text generation — can be applied at the reasoning step level rather than the token level. Instead of tracking the top- token sequences, we track the top-reasoning prefixes:
where the scoring combines the LLM log-probability (fluency) with a value model estimate (correctness). This is effectively ToT-BFS with a learned value function rather than a prompted one.
Iterative Refinement and Self-Correction
Rather than exploring breadth (multiple parallel chains), iterative refinement invests compute in depth — repeatedly improving a single solution:
where may come from:
- Self-verification: Ask the model to check its own answer
- External verification: Run code, check math symbolically
- Critic model: A separate model identifies errors
Notable methods: Self-Refine[246] (iterative self-feedback), Reflexion[326] (verbal RL via reflections stored in memory), and LATS[438] (tree search + reflection-based pruning).
Method Comparison and Selection Guide
| Method | Structure | LLM Calls | Parallelizable | Needs RM? | Best For |
|---|---|---|---|---|---|
| CoT [374] | Chain | 1 | N/A | No | Easy–medium problems |
| Self-Consistency [367] | Parallel chains | ✓ Fully | No (majority vote) | Math with discrete answers | |
| Best-of-N + ORM | Parallel chains | + 1 | ✓ Fully | Yes (ORM) | General tasks with good RM |
| Best-of-N + PRM | Parallel chains | + | ✓ Fully | Yes (PRM) | Complex multi-step reasoning |
| ToT [408] | Tree (BFS/DFS) | Partial | LLM-as-judge | Structured search problems | |
| GoT [25] | DAG | Partial | LLM-as-judge | Decomposable problems | |
| MCTS [187] | Tree + values | Partial | Yes (value net) | Hard proofs, coding | |
| Self-Refine [246] | Linear (iterative) | No | Self-critic | Open-ended generation | |
| LATS [438] | Tree + reflection | Partial | LLM-as-judge | Agent tasks |
Table 13.2:Comprehensive comparison of test-time scaling methods.
DeepSeek-R1
DeepSeek-R1 [69] is the first fully open-source large reasoning model to match or exceed OpenAI o1 on major benchmarks. Its training pipeline is technically transparent and has become the de facto reference implementation for RL-based reasoning.
Two-Stage Training Pipeline
The base model (DeepSeek-V3) is first fine-tuned on a small, carefully curated dataset of long chain-of-thought examples. This “cold start” phase serves two purposes:
- Format initialization: The model learns to produce reasoning in the
<think>...</think>format before emitting a final answer. - Stability: Without cold-start SFT, pure RL from scratch on the base model produces unstable training dynamics and degenerate outputs (e.g., language mixing, repetitive loops).
The cold-start dataset contains only thousands of examples, deliberately kept small to avoid over-constraining the reasoning style that RL will later discover.
After cold-start SFT, the model undergoes large-scale RL using Group Relative Policy Optimization (GRPO). The full GRPO objective as used in R1 is described in Section 13.3.3 GRPO Formulation for R1.
Reward Design: Accuracy and Format Rewards
A key design choice in R1 is the absence of a process reward model. Instead, R1 uses two simple, automatically computable rewards:
For math problems with verifiable answers:
where is the model’s final answer (extracted from ⟨answer⟩ tags) and is the ground-truth answer. The verify function uses symbolic math comparison (e.g., SymPy) to handle equivalent forms.
For code problems, the accuracy reward is determined by passing test cases:
To enforce the <think>...</think> structure:
with in the original implementation (small enough not to dominate, large enough to prevent format collapse).
GRPO Formulation for R1
GRPO [323] is a policy gradient method that avoids training a separate value network by estimating advantages from a group of sampled responses. For a question , GRPO samples responses from the current policy and computes advantages relative to the group mean.
Given question , sample outputs:
Compute rewards using the reward function from Eq. [eq:r1_combined_reward]. The normalized advantage for response is:
where , , and for numerical stability.
The GRPO objective clips the probability ratio (as in PPO) and adds a KL penalty against a reference policy :
where:
- is the per-token probability ratio
- is the PPO clipping parameter
- controls the KL penalty strength
- is the length of response (length normalization prevents bias toward short responses)
The KL divergence term is computed token-by-token:
In practice, R1 uses an unbiased estimator of the KL that avoids computing at every step by using the approximation:
which is always non-negative and equals zero when .
Distillation: The R1-Distill Series
A major practical contribution of R1 is demonstrating that reasoning capabilities can be distilled into much smaller models via supervised fine-tuning on R1-generated chains. The R1-Distill series (1.5B, 7B, 8B, 14B, 32B, 70B parameters) is trained by:
- Generating long-CoT solutions to a large problem set using R1 (671B)
- Filtering to keep only correct solutions
- Fine-tuning smaller base models (Qwen2.5, Llama-3) on these solutions
The distillation approach raises an important question about the nature of reasoning: is the small model truly “reasoning,” or is it pattern-matching on the surface form of reasoning chains? Empirically, distilled models show some generalization to novel problem types, suggesting genuine internalization of reasoning strategies rather than pure memorization.
OpenAI o1/o3 Series
OpenAI’s o1 [275] (released September 2024) and subsequent o3/o4-mini [278] models represent the commercial frontier of reasoning model development. While full technical details remain proprietary, the published system cards, technical reports, and empirical observations provide substantial insight into the methodology.
Chain-of-Thought RL with Hidden Reasoning Tokens
The defining architectural choice of o1 is the use of hidden reasoning tokens: the model generates an internal chain-of-thought (called a “reasoning trace” or “thinking tokens”) that is not shown to the user. Only the final answer is returned. This design has several implications:
- No format constraints: The hidden reasoning can use any format, including scratchpad notation, pseudocode, or even non-English reasoning.
- No reward hacking on style: Since users never see the reasoning, there is no pressure to make it look “good” rather than be useful.
- Proprietary protection: The reasoning process is not exposed, preventing direct imitation.
The training procedure is described as “training models to reason using RL,” with the RL objective applied to the complete (hidden reasoning + final answer) sequence, rewarded only on the quality of the final answer.
Process Reward Models vs. Outcome Reward Models
OpenAI’s approach is believed to use Process Reward Models (PRMs)[216] in addition to outcome rewards, in contrast to DeepSeek-R1’s outcome-only approach. This inference is based on OpenAI’s published PRM research (PRM800K dataset, “Let’s Verify Step by Step”) and the o1 system card’s description of RL training on reasoning chains, though the exact o1/o3 training recipe has not been publicly disclosed.
An ORM scores the complete response :
For verifiable tasks (math, code), this reduces to exact-match verification. For open-ended tasks, a learned reward model is used.
A PRM assigns a reward to each reasoning step in the chain :
where is the step-level reward and is a discount factor. The step-level reward estimates the probability that the partial solution leads to a correct final answer:
Inference-Time Compute Scaling
The o1 technical report demonstrates a clear scaling law: more thinking tokens monotonically improve performance on hard reasoning tasks. This is operationalized through a “thinking budget” parameter that controls the maximum number of hidden reasoning tokens.
Let be the thinking token budget. The empirical scaling law observed is approximately:
for constants , where represents the asymptotic accuracy ceiling and characterizes the rate of improvement. For AIME 2024, o1 with full thinking budget achieves 83% accuracy, compared to 13% for GPT-4o (which uses no extended thinking).
Training Compute vs. Test-Time Compute
A fundamental insight from the o1/o3 series is the compute equivalence principle: there exists a tradeoff curve between training compute and test-time compute such that points on the curve achieve similar performance:
Empirically, for reasoning tasks, suggesting that training and test-time compute are roughly substitutable. This has profound implications for deployment: a smaller, cheaper model with extended thinking can match a larger model on hard problems, at the cost of higher latency.
o3 and o4-mini Architecture Insights
While o3 and o4-mini details remain largely proprietary, several observations have emerged:
- o3: Substantially larger thinking budgets than o1; achieves near-human performance on ARC-AGI (87.5% with high compute). Believed to use more sophisticated search strategies during inference.
- o4-mini: Demonstrates that smaller models with RL-trained reasoning can be highly competitive. Achieves 93% on AIME 2025 with extended thinking, suggesting that model size is less important than reasoning capability for math.
- Tool use: o3/o4-mini integrate tool use (code execution, web search) into the reasoning process, allowing the model to verify intermediate steps programmatically.
QwQ and Qwen Reasoning Models
Alibaba’s Qwen team has developed a series of reasoning models (QwQ-32B [351], Qwen3 [352]) that represent the open-source frontier alongside DeepSeek-R1. Their approach differs in several key respects.
Multi-Stage RL Pipeline
The Qwen reasoning pipeline uses a more elaborate multi-stage approach:
- Base pretraining: Qwen2.5 base model with strong mathematical and coding capabilities
- SFT on diverse reasoning: Fine-tuning on a broad mixture of reasoning tasks (math, code, science, logic)
- Rejection sampling fine-tuning (RFT): Generate solutions per problem, keep correct ones, fine-tune
- RL phase 1: GRPO on math and code with verifiable rewards
- RL phase 2: Broader RL including instruction following and safety
Rejection Sampling + RL Combination
A key innovation in the Qwen approach is the iterative combination of rejection sampling and RL:
- Initialize: Policy from SFT model.
- Rejection Sampling: Sample solutions: . Keep correct solutions: .
- SFT update:
- RL update:
- Repeat steps 2–4 for iterations to obtain final policy .
The rejection sampling step provides high-quality positive examples that anchor the policy, while RL explores beyond the current distribution. This combination is more stable than pure RL and more capable than pure SFT.
Tool-Integrated Reasoning
QwQ-32B and Qwen3 models support tool-integrated reasoning: the model can invoke external tools (Python interpreter, search engine, calculator) during its reasoning chain. This is implemented via special tokens:
<think>
Let me solve this step by step.
First, I'll compute the eigenvalues of the matrix.

<tool_call>
{"name": "python", "arguments": {"code": "import numpy as np\nA = np.array([[2,1],[1,3]])\neigenvalues = np.linalg.eigvals(A)\nprint(eigenvalues)"}}
</tool_call>

<tool_response>
[1.38196601 3.61803399]
</tool_response>

The eigenvalues are approximately 1.382 and 3.618.
These are (5 +/- sqrt(5))/2, which are the golden ratio and its conjugate...
</think>
<answer>The eigenvalues are (5 +/- sqrt(5))/2</answer>
Listing 7:Tool-integrated reasoning format in QwQ
The RL training reward is computed on the final answer, but the model learns to use tools strategically because tool use improves the probability of reaching the correct answer.
Key Methods with Mathematical Foundations
Monte Carlo Tree Search for Reasoning
Monte Carlo Tree Search (MCTS) provides a principled framework for reasoning as tree search. In the AlphaProof [68] and related systems, MCTS is applied over reasoning steps rather than game moves.
- State: The partial reasoning chain where are reasoning steps
- Action: The next reasoning step (a sentence or paragraph)
- Terminal state: A state containing a final answer
- Reward: (Eq. [eq:r1_accuracy_reward])
A value function estimates the probability of reaching a correct answer from partial state :
where is a Monte Carlo rollout from to a terminal state using the current policy.
Node selection uses the Upper Confidence Bound (UCB) formula adapted for reasoning:
where:
- is the mean value of child states
- is the policy prior (language model probability of step )
- is the visit count of state
- is the visit count of the edge
- is the exploration constant
MCTS can be used to generate high-quality training data:
where is the MCTS policy (visit count distribution with temperature ).
Process Reward Models
Math-Shepherd [365] proposes an automated method for training PRMs without human step-level annotations. The key insight is to use outcome-based estimation: a step is labeled as correct if there exists a completion from that reaches the correct answer.
Formally, for a partial solution :
In practice, this is estimated by sampling completions from and checking if any are correct:
The PRM is then trained with binary cross-entropy:
A primary application of PRMs is best-of-N selection: generate candidate solutions and select the one with the highest PRM score:
This is more effective than majority voting (which uses ORM) because PRM can distinguish between solutions that reach the same answer via different quality reasoning paths.
Outcome Reward Models and Majority Voting
The simplest form of test-time compute scaling is majority voting [367]: generate solutions and return the most common answer:
Under the assumption that each solution is independently correct with probability , the probability that majority voting is correct is:
An ORM can improve majority voting by weighting votes by confidence:
Self-Play for Reasoning
Self-play methods generate training data by having the model play both the generator and verifier roles.
STaR [419] bootstraps reasoning capabilities iteratively:
- Generate reasoning chains for a problem set
- Keep chains that lead to correct answers (rejection sampling)
- Fine-tune on kept chains
- Repeat with the improved model
The key insight is that the model can rationalize correct answers: even if it cannot solve a problem from scratch, it can generate a plausible reasoning chain given the answer, which can then be used as training data.
In self-play RL for reasoning, the model generates both problems and solutions:
where generates problems and solves them. The generator is rewarded for producing problems that are challenging but solvable.
Reinforcement Learning from Verifiable Rewards (RLVR)
RLVR [199] is a framework that uses ground-truth verification as the reward signal, applicable to any domain where correctness can be automatically checked.
- Mathematics: Symbolic verification via SymPy, Lean, or Isabelle
- Code: Unit test execution
- Formal logic: Proof checking
- Factual QA: Database lookup
- Games: Win/loss outcome
The key advantage of RLVR over RLHF is the absence of reward model error: since the reward is computed by a deterministic verifier rather than a learned model, there is no reward hacking against a flawed reward model. The only failure mode is if the model finds solutions that pass verification but are not genuinely correct (e.g., exploiting test case weaknesses in code evaluation).
Journey Learning
Journey Learning [298] proposes training on the full reasoning trajectory, including failed attempts and corrections, rather than only successful final solutions.
Standard rejection sampling discards failed attempts. But failed attempts contain valuable information:
- Which approaches don’t work (negative examples)
- How to recognize and recover from errors (correction patterns)
- The structure of the problem space (exploration data)
Given a trajectory that may include backtracking:
where the weights are designed to emphasize:
- Steps that lead to eventual success ()
- Correction steps after errors ()
- Steps in failed branches (, but )
Quiet-STaR: Reasoning at Every Token
Quiet-STaR [418] extends the reasoning paradigm to every token position: rather than generating a reasoning chain only before the final answer, the model generates a “thought” at every token position.
For each token position , the model generates a hidden thought before predicting the next token :
In practice, this is approximated by mixing the predictions with and without the thought:
Since the thought is a discrete latent variable, the gradient is estimated using REINFORCE:
where is a baseline (e.g., the no-thought prediction ).
Scaling Laws for Reasoning
Recent work [335, 388] has established that test-time compute scales predictably with reasoning performance, extending the classical scaling laws [177] into the inference regime.
Training Compute vs. Test-Time Compute Tradeoff
The fundamental scaling question for reasoning models is: given a fixed total compute budget (where is the number of queries), how should compute be allocated?
Let denote the accuracy of a model trained with FLOPs and given inference FLOPs per query. Empirically:
for constants . The optimal allocation for a fixed total budget satisfies the condition that marginal return per FLOP is equalized between training and inference:
Intuitively: one FLOP of training benefits all queries, while one FLOP of test-time benefits only one query. At the optimum, the per-query marginal value of test-time compute is times larger than training compute (because training is amortized). Applying this to Eq. [eq:reasoning_scaling_law] gives the optimal training compute fraction:
For the specific budget structure , this fraction is independent of under the multiplicative accuracy model. However, in practice and are problem-dependent: for high-volume deployments (large ), even small improvements in the base model dominate, favoring training investment. For low-volume, high-stakes queries (small ), test-time compute is more cost-effective.
When to Invest in Longer Chains vs. Better Base Models
The “overthinking” phenomenon—where models with very long reasoning chains perform worse than those with moderate chains—has been empirically observed and is attributed to:
- Accumulation of errors in long chains (error propagation)
- Distraction from the main solution path
- Overconfidence in incorrect intermediate conclusions
Optimal Token Budget Allocation
For a model with a fixed token budget , the allocation between “thinking” tokens and “answering” tokens should satisfy:
Empirically, the optimal split is problem-dependent:
- Simple problems: (30% thinking)
- Hard problems: (80% thinking)
- Very hard problems: (95% thinking, minimal answer)
This motivates adaptive thinking budgets: allocating more tokens to harder problems, which can be estimated by the model’s uncertainty on initial solution attempts.
Comparison of Reasoning Models
| Method | PRM | ORM | MCTS | Distill | Tool | Open |
|---|---|---|---|---|---|---|
| OpenAI o1/o3 | ✓ | ✓ | Unknown | – | ✓ | |
| DeepSeek-R1 | ✓ | ✓ | ✓ | |||
| QwQ / Qwen3 | Partial | ✓ | ✓ | ✓ | ||
| AlphaProof | ✓ | ✓ | ✓ | – | ✓ | |
| Math-Shepherd | ✓ | ✓ | – | ✓ | ||
| STaR / Quiet-STaR | ✓ | – | ✓ |
Table 13.3:Comparison of training methodologies for reasoning models.
Inference-Time Compute Scaling Laws
Training-time scaling laws (Chinchilla [140]) are well-understood: model performance improves predictably with compute, data, and parameters. Inference-time compute scaling is the new frontier—the empirical finding that allocating more computation at test time (longer reasoning chains, more search, iterative refinement) can solve problems that larger base models cannot.
The Overthinking Problem
Inference-time scaling introduces a critical failure mode: overthinking. Reasoning models trained to generate long chains of thought continue generating tokens even when the answer is obvious, wasting compute and sometimes degrading accuracy by introducing spurious reasoning steps.
Efficient Reasoning Techniques
Several approaches address the compute-quality trade-off in inference-time scaling:
- Sketch-of-Thought: Generate a compressed reasoning sketch before the full chain. Achieves 84% token reduction with minimal accuracy loss by separating planning from execution in the reasoning trace.
- Budget-aware prompting: Explicitly instruct the model with a token budget (“solve this in under 200 tokens”). Halves inference costs on benchmarks where problems have known difficulty.
- Shorter chains boost accuracy: On some tasks, enforcing shorter reasoning chains improves accuracy by 34.5%—the model is forced to be more direct and avoids overthinking spirals.
- Adaptive depth: OpenAI’s
reasoning_effortparameter (low/medium/high) routes queries to different token budgets based on estimated difficulty, providing a practical API for compute-quality trade-offs.
Connection to RL: Inference Compute as MDP Horizon
Latent Reasoning: Is the Chain the Computation?
A growing body of evidence challenges the assumption that chain-of-thought is the reasoning:
- Reasoning Beyond Chain-of-Thought[168]: Using Sparse Autoencoders to probe internal representations, this work identifies reasoning-specific features that activate before the corresponding tokens are generated—suggesting the model “knows the answer” before writing the chain.
- Thinking to Recall[114] (Google, COLM 2026): Demonstrates that generating a reasoning trace unlocks parametric knowledge that is otherwise effectively unreachable via direct prompting—but the trace itself may be a scaffold rather than the computation.
On-Policy Self-Distillation for Reasoning
The methods in this chapter—GRPO, process rewards, MCTS—share a fundamental limitation: sparse feedback. Reinforcement learning provides a fixed number of bits per episode regardless of sequence length. A 2000-token chain-of-thought that arrives at the wrong answer receives a single scalar penalty; the model does not learn which tokens contributed to the failure. On-Policy Self-Distillation (OPSD) [430] addresses this by providing dense, token-level supervision while retaining the on-policy property that makes RL effective.
The Training Objective
Let denote the student policy (the model given only the question) and denote the teacher policy (the same model conditioned on privileged context such as a verified answer). For a trajectory sampled from the student, the OPSD loss minimizes the per-token reverse KL divergence:
In practice, this simplifies to the difference in log-probabilities evaluated on the sampled tokens:
The teacher’s log-probabilities require only a single forward pass (no gradient computation), making the approach significantly cheaper than running a separate reward model or performing full RL rollouts with delayed rewards.
Why Dense Supervision Matters
The information-theoretic argument is compelling: RL teaches bits per episode (the scalar reward), while token-level distillation teaches bits per episode. This translates directly into training efficiency:
- Qwen3 results: The Qwen3 technical report reports that on-policy distillation achieves 74.4% on AIME’24 at one-tenth the GPU-hours of their RL pipeline (1,800 vs. 17,920 GPU-hours), while exceeding RL’s 67.6%.
- Step efficiency: Empirical comparisons show OPSD reaching equivalent reasoning performance in 7–10 fewer gradient steps than GRPO, corresponding to 50–100 compute savings when accounting for shorter required context lengths and smaller batch sizes.
- Data reuse: Unlike RL, which memorizes final answers when trained on repeated prompts, OPSD learns to approximate the teacher’s full distribution via reverse KL, enabling effective multi-epoch training on small prompt sets.
Failure Modes and Mitigations
RLCSD [282] addresses this pathology through a contrastive formulation: it computes the teacher-student gap under both a correct hint and an incorrect hint, then subtracts the latter to cancel out the style component that conditioning on any hint induces. The residual signal concentrates on task-relevant tokens.
EGRSD [181] takes a complementary approach: it introduces an entropy-guided confidence gate that down-weights token positions where the teacher’s predictive distribution is high-entropy (uncertain), focusing the gradient on positions where the teacher is confident and the student diverges.
Connection to RL and the Training Pipeline
OPSD occupies a specific niche in the post-training pipeline:
The practical pipeline emerging in frontier labs is: (1) SFT on teacher-generated reasoning traces to initialize the policy within the correct distribution; (2) OPSD to cheaply recover or refine reasoning capabilities with dense supervision; (3) RL for the final push on hard problems where OPSD’s teacher signal becomes unreliable (the teacher itself cannot solve them).
Summary and Open Problems
The field of RL for reasoning models has advanced remarkably rapidly. Several key lessons have emerged:
- Verifiable rewards are sufficient: For domains with ground-truth verification (math, code), outcome-only rewards are sufficient for RL to discover sophisticated reasoning strategies, without requiring process reward models.
- Test-time compute is a new axis: Reasoning models introduce a new dimension of scaling—inference compute—that is roughly substitutable with training compute for hard reasoning tasks.
- Distillation is highly effective: Large reasoning models can transfer their capabilities to much smaller models via supervised fine-tuning on generated chains, often outperforming direct RL training of small models. On-policy self-distillation further closes the gap between distillation and RL at a fraction of the compute.
- Emergent meta-cognition: RL training on reasoning tasks produces emergent self-correction and verification behaviors that were not explicitly trained.
- Dense supervision beats sparse rewards: On-policy self-distillation achieves RL-level reasoning at 10–100 lower compute by providing token-level feedback rather than episode-level rewards.
The development of reasoning models represents a paradigm shift: from language models that know things to language models that can figure things out. The methods described in this chapter—from RL with verifiable rewards through inference-time compute scaling to on-policy self-distillation—form a rapidly expanding toolkit, and their continued development is likely to be a central focus of AI research in the coming years.