
Motivation: Why Multiple Agents?
The history of artificial intelligence is, in many ways, a history of scale. Early AI systems were monolithic: a single program, a single knowledge base, a single inference engine. As problems grew more complex, researchers discovered that no single agent—however capable—could efficiently handle every aspect of a rich, open-ended task. This insight, long established in distributed AI and multi-agent systems (MAS) research [375, 382], has found renewed urgency in the era of large language models.
Four fundamental motivations drive the shift from monolithic agents to agent societies:
Different sub-tasks benefit from different capabilities, prompting strategies, and even different base models. A code-generation agent can be fine-tuned on programming corpora; a fact-checking agent can be grounded with retrieval tools; a creative-writing agent can be prompted for stylistic diversity. Forcing a single agent to excel at all of these simultaneously is both inefficient and often impossible.
Many real-world tasks decompose into independent sub-tasks that can be executed concurrently. A research pipeline that requires literature review, data analysis, and report writing can run all three in parallel, dramatically reducing wall-clock time. Sequential single-agent processing is a bottleneck that multi-agent parallelism eliminates.
A single agent is a single point of failure. If it hallucinates, gets stuck in a loop, or produces a subtly wrong answer, there is no check. Multi-agent systems introduce redundancy: a second agent can verify, critique, or independently re-derive results. Adversarial agents can probe for weaknesses before outputs are trusted.
Perhaps most intriguingly, agent collectives can exhibit capabilities that no individual agent possesses. Through debate, negotiation, and iterative refinement, multi-agent systems can arrive at solutions that transcend what any single agent could produce alone—a computational analog to the emergent intelligence of social organisms.
The transition from monolithic agents to agent societies mirrors a broader pattern in complex systems: as the problem space grows, distributed, modular architectures consistently outperform centralized, monolithic ones. The question is no longer whether to use multiple agents, but how to organize them.
Multi-Agent Architectures
The topology of a multi-agent system—how agents are connected and how authority flows among them—is the most consequential architectural decision. Four canonical patterns have emerged, each with distinct trade-offs.
Centralized (Supervisor/Manager) Architecture
In a centralized architecture, a single orchestrator agent (variously called supervisor, manager, or planner) holds global state, decomposes tasks, delegates sub-tasks to worker agents, and aggregates their results. The topology is a hub-and-spoke: all communication flows through the central node.
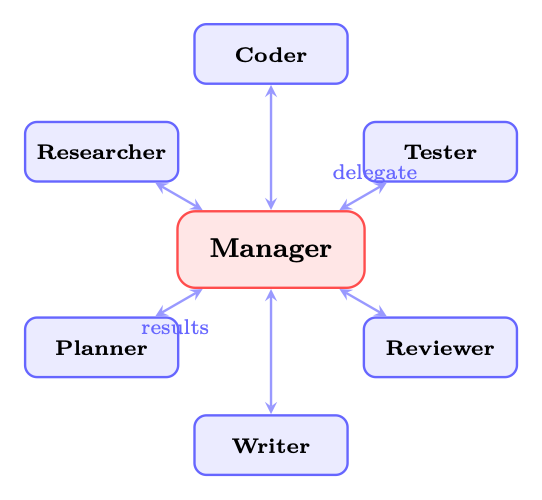
The manager’s responsibilities include:
- Task routing: deciding which worker is best suited for each sub-task
- Context management: providing each worker with the relevant subset of global context
- Result aggregation: synthesizing worker outputs into a coherent whole
- Error handling: detecting worker failures and re-routing or retrying
Decentralized (Peer-to-Peer) Architecture
In a decentralized architecture, agents interact directly with one another without a central coordinator. The topology is a mesh: any agent can communicate with any other. Coordination emerges from local interactions rather than global planning.
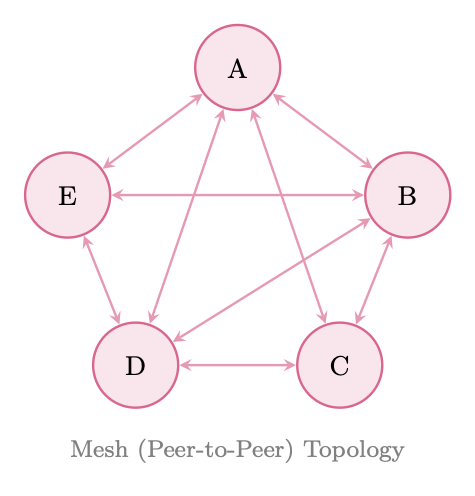
Emergent coordination in peer-to-peer systems arises through mechanisms such as:
- Negotiation: agents bid for tasks or resources
- Stigmergy: agents modify shared state that others observe (see Section 25.3.6 Stigmergy: Indirect Communication Through Environment)
- Gossip protocols: agents propagate information through the network
- Local consensus: small groups of agents reach agreement without global coordination
Hierarchical Architecture
Hierarchical architectures generalize the centralized pattern into a tree structure with multiple levels of management. A top-level orchestrator delegates to domain-specific sub-managers, who in turn delegate to specialized workers. This mirrors the organizational structure of large enterprises.
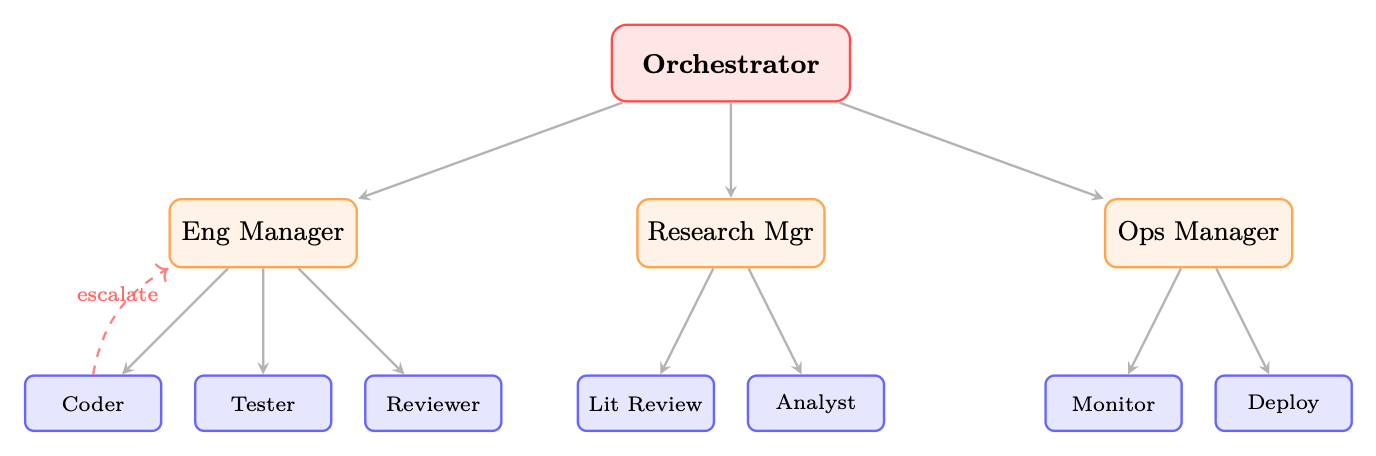
Key features of hierarchical systems:
- Delegation chains: authority and context flow down the tree; results flow up
- Escalation paths: workers can escalate unresolvable issues to their manager
- Domain isolation: sub-managers maintain domain-specific context, reducing the cognitive load on the top-level orchestrator
- Scope limitation: each agent only needs to know about its immediate superiors and subordinates
The enterprise analogy is apt: a CEO (top orchestrator) sets strategy; VPs (sub-managers) translate strategy into domain plans; individual contributors (workers) execute. The hierarchy enables scale while preserving accountability.
Swarm Architecture
Swarm architectures, inspired by biological systems (ant colonies, bird flocking), consist of many loosely coupled agents that follow simple local rules, producing complex global behavior without any central coordinator or global state.
OpenAI’s Swarm framework [276] (now superseded by the OpenAI Agents SDK, but its conceptual primitives remain influential) operationalizes this with two primitives:
- Routines: sequences of instructions an agent follows to complete a sub-task
- Handoffs: an agent transferring control (and relevant context) to another agent
Coordination Mechanisms
How agents coordinate—how they share information, divide work, and resolve conflicts—is as important as the topology. Six canonical coordination mechanisms apply to LLM-based multi-agent systems.
Shared State (Global Blackboard)
The blackboard architecture[135] provides a shared data structure that all agents can read from and write to. In LLM systems, this is typically implemented as a shared dictionary, database, or structured document.
import threading
from dataclasses import dataclass, field
from typing import Any, Callable, Dict, List

@dataclass
class BlackboardEntry:
    value: Any
    author: str
    timestamp: float
    confidence: float = 1.0

class Blackboard:
    """Thread-safe shared state for multi-agent coordination."""

    def __init__(self):
        self._data: Dict[str, BlackboardEntry] = {}
        self._lock = threading.RLock()
        self._subscribers: Dict[str, List[Callable]] = {}

    def write(self, key: str, value: Any, author: str,
              confidence: float = 1.0) -> bool:
        """Write to blackboard; higher-confidence entries win conflicts."""
        with self._lock:
            existing = self._data.get(key)
            if existing and existing.confidence > confidence:
                return False  # Conflict: existing entry wins
            import time
            self._data[key] = BlackboardEntry(
                value=value, author=author,
                timestamp=time.time(), confidence=confidence
            )
            self._notify(key, value)
            return True

    def read(self, key: str) -> Any:
        with self._lock:
            entry = self._data.get(key)
            return entry.value if entry else None

    def subscribe(self, key: str, callback: Callable):
        """Agents subscribe to changes on specific keys."""
        self._subscribers.setdefault(key, []).append(callback)

    def _notify(self, key: str, value: Any):
        for cb in self._subscribers.get(key, []):
            cb(key, value)
Listing 33:Shared blackboard with conflict resolution
Message Passing
Message passing is the most natural coordination mechanism for LLM agents: agents communicate by sending structured text messages to one another. Key design decisions include:
- Message format: structured (JSON schema) vs. natural language vs. hybrid
- Routing: direct (agent-to-agent) vs. broadcast vs. topic-based pub/sub
- Conversation threads: maintaining context across multi-turn exchanges
- Acknowledgment: whether senders require confirmation of receipt/processing
Planning and Decomposition
A manager agent decomposes a high-level task into a directed acyclic graph (DAG) of sub-tasks, assigns each to an appropriate worker, and tracks dependencies. This is the multi-agent analog of classical hierarchical task network (HTN) planning.
from dataclasses import dataclass, field
from typing import List, Optional
import asyncio

@dataclass
class Task:
    id: str
    description: str
    assigned_to: str
    dependencies: List[str] = field(default_factory=list)
    status: str = "pending"   # pending | running | done | failed
    result: Optional[str] = None

class TaskDAG:
    def __init__(self):
        self.tasks: dict[str, Task] = {}

    def add_task(self, task: Task):
        self.tasks[task.id] = task

    def ready_tasks(self) -> List[Task]:
        """Return tasks whose dependencies are all completed."""
        return [
            t for t in self.tasks.values()
            if t.status == "pending"
            and all(self.tasks[d].status == "done"
                    for d in t.dependencies)
        ]

    async def execute(self, agent_pool: dict):
        while any(t.status != "done" for t in self.tasks.values()):
            ready = self.ready_tasks()
            if not ready:
                await asyncio.sleep(0.1)
                continue
            # Execute ready tasks in parallel
            await asyncio.gather(*[
                self._run_task(t, agent_pool[t.assigned_to])
                for t in ready
            ])

    async def _run_task(self, task: Task, agent):
        task.status = "running"
        try:
            task.result = await agent.execute(task.description)
            task.status = "done"
        except Exception as e:
            task.status = "failed"
            raise
Listing 34:Task DAG decomposition
Voting and Consensus
When multiple agents produce conflicting outputs, voting mechanisms aggregate their responses into a single decision. Common schemes include:
- Majority voting: the most common answer wins; effective for factual questions
- Weighted voting: agents with higher track records or confidence scores receive more weight
- Debate-based resolution: agents argue for their positions; a judge agent decides
- Delphi method: iterative rounds where agents revise their answers after seeing others’ reasoning
Formally, given agents producing outputs with weights , the weighted consensus is:
For continuous outputs (e.g., probability estimates), weighted averaging applies:
Market-Based Coordination
Market mechanisms allocate tasks and resources through auctions and bidding. The Contract Net Protocol [334], one of the oldest multi-agent coordination mechanisms, is a task auction:
- A manager broadcasts a task announcement with requirements
- Contractor agents submit bids (capability declarations + cost estimates)
- The manager awards the contract to the best bidder
- The winning contractor executes and reports results
In LLM systems, bids can be expressed in natural language (“I can complete this in 3 steps with high confidence”) or structured formats. Market mechanisms are particularly effective for resource-constrained settings where API costs must be minimized.
Stigmergy: Indirect Communication Through Environment
Stigmergy[117] replaces explicit agent-to-agent messaging with a simpler mechanism: each agent modifies the shared environment as a side effect of its work, and other agents react to those modifications rather than to direct signals. The classic illustration is a foraging ant depositing pheromone on its return path; subsequent ants amplify successful routes without any ant “talking” to another.
In LLM multi-agent systems, stigmergy manifests as:
- Shared documents: agents write to a shared document; others read and build upon it
- Code repositories: one agent commits code; another reads and extends it
- Annotation layers: agents annotate shared artifacts (highlight errors, add comments)
- Task queues: agents add and consume tasks from a shared queue
Stigmergy enables coordination without explicit communication overhead—agents simply observe the state of the shared environment and act accordingly.
Communication Protocols
Effective multi-agent systems require well-defined communication protocols: agreed-upon formats, semantics, and patterns for agent-to-agent messages. (For the standardized inter-agent protocol, see Chapter Chapter 24 Agent-to-Agent Communication (A2A).)
Structured Message Formats
Messages between LLM agents should be structured to enable reliable parsing and routing. A minimal message schema:
from pydantic import BaseModel, Field
from typing import Literal, Optional, Dict, Any
from datetime import datetime, timezone
import uuid

PerformativeType = Literal[
    "inform",    # Share information
    "request",   # Request an action
    "propose",   # Propose a course of action
    "accept",    # Accept a proposal
    "reject",    # Reject a proposal
    "query",     # Ask a question
    "confirm",   # Confirm receipt/completion
    "failure",   # Report a failure
]

class AgentMessage(BaseModel):
    message_id: str = Field(default_factory=lambda: str(uuid.uuid4()))
    conversation_id: str          # Groups related messages
    sender: str                   # Agent identifier
    receiver: str                 # Target agent (or "broadcast")
    performative: PerformativeType
    content: str                  # Natural language content
    metadata: Dict[str, Any] = {} # Structured payload
    reply_to: Optional[str] = None  # message_id being replied to
    timestamp: datetime = Field(default_factory=lambda: datetime.now(timezone.utc))

    def to_llm_prompt(self) -> str:
        """Render message as a prompt fragment for the receiving agent."""
        return (
            f"[MESSAGE from {self.sender}]\n"
            f"Type: {self.performative}\n"
            f"Content: {self.content}\n"
            + (f"Metadata: {self.metadata}\n" if self.metadata else "")
        )
Listing 35:Agent message schema
Performative Types (FIPA-ACL Inspired)
Drawing from the FIPA Agent Communication Language [93], modernized for LLM agents:
| Performative | Semantics | Example Use |
|---|---|---|
| inform | Sender believes is true | Share research findings |
| request | Sender wants receiver to do | Delegate a sub-task |
| propose | Sender proposes plan | Suggest an approach |
| accept | Receiver agrees to proposal | Confirm task assignment |
| reject | Receiver declines proposal | Refuse incompatible task |
| query | Sender wants to know | Ask for clarification |
| confirm | Sender confirms occurred | Acknowledge completion |
| failure | Sender failed to achieve | Report error |
Table 25.1:FIPA-ACL-inspired performative types for LLM agent messages.
Context Sharing Strategies
A critical challenge in multi-agent communication is context management: how much history does each agent need? Three strategies:
- Full history: pass the entire conversation history to each agent. Maximally informative but expensive; context windows fill quickly.
- Summary: a summarizer agent condenses prior exchanges into a compact summary. Efficient but lossy; important details may be dropped.
- Relevant excerpt: retrieve only the most relevant prior messages using semantic search. Balances cost and informativeness; requires a retrieval mechanism.
Role Design and Specialization
The design of agent roles—their capabilities, personas, and responsibilities—is as much an art as a science. Well-designed roles enable specialization; poorly designed roles create confusion and redundancy.
Defining Agent Roles
Common roles in LLM multi-agent systems:
| Role | Primary Capability | Typical Tools |
|---|---|---|
| Researcher | Information gathering, synthesis | Web search, RAG, databases |
| Planner | Task decomposition, scheduling | None (reasoning only) |
| Coder | Code generation, debugging | Code interpreter, linter |
| Reviewer | Quality assessment, critique | None (reasoning only) |
| Tester | Test generation, execution | Test runner, coverage tools |
| Writer | Prose generation, editing | Grammar checker, style guide |
| Critic | Adversarial evaluation | None (reasoning only) |
| Orchestrator | Coordination, delegation | All agent interfaces |
Table 25.2:Common agent roles in LLM multi-agent systems.
Capability-Based vs. Role-Based Assignment
Two philosophies for task assignment:
- Role-based: tasks are assigned based on predefined role labels. Simple and predictable; may be suboptimal when a task spans multiple roles.
- Capability-based: tasks are assigned based on a dynamic assessment of each agent’s capabilities relative to the task requirements. More flexible; requires a capability registry and matching mechanism.
Dynamic Role Reassignment
In long-running systems, static role assignments become suboptimal. Dynamic reassignment allows agents to take on new roles based on:
- Current workload (load balancing)
- Demonstrated performance on recent tasks
- Changing task requirements
- Agent failures requiring coverage
Persona Design for Diversity of Thought
A subtle but powerful technique: give agents distinct personas that encourage diverse perspectives. Rather than five identical “assistant” agents, design:
- An optimist who emphasizes opportunities
- A skeptic who challenges assumptions
- A pragmatist who focuses on implementation
- A visionary who thinks long-term
- A devil’s advocate who argues the opposite position
This diversity of thought, inspired by techniques like Six Thinking Hats [28], reduces groupthink and produces more robust collective reasoning.
Multi-Agent Patterns for LLMs
Beyond architectural topologies, several interaction patterns have proven particularly effective for LLM-based multi-agent systems. (These complement the single-agent design patterns in Chapter Chapter 20 Agent Design Patterns.)
Debate Pattern
Multiple agents argue for different positions; a judge agent evaluates the arguments and decides. Debate has been shown to improve factual accuracy and reduce hallucinations [78].
async def debate_round(question: str, agents: list, judge: Agent,
                       rounds: int = 2) -> str:
    """Run a multi-agent debate and return the judge's verdict."""
    positions = {a.name: await a.generate_position(question)
                 for a in agents}

    for round_num in range(rounds):
        # Each agent sees others' positions and can rebut
        rebuttals = {}
        for agent in agents:
            others = {k: v for k, v in positions.items()
                      if k != agent.name}
            rebuttals[agent.name] = await agent.rebut(
                question, positions[agent.name], others
            )
        positions = rebuttals

    # Judge evaluates all final positions
    verdict = await judge.evaluate(question, positions)
    return verdict
Listing 36:Debate pattern implementation
Reflection Pattern
One agent generates an output; a second agent critiques it; the first agent revises based on the critique. This implements a generate-critique-revise loop that iteratively improves quality.
async def reflection_loop(task: str, generator: Agent,
                          critic: Agent, max_rounds: int = 3) -> str:
    draft = await generator.generate(task)

    for _ in range(max_rounds):
        critique = await critic.critique(task, draft)
        if critique.is_satisfactory:
            break
        draft = await generator.revise(task, draft, critique.feedback)

    return draft
Listing 37:Reflection pattern
Division of Labor Pattern
The task is decomposed into independent sub-tasks executed in parallel. Results are aggregated by a synthesis agent. This pattern maximizes throughput for embarrassingly parallel tasks.
Pipeline Pattern
Agents form a sequential processing chain: each agent transforms the output of the previous agent. Analogous to Unix pipes. Effective for tasks with clear sequential dependencies (e.g., research outline draft edit format).
Ensemble Pattern
Multiple agents independently solve the same problem; a selection mechanism picks the best answer (best-of-) or aggregates answers (mixture-of-experts style). Improves reliability at the cost of compute.
where score can be a reward model, a judge LLM, or a verifier.
Teacher-Student Pattern
A more capable agent (teacher) guides a less capable agent (student) through a task, providing hints, corrections, and explanations. This pattern enables knowledge distillation at inference time and can be used to fine-tune the student agent.
Red Team Pattern
An adversarial agent (red team) actively tries to find weaknesses, errors, or safety violations in the outputs of other agents. The red team agent is prompted to be maximally critical and creative in its attacks. This pattern is essential for safety-critical applications.
Training Multi-Agent Systems with Reinforcement Learning
Training multi-agent systems with RL introduces challenges that go beyond single-agent RL. The fundamental difficulty is that each agent’s environment includes other learning agents, making the environment non-stationary from any single agent’s perspective.
Mathematical Formulation
A multi-agent system is formalized as a Markov Game (also called a stochastic game) [324]:
where is the set of agents, is the shared state space, is agent ’s action space, is the transition function, is agent ’s reward function, and is the discount factor.
Each agent seeks to maximize its expected discounted return:
Independent Learning
The simplest approach: each agent treats other agents as part of its environment and optimizes its own policy independently using standard single-agent RL (e.g., PPO, REINFORCE).
Centralized Training, Decentralized Execution (CTDE)
CTDE [240, 306] is the dominant paradigm for cooperative multi-agent RL. During training, a centralized critic has access to the global state and all agents’ actions . During execution, each agent acts using only its local observation .
The centralized critic for agent :
The decentralized actor for agent :
The policy gradient with centralized critic:
CTDE resolves non-stationarity during training (the centralized critic sees the full joint state) while preserving decentralized execution (no communication required at inference time).
Communication Learning
Rather than using fixed communication protocols, agents can learn what to communicate. In differentiable communication frameworks [342, 66], agents produce continuous communication vectors that are passed to other agents:
The communication vectors are optimized end-to-end via backpropagation through the joint reward signal. For LLM agents, this is approximated by training agents to produce structured natural language messages that maximize task performance.
Emergent Communication
When agents are trained from scratch with only a reward signal (no predefined language), they can develop emergent communication protocols[200]: shared symbol systems that encode task-relevant information. While fascinating scientifically, emergent communication in LLM systems is typically undesirable—we want agents to communicate in human-interpretable language.
Self-Play
In competitive or mixed-motive settings, self-play[332] trains agents by having them compete against copies of themselves. This generates an automatic curriculum: as the agent improves, its opponent (a previous version of itself) becomes harder to beat.
For LLM agents, self-play is used in:
- Red team vs. blue team training
- Debate training (agents argue against each other)
- Negotiation training (agents negotiate with each other)
Population-Based Training
Population-Based Training (PBT)[158] maintains a diverse population of agents with different policies, hyperparameters, and specializations. Agents are periodically evaluated; underperforming agents are replaced by mutated copies of high-performing agents.
For multi-agent LLM systems, PBT enables:
- Automatic discovery of effective role specializations
- Robustness to individual agent failures (diverse population)
- Avoidance of local optima through population diversity
Social Welfare and Nash Equilibrium
In multi-agent settings, the notion of optimality is more complex than in single-agent settings. Two key solution concepts:
Nash Equilibrium: a joint policy such that no agent can improve its expected return by unilaterally deviating:
where denotes the joint policy of all agents except .
Social Welfare Maximization: optimize the sum of all agents’ returns:
In fully cooperative settings (all agents share the same reward), social welfare maximization is the appropriate objective. In competitive settings, Nash equilibrium is the relevant solution concept. Most real-world multi-agent LLM systems are mixed-motive: agents have partially aligned, partially conflicting objectives.
Challenges and Solutions
Coordination Overhead
Every inter-agent message consumes tokens—and therefore time and money. In a naive implementation, agents communicate constantly, even when unnecessary.
Quantifying communication cost: if a message costs tokens and the receiving agent’s task has value , communicate only if the expected improvement in task value .
Redundancy vs. Efficiency
Multiple agents may independently solve the same sub-problem, wasting compute. Solutions:
- Duplicate detection: before starting a task, check the blackboard for existing results
- Result caching: store completed sub-task results with semantic keys for retrieval
- Task locking: mark tasks as “in progress” to prevent duplicate execution
Attribution
When a multi-agent system succeeds or fails, which agent is responsible? Attribution is critical for:
- RL reward assignment (credit assignment problem)
- Debugging and improvement
- Trust calibration (which agents to rely on)
The counterfactual credit assignment approach estimates each agent’s contribution by asking: “How much would the outcome have changed if this agent had acted differently?”
Scalability
Naive message passing scales as with the number of agents. Solutions:
- Hierarchical communication: agents communicate only within their subtree
- Topic-based pub/sub: agents subscribe only to relevant message topics
- Sparse communication graphs: only connect agents that need to interact
- Asynchronous communication: agents don’t block waiting for responses
Emergent Behavior and Safety
Multi-agent systems can exhibit unexpected emergent behaviors—interactions between agents that produce outcomes no individual agent was designed to produce. This is both a feature (emergent capabilities) and a risk (emergent failures).
Evaluation
Evaluating multi-agent systems requires metrics at multiple levels:
| Level | Metric | Example |
|---|---|---|
| System | Task completion rate | % of tasks completed correctly |
| System | End-to-end latency | Time from task to final output |
| System | Total token cost | Tokens consumed across all agents |
| Agent | Individual accuracy | Per-agent task success rate |
| Agent | Communication efficiency | Useful messages / total messages |
| Agent | Contribution score | Counterfactual credit (Eq. ) |
| Emergent | Coordination quality | Degree of task overlap / gaps |
Table 25.3:Multi-level evaluation metrics for multi-agent systems.
Real-World Multi-Agent Applications
Software Development Team
A multi-agent software development team mirrors a real engineering organization:
from dataclasses import dataclass
from typing import Optional
import asyncio

@dataclass
class SoftwareTeamState:
    requirements: str
    architecture: Optional[str] = None
    code: Optional[str] = None
    tests: Optional[str] = None
    review_feedback: Optional[str] = None
    final_code: Optional[str] = None
    approved: bool = False

class SoftwareDevelopmentTeam:
    """
    Multi-agent software team:
      Architect -> Coder -> Tester -> Reviewer -> (iterate or ship)
    """

    def __init__(self, llm_factory):
        self.architect = llm_factory(
            system_prompt="""You are a software architect. Given requirements,
            produce a clear technical design: components, interfaces, data
            structures, and implementation plan."""
        )
        self.coder = llm_factory(
            system_prompt="""You are an expert software engineer. Given a
            technical design, write clean, well-documented, production-ready
            code. Follow best practices for the language."""
        )
        self.tester = llm_factory(
            system_prompt="""You are a QA engineer. Given code, write
            comprehensive tests: unit tests, edge cases, integration tests.
            Identify potential bugs and failure modes."""
        )
        self.reviewer = llm_factory(
            system_prompt="""You are a senior code reviewer. Evaluate code
            for correctness, security, performance, and maintainability.
            Provide specific, actionable feedback. Approve only if excellent."""
        )

    async def build(self, requirements: str,
                    max_iterations: int = 3) -> SoftwareTeamState:
        state = SoftwareTeamState(requirements=requirements)

        # Phase 1: Architecture
        state.architecture = await self.architect.invoke(
            f"Requirements:\n{requirements}\n\nProduce technical design."
        )

        for iteration in range(max_iterations):
            # Phase 2: Implementation
            prompt = (f"Design:\n{state.architecture}\n\n"
                      + (f"Previous feedback:\n{state.review_feedback}\n\n"
                         if state.review_feedback else "")
                      + "Write the implementation.")
            state.code = await self.coder.invoke(prompt)

            # Phase 3: Testing
            state.tests = await self.tester.invoke(
                f"Code:\n{state.code}\n\nWrite comprehensive tests."
            )

            # Phase 4: Review
            review = await self.reviewer.invoke(
                f"Code:\n{state.code}\n\nTests:\n{state.tests}\n\n"
                "Review this code. End with APPROVED or NEEDS_REVISION."
            )

            if "APPROVED" in review:
                state.final_code = state.code
                state.approved = True
                break
            else:
                state.review_feedback = review

        return state

    async def run(self, requirements: str) -> str:
        state = await self.build(requirements)
        if state.approved:
            return f"# Final Implementation\n\n{state.final_code}"
        else:
            return f"# Best Attempt (not approved)\n\n{state.code}"
Research Team
A research team agent society mirrors academic collaboration:
- Literature Reviewer: searches and synthesizes existing work
- Hypothesis Generator: proposes novel research directions
- Experimentalist: designs and runs experiments (via code execution)
- Statistician: analyzes results and assesses significance
- Writer: synthesizes findings into a coherent report
Customer Service System
A tiered customer service system:
- Router: classifies incoming requests and routes to specialists
- Billing Specialist: handles payment and account issues
- Technical Specialist: resolves product/service issues
- Escalation Agent: handles complex cases requiring human judgment
Creative Team
A creative production pipeline:
- Brainstormer: generates diverse ideas without self-censorship
- Drafter: develops the most promising ideas into full drafts
- Editor: refines drafts for clarity, style, and coherence
- Critic: provides adversarial feedback to strengthen the work
Architecture Comparison
| Architecture | Scalability | Debug | Coord. Cost | Fault Tol. | Best For |
|---|---|---|---|---|---|
| Centralized (Supervisor) | M | H | L | L | Simple pipelines; clear task decomposition; small teams |
| Decentralized (P2P) | H | L | H | H | Dynamic environments; resilience-critical; large-scale |
| Hierarchical | H | M | M | M | Enterprise workflows; complex multi-domain tasks |
| Swarm | H | L | L | H | Customer service routing; simple handoff chains |
| Pipeline | M | H | L | L | Sequential processing; clear stage dependencies |
| Ensemble | L | H | H | H | High-stakes decisions; reliability over efficiency |
Table 25.4:Multi-agent architecture patterns compared across key dimensions. Ratings: High / Medium / Low.
Self-Evolving Agents: BDI Meets LLMs
A May 2026 line of research [427] represents the first serious attempt to combine Belief-Desire-Intention (BDI) architectures—the classical framework for rational agents in multi-agent systems—with LLMs. Unlike static agents that execute fixed tool-call sequences, BDI-LLM agents autonomously modify their own goals and rewrite their underlying code based on environmental feedback:
- Beliefs: The LLM maintains and updates a structured world model (beliefs about file states, API responses, user intent)
- Desires: High-level goals that can be dynamically reprioritized based on observed outcomes
- Intentions: Concrete plans (code + tool sequences) that the agent can rewrite when a plan fails
Summary
Multi-agent systems represent a fundamental shift in how we deploy LLMs: from isolated assistants to collaborative societies of specialized agents. The key insights from this section:
The field of multi-agent LLM systems is evolving rapidly. The patterns and techniques described here represent the current state of the art, but new architectures, coordination mechanisms, and training algorithms are emerging continuously. The foundational principles—specialization, coordination, emergent behavior, and the tension between efficiency and robustness—will remain relevant regardless of how the specific implementations evolve.