
This section covers the foundational architecture of large language models and the key optimization techniques that make training and inference efficient. Topics are ordered as a curriculum: we begin with the transformer itself, then cover how to train it efficiently, how to adapt it cheaply, how to compress it, how to scale it, and how to accelerate its inference.
How LLMs Work: An Intuitive Overview
Before diving into architectural details, let us build intuition for how a large language model transforms text into text. The entire process follows a simple pipeline: text tokens representations tokens text.
Tokenization
Tokenization is the critical first step that converts raw text into the discrete symbols a language model operates on. The choice of tokenizer directly affects model quality, multilingual capability, and computational efficiency.
Why Not Characters or Words?
| Granularity | Vocab Size | Seq Length | Issues |
|---|---|---|---|
| Character | 256 | Very long | Attention cost ; hard to learn long-range semantics |
| Word | 500K+ | Short | Cannot handle rare/novel words; huge embedding table |
| Subword | 32K–128K | Moderate | Best trade-off: short sequences, open vocabulary |
Table 1.1:Trade-offs of different tokenization granularities.
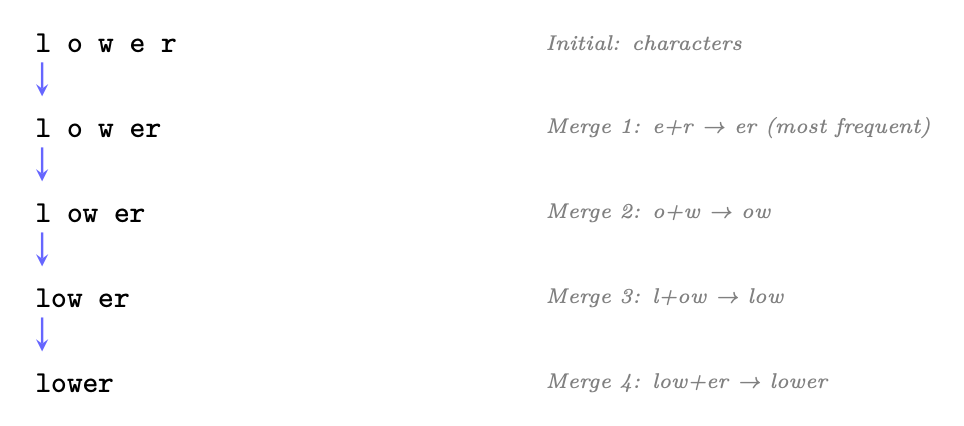
Byte-Pair Encoding (BPE)
BPE [320] is the dominant tokenization algorithm used by GPT, Llama, Mistral, and most modern LLMs.
Other Tokenization Methods
| Method | Used By | Key Idea |
|---|---|---|
| BPE | GPT-4 [274], Llama-3 [118], Mistral [165] | Bottom-up merging of frequent pairs; deterministic |
| WordPiece | BERT [76], DistilBERT [312] | Similar to BPE but maximizes likelihood of training data |
| Unigram LM | SentencePiece (T5 [303], XLNet [405]) | Top-down: start with large vocab, prune by likelihood impact |
| Byte-level BPE | GPT-2 [301]+ | BPE on raw bytes (no unknown tokens possible); 256 base vocab |
Table 1.2:Comparison of subword tokenization algorithms.
Tokenization Best Practices
- Vocabulary size matters: 32K is minimal; 128K enables better multilingual coverage and code handling. Llama-3 uses 128K tokens.
- Special tokens: Always include
<bos>,<eos>,<pad>,<unk>. For instruction-tuned models, add role markers (<|user|>,<|assistant|>). - Fertility: Measure tokens-per-word across languages. High fertility (many tokens per word) indicates poor coverage for that language.
- Never tokenize across boundaries: Spaces, punctuation, and digits should be handled consistently. Most modern tokenizers prepend a space marker (“the”) to distinguish word-initial vs. continuation tokens.
- Numbers: Consider digit-level tokenization for arithmetic tasks. “2024” as [“2”,“0”,“2”,“4”] enables digit-by-digit reasoning.
- Code: Ensure whitespace (indentation) is tokenized efficiently. Llama-3 tokenizes runs of spaces as single tokens.
Tokenization in Practice: HuggingFace Example
The transformers library provides a unified interface for all tokenizers. The following demonstrates encoding and decoding with a modern LLM tokenizer:
from transformers import AutoTokenizer

# Load Llama-3 tokenizer (128K vocabulary, byte-level BPE)
tokenizer = AutoTokenizer.from_pretrained("meta-llama/Meta-Llama-3-8B")

text = "Reinforcement learning optimizes long-term rewards."

# Encode: text -> token IDs
token_ids = tokenizer.encode(text)
print(token_ids)
# [128000, 29934, 262, 11008, 4815, 6900, 1317, 9860, 21845, 13]

# Decode individual tokens to see subword splits
tokens = tokenizer.convert_ids_to_tokens(token_ids)
print(tokens)
# ['<|begin_of_text|>', 'Re', 'inforce', 'ment', ' learning',
#  ' optimizes', ' long', '-term', ' rewards', '.']

# Decode back to text (round-trip)
reconstructed = tokenizer.decode(token_ids, skip_special_tokens=True)
assert reconstructed == text  # Perfect reconstruction

# Tokenize with attention mask (for batched inputs with padding)
batch = tokenizer(
    ["Short text.", "A much longer input sentence for comparison."],
    padding=True, return_tensors="pt"
)
print(batch.keys())  # dict_keys(['input_ids', 'attention_mask'])
Listing 1:Tokenization encode/decode with HuggingFace Transformers.
Special Tokens and Structured Prompts
Special tokens are reserved vocabulary entries that carry structural meaning rather than linguistic content. They are critical for controlling model behavior.
| Token | Alias | Purpose |
|---|---|---|
| <bos> / <|begin_of_text|> | BOS | Marks start of sequence |
| <eos> / <|end_of_text|> | EOS | Marks end of sequence; stops generation |
| <|user|> | — | Marks start of user turn in chat |
| <|assistant|> | — | Marks start of assistant turn in chat |
| <pad> | PAD | Fills batch to uniform length; masked in attention |
| <unk> | UNK | Out-of-vocabulary placeholder (rare with BPE) |
| [SEP] | SEP | Separates segments (BERT-style) |
| [CLS] | CLS | Classification token (BERT) |
| [MASK] | MASK | Masked token for MLM pretraining |
Table 1.3:Common special tokens across LLM families.
Modern chat models use special tokens to delineate conversational structure. These are not trained to carry semantic meaning—they are structural delimiters that the model learns to parse:
# Llama-3 chat template
messages = [
    {"role": "system", "content": "You are a helpful assistant."},
    {"role": "user", "content": "Explain PPO in one sentence."},
]

# apply_chat_template handles all special token insertion
prompt = tokenizer.apply_chat_template(messages, tokenize=False)
print(prompt)
# <|begin_of_text|><|start_header_id|>system<|end_header_id|>
#
# You are a helpful assistant.<|eot_id|><|start_header_id|>user<|end_header_id|>
#
# Explain PPO in one sentence.<|eot_id|><|start_header_id|>assistant<|end_header_id|>
#
#
Listing 2:Chat template with special tokens (Llama-3 format).
The Transformer Architecture
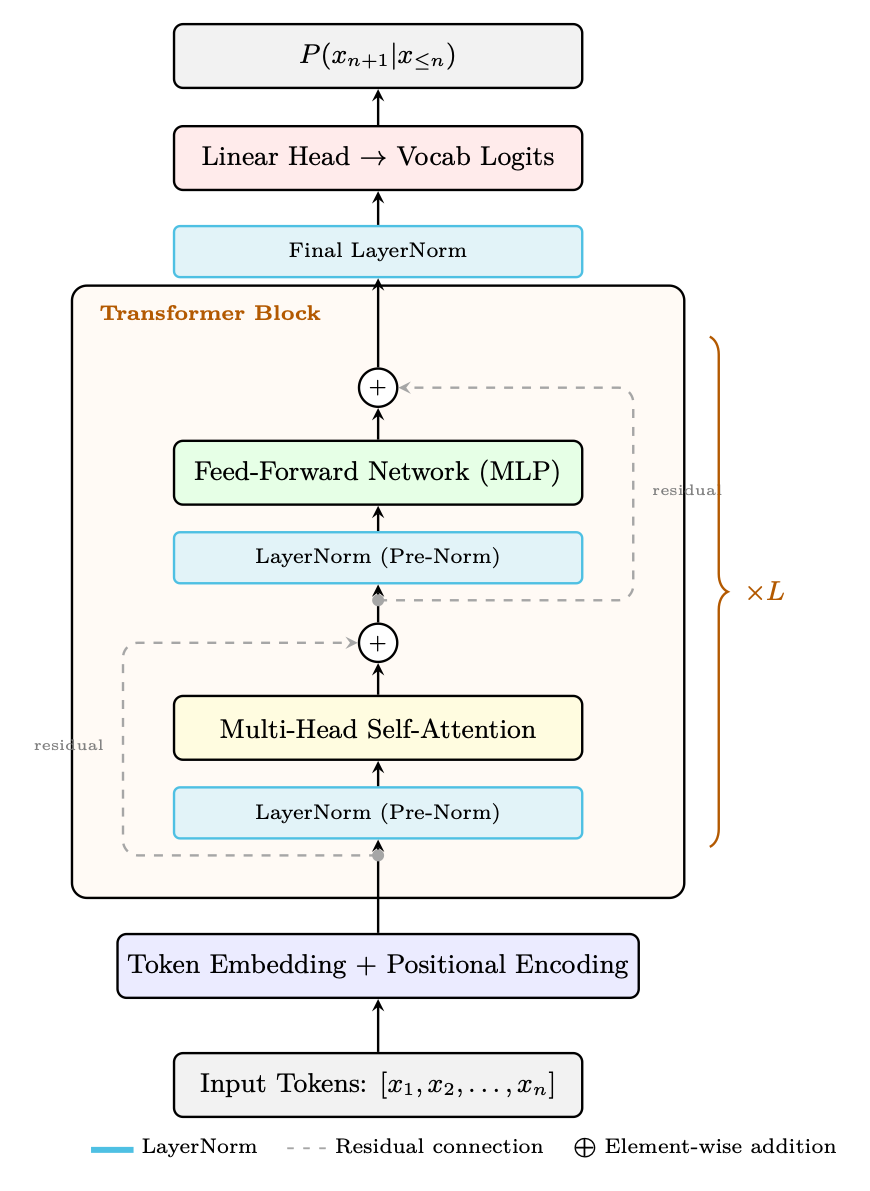
The Transformer [357] is the foundation of all modern LLMs. Understanding its components is essential for grasping every optimization and training method in this guide.
High-Level Structure
A decoder-only transformer processes tokens sequentially through embedding, repeated attention+FFN blocks, and a final projection to vocabulary logits. Figure 图 1.3 shows the complete architecture.
The Original Encoder-Decoder Transformer
The Transformer was originally introduced [357] as an encoder-decoder architecture for sequence-to-sequence tasks (machine translation, summarization). While modern LLMs predominantly use decoder-only variants (GPT-style), understanding the full architecture is essential because cross-attention and masked self-attention — both originating here — remain fundamental building blocks.
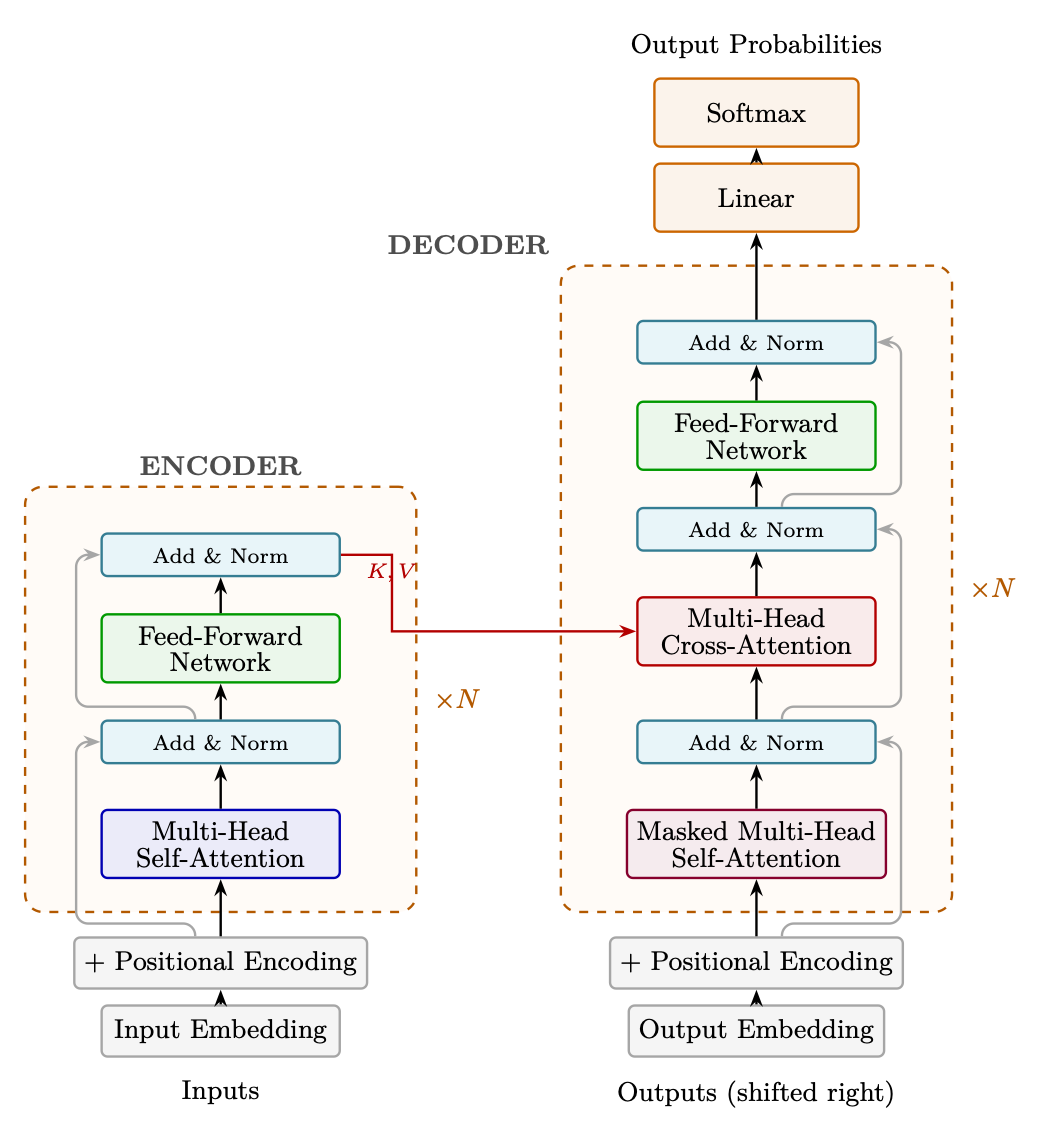
The encoder processes the entire input sequence bidirectionally — each token attends to all other tokens (no causal mask). This produces a rich contextual representation where each position encodes information about the full input:
- Input: Token embeddings + sinusoidal positional encodings
- Each layer: Multi-Head Self-Attention Add & Norm FFN Add & Norm
- No causal mask: Position attends to all positions
- Output: Contextual representations of the full input sequence
The decoder generates output tokens one at a time (autoregressively). To prevent the model from “seeing the future,” the self-attention in the decoder uses a causal mask:
where the mask is:
After masked self-attention, each decoder layer applies cross-attention where the decoder attends to the encoder’s output representations. This is the mechanism by which the decoder “reads” the input:
- Queries come from the decoder’s previous sublayer (the masked self-attention output)
- Keys and Values come from the encoder’s final output
- No mask is applied — every decoder position can attend to every encoder position
- This allows the decoder to dynamically focus on different parts of the input at each generation step (e.g., attending to “cat” when translating to “gato” in EnglishSpanish)
Each decoder layer contains three sublayers (vs. two in the encoder):
- Masked Multi-Head Self-Attention + Residual + LayerNorm
- Multi-Head Cross-Attention (to encoder output) + Residual + LayerNorm
- Feed-Forward Network + Residual + LayerNorm
Modern LLMs (GPT, Llama, Qwen) use only the decoder, removing both the encoder and cross-attention layers entirely. The key insight: for generative language modeling, a single causal (masked) self-attention stack is sufficient — the model learns to encode context and generate continuations in a single pass. This simplifies architecture, training, and inference while scaling more effectively. Encoder-decoder models (T5, BART) remain relevant for tasks with distinct input/output structure (translation, summarization), and cross-attention reappears in multimodal models where vision encoders provide keys/values to language decoders.
Decoder-Only vs Encoder-Decoder
Modern LLMs almost exclusively use decoder-only architectures, but understanding the trade-offs with encoder-decoder designs clarifies why.
ArchitectureExamplesUse CaseDecoder-onlyGPT-4 [274], Llama [118], Mistral [165], Qwen [350]Autoregressive generation; dominant for chat/reasoningEncoder-decoderT5 [303], BART [207], Flan-T5 [59]Seq2seq (translation, summarization); less common nowEncoder-onlyBERT [76], RoBERTa [234]Classification/embeddings; not for generation
Embeddings: From Discrete Tokens to Continuous Space
Before any attention or computation happens, the transformer must convert discrete token IDs into continuous vectors that neural networks can process. This is the role of the embedding layer.
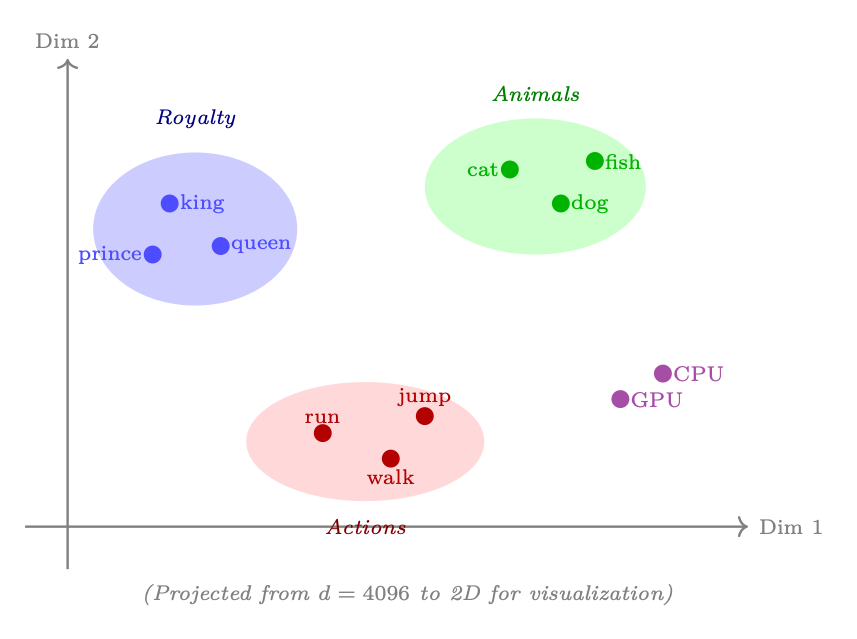
An embedding is a learned dense vector representation of a discrete symbol. Instead of representing the word “king” as a one-hot vector of size (mostly zeros), we represent it as a compact vector in (e.g., ) that captures its meaning.
The key insight: similar concepts get nearby vectors. In a well-trained embedding space:
- “king” and “queen” are close (both royalty)
- “king” and “bicycle” are far apart (unrelated)
- Vector arithmetic captures relationships:
In practice, the embedding layer is simply a matrix where row stores the embedding vector for token :
For a sequence of token IDs , embedding is a simple table lookup (indexing operation):
A critical issue arises when using pretrained embeddings (e.g., from BERT or GPT-2) for downstream tasks like retrieval (RAG) or bootstrapping recommender systems: the learned representations are highly anisotropic—they occupy a narrow cone in the embedding space rather than being uniformly distributed across all directions [87].
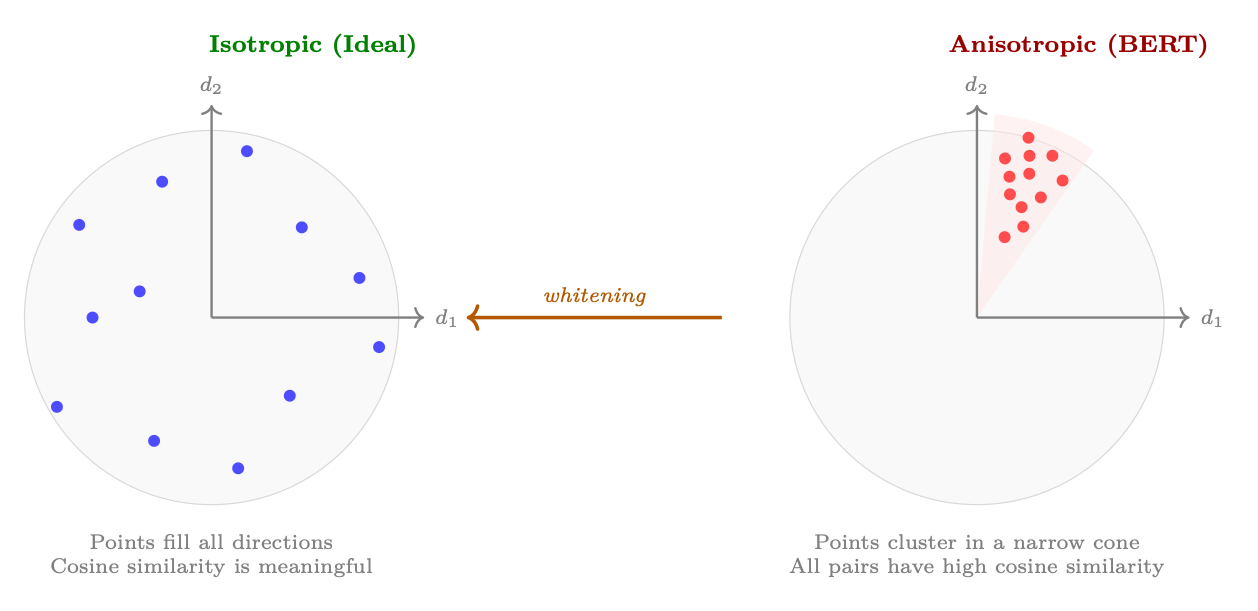
Why this matters for applications:
- RAG / Retrieval: If all embeddings have cosine similarity regardless of content, retrieval rankings become nearly random—the system cannot distinguish relevant from irrelevant passages.
- Recommender systems: Using pretrained LLM embeddings to represent items/users only works if the geometry preserves meaningful similarity structure.
- Clustering: Anisotropic embeddings collapse clusters, making it impossible to discover natural groupings.
A simple and effective fix is whitening[341]—a linear transformation that makes the embedding distribution isotropic (zero mean, identity covariance):
where is the mean embedding, and is the eigendecomposition of the covariance matrix .
Self-Attention Mechanism
Self-attention is the core operation that allows each token to attend to every other token in the sequence, computing a weighted combination based on relevance.
The naive attention computation has quadratic cost in sequence length:
- Time: — computing requires dot products, each of dimension .
- Memory: — the full attention matrix must be materialized to apply softmax.
For a 128K-token context with , the attention matrix alone is billion entries (64 GB in FP32). This quadratic scaling is the fundamental bottleneck for long-context LLMs.
| Seq Length | Attention Ops | Matrix Size | Practical Impact |
|---|---|---|---|
| 2K | 4M | 16 MB | Fast; fits in SRAM |
| 8K | 64M | 256 MB | Manageable with FlashAttention |
| 32K | 1B | 4 GB | Requires memory-efficient kernels |
| 128K | 16B | 64 GB | Exceeds single GPU HBM |
| 1M | 1T | 4 TB | Impossible without sub-quadratic methods |
Table 1.4:Attention cost scaling: why naive implementation is prohibitive for long sequences.
Several families of solutions address this quadratic bottleneck:
- Exact attention with IO-awareness (FlashAttention [64]): Does not reduce computational complexity but eliminates the need to materialize the matrix in HBM by computing attention in tiles that fit in SRAM. Crucially, FlashAttention is orthogonal to the sparse patterns below—it is an execution engine, not an attention pattern. Production systems routinely combine FlashAttention with sliding windows or block-sparse masks, getting both IO efficiency and reduced FLOPs. We cover the algorithm in detail in Section 1.6 Flash Attention – Algorithm and Hardware Awareness.
- Sliding window / local attention: Each token only attends to the nearest tokens (e.g., ). Cost becomes —linear in . Used by Mistral [165] (window ) and Longformer [23]. Trades global context for efficiency; works well because most attention is local in practice. In modern stacks, the sliding-window mask is executed inside a FlashAttention kernel.
- Sparse attention patterns: Combine local windows with periodic global tokens (e.g., every 512th token attends to all). BigBird [416] and LongT5 [125] use this. Preserves some long-range connectivity at cost. Again, FlashAttention serves as the underlying kernel for the non-zero attention blocks.
- Linear attention / state-space models: Replace with using associativity, or reformulate as a recurrence (Mamba [122], RWKV [288]). Theoretically total. Unlike approaches 2–3 above, these are architectural replacements that alter model expressiveness—softmax-free attention is fundamentally less expressive, and empirically these models still lag behind transformers on tasks requiring precise long-range retrieval or complex reasoning.
- KV cache compression: At inference, compress or evict old KV pairs to bound memory. Techniques include: H2O [429] (heavy-hitter oracle—keep only high-attention keys), StreamingLLM [394] (keep initial “attention sink” tokens + recent window), and quantized KV caches [238].
Multi-Head Attention
Rather than computing a single attention function, multi-head attention runs several attention operations in parallel, each learning to focus on different aspects of the input (syntax, semantics, position, etc.).
DeepSeek-V2 [70] introduced a more aggressive compression: instead of sharing KV heads (as in GQA), MLA compresses all key-value information into a single low-rank latent vector per token:
where with . The KV cache stores only —smaller than even GQA—while decompression matrices reconstruct full keys and values on-the-fly. Because the compression is learned end-to-end, quality matches or exceeds GQA. MLA enables DeepSeek’s subsequent Sparse Attention for sub-quadratic long-context scaling and is now the basis of the DeepSeek-V3/V4 architecture family.
Positional Encodings
Transformers are permutation-equivariant by construction — without positional information, the model cannot distinguish “the cat sat on the mat” from “mat the on sat cat the”. Positional encodings inject sequence-order signal so that attention can reason about token distance and direction.
| Method | Used By | Key Idea |
|---|---|---|
| Sinusoidal | Original Transformer | Fixed at different frequencies. Not learned. |
| Learned Absolute | GPT-2 [301], BERT [76] | Learned embedding per position. Limited to training length. |
| RoPE (Rotary) | Llama [118], Qwen [350], Mistral [165] | Rotate Q,K vectors by position-dependent angle. Extrapolates via NTK-aware scaling. |
| ALiBi | BLOOM [383], MPT [260] | No position embedding; add linear bias to attention scores. Simple, extrapolates well. |
Table 1.5:Positional encoding methods in modern LLMs.
Introduced in the original Transformer [357], this method uses fixed sinusoidal functions at geometrically-spaced frequencies:
where is the token position, is the dimension index, and is the model dimension.
Motivation: Each frequency encodes position at a different scale (analogous to binary counting). The authors hypothesised that the model could learn to attend to relative positions because can be expressed as a linear function of .
Pros: Zero learned parameters; deterministic; theoretically supports arbitrary lengths.
Cons: In practice, does not extrapolate well beyond training lengths; the model must learn to decode relative position from absolute signals indirectly; largely superseded.
Used by GPT-2 [301] and BERT [76]: a learnable embedding matrix is added to token embeddings:
Motivation: Let the model learn whatever positional representation is optimal for the task, rather than imposing a fixed structure.
Pros: Maximum flexibility; simple implementation; often outperforms sinusoidal for short sequences.
Cons: Hard-coded maximum length ; no generalisation beyond it; embeddings near the end of are under-trained; adds parameters.
RoPE [340] encodes position by rotating query and key vectors in 2D subspaces:
where and is the position index. The key property is that the dot product between rotated queries and keys depends only on relative position:
Motivation: Achieve relative position encoding without explicit bias terms, while maintaining compatibility with linear attention and KV-caching.
Pros: Naturally relative; no extra parameters; compatible with efficient inference; can be extended to longer contexts via NTK-aware scaling [289] or YaRN (adjusting base or interpolating frequencies).
Cons: Slightly more compute per attention operation (rotation + interleaving); extrapolation requires explicit scaling strategies; rotation in 2D subspaces imposes structure that may not be optimal for all tasks.
ALiBi [292] takes a radically different approach: no positional embedding at all. Instead, a static linear penalty is subtracted from attention scores:
where is a head-specific slope (set geometrically: for head of total). The bias creates a soft local attention window whose width varies by head.
Motivation: Position should bias attention toward nearby tokens (recency prior) without interfering with the embedding space. By operating purely in attention-score space, ALiBi avoids polluting token representations with positional signal.
Pros: Excellent length extrapolation (trained at 1k, works at 8k+); zero parameters; trivial to implement; head-specific slopes give multi-scale locality.
Cons: Less expressive for tasks requiring precise long-range positional reasoning (e.g. “what was the 5th word?”); the linear decay is a strong inductive bias that may not suit all domains; largely overtaken by RoPE in recent models due to RoPE’s better short-context performance.
| Sinusoidal | Learned Abs. | RoPE | ALiBi | |
|---|---|---|---|---|
| Extra parameters | None | None | None | |
| Position type | Absolute | Absolute | Relative | Relative (implicit) |
| Length extrapolation | Poor | None | Good (w/ scaling) | Excellent |
| Compute overhead | Negligible | Negligible | Small | Negligible |
| Dominant era | 2017–19 | 2018–20 | 2022–present | 2022–23 |
Table 1.6:Positional encoding comparison: practical trade-offs.
Modern frontier models (Claude [11] with 200K–1M context, Gemini 1.5 [108] at 1M+, GPT-4 [274] at 128K) require positional encodings that remain faithful far beyond training lengths. The dominant solutions today:
- RoPE with frequency scaling: The standard approach for extending RoPE beyond training length. Rather than retraining, the base frequency is rescaled:Variants include:•Linear scaling (Position Interpolation) [48]: Simply divide position indices by a factor . Cheap but degrades quality at high extension ratios.•NTK-aware scaling[289]: Scale the base frequency . Preserves high-frequency (local) information while extending low-frequency (global) range.•YaRN[289] (Yet another RoPE extensioN): Combines NTK scaling with an attention temperature correction and fine-tuning on a small long-context corpus. Used by Llama-3 to extend from 8K training to 128K deployment.•Dynamic NTK[289]: Adjusts the scaling factor on-the-fly based on actual sequence length at inference. No fixed extension ratio needed—the model adapts as context grows.
- Continued pretraining on long data: Even with RoPE scaling, models benefit from a short continued pretraining phase (1–5B tokens) on long documents. This teaches the model to actually use distant context, not just tolerate it positionally. Llama-3.1 used a progressive schedule: 8K 64K 128K.
- Ring Attention / Blockwise Parallel[222]: For sequences exceeding single-GPU memory (1M+ tokens), Ring Attention distributes the sequence across GPUs in a ring topology. Each GPU holds a block and passes KV blocks around the ring, computing local attention tiles. This enables linear memory scaling with GPU count while preserving exact attention.
- Hybrid architectures: Some systems combine a local sliding window (e.g., 4K) for most layers with full attention at select layers (e.g., every 4th layer). This provides cost for most computation while maintaining global information flow.
Feed-Forward Network (MLP)
Each transformer block contains an MLP applied independently to each position:
where , . Modern LLMs use:
- SwiGLU activation: — used by Llama [118], Mistral [165]. Requires 3 weight matrices but gives better performance.
- Hidden dimension is typically (rounded to multiples of 256 for Tensor Core efficiency).
Layer Normalization
Layer normalization stabilizes training by normalizing activations across the feature dimension. Its placement relative to the attention/FFN sublayers significantly affects training dynamics.
Given a hidden state vector (a single token’s representation), LayerNorm [15] computes:
where:
- (mean across the feature dimensions)
- (variance across features)
- are learned scale and shift parameters (per-dimension)
- prevents division by zero
Key distinction from BatchNorm: LayerNorm normalizes across the feature dimension of a single example, not across the batch. This makes it independent of batch size and works identically at training and inference.
RMSNorm [421] drops the mean-centering step, normalizing only by the root-mean-square:
No (shift) parameter and no mean subtraction — just scale. This saves one reduction operation per token and is 5–10% faster on GPUs while achieving equivalent model quality. All modern LLMs (Llama, Mistral, Qwen) use RMSNorm.
Model Size Reference
The following table summarizes key architectural parameters for widely-used open-weight models (latest versions as of 2025), providing a quick reference for understanding scale and design choices.
| Model | Params | Layers | Heads | KV Heads | Context | |
|---|---|---|---|---|---|---|
| Llama-3.1 8B [118] | 8B | 32 | 4096 | 32 | 8 | 128K |
| Llama-3.1 405B [118] | 405B | 126 | 16384 | 128 | 8 | 128K |
| Llama-4 Maverick [4] | 400B (17B active) | 48 | 5120 | 40 | 8 | 1M |
| Mistral Large 2 [5] | 123B | 88 | 12288 | 96 | 8 | 128K |
| Qwen-2.5 72B [350] | 72B | 80 | 8192 | 64 | 8 | 128K |
| DeepSeek-V3 [71] | 671B (37B active) | 61 | 7168 | 128 | MLA | 128K |
Table 1.7:Architecture parameters for popular open-weight LLMs (2024–2025 generation).
Note: Models marked with “active” parameters use Mixture-of-Experts (MoE) architecture—total parameters indicate model capacity, while active parameters reflect per-token compute cost. DeepSeek-V3 uses Multi-head Latent Attention (MLA) instead of standard GQA, compressing KV into a low-rank latent space.
Attention Pathologies
While the attention mechanism is powerful, it exhibits systematic failure modes that practitioners must understand—especially when scaling to long contexts or interpreting model behaviour.
Xiao et al. [393] discovered that transformer models allocate disproportionately high attention scores to the first token in the sequence—regardless of its semantic content. Even when the first token is a meaningless ⟨BOS⟩ marker, attention heads across all layers consistently attend to it, sometimes with 20–50% of total attention mass.
Softmax attention must produce a valid probability distribution (). When no key is particularly relevant to a query, the model needs a “dump” location for unused attention mass. During training, the first token becomes this default sink because it is always present and positionally predictable. It functions as a no-op attention target—the model has learned to route irrelevant attention there rather than distributing it unpredictably.
- Streaming inference failure: When using sliding-window KV caches, evicting the first token causes perplexity to spike catastrophically—the model loses its attention sink.
- Misleading interpretability: Naive attention visualizations suggest the first token is “important” when it is merely a mathematical artefact.
- Context window waste: The sink token occupies a KV cache slot without carrying useful information.
- StreamingLLM[393]: Always keep the first tokens (“attention sinks”) in the KV cache alongside the recent sliding window. Enables infinite-length generation with bounded memory.
- Sink tokens by design: Some models (e.g., Mistral) prepend dedicated sink tokens during training that are explicitly meant to absorb residual attention.
- Softmax alternatives: Replace softmax with ReLU attention or sigmoid gating, where zero attention is representable without requiring a dump target.
As sequence length grows, each query must distribute its attention budget across more keys. The average attention weight per token decreases as , making it progressively harder for the model to concentrate on the few truly relevant positions—a problem known as attention dilution or attention diffusion[227].
Liu et al. [227] showed that LLMs exhibit a U-shaped retrieval curve: information placed at the beginning or end of long contexts is retrieved reliably, but information in the middle is often ignored. This is a direct consequence of attention dilution compounded with positional biases from RoPE/ALiBi:
- Softmax saturation: With many keys, the softmax temperature effectively decreases, making the distribution more uniform (entropic).
- Positional decay: RoPE’s relative positional encoding introduces a natural decay with distance, suppressing attention to middle positions that are far from both start and end.
- Training distribution: Models trained on shorter sequences develop attention patterns biased toward recent context.
- Explicit retrieval: Place relevant context at the beginning or end of the prompt; use RAG to avoid relying on middle positions.
- Long-context training: Train on long documents with varied placement of key information [100].
- Hierarchical attention: Architectures like Mamba [123] or RWKV that avoid the attention bottleneck entirely.
- Landmark tokens: Insert retrievable markers in the context that act as “signposts” for attention.
- Temperature scaling: Some implementations scale the attention logits by to counteract dilution in long sequences.
| Pattern | Description | Implication |
|---|---|---|
| Attention heads specialization | Different heads learn distinct roles: syntax heads, co-reference heads, positional heads [361] | Not all heads are equally important; many can be pruned |
| Induction heads | Heads that implement [A][B]…[A] [B] copying [273] | Critical for in-context learning; emerge in 2-layer+ models |
| Attention collapse | In deep networks, attention distributions can converge (all heads attend same positions) | Hurts expressivity; addressed by attention diversity losses |
| Retrieval heads | Specific heads specialize in retrieving factual information from context [387] | Explains why pruning certain heads causes hallucination spikes |
Table 1.8:Additional attention patterns observed in large transformers.
Visualizing Attention for Explainability
Attention weights provide a window into model reasoning—but must be interpreted carefully.
The simplest approach: plot the attention matrix as a heatmap for each head and layer. Tools like BertViz [359] render interactive multi-head visualizations.
Raw attention at a single layer is misleading because information flows through residual connections across all layers. Abnar and Zuidema [2] propose attention rollout: multiply attention matrices across layers to approximate the total information flow from input to output:
where is the (averaged across heads) attention matrix at layer , adjusted to include the residual connection: .
Combine attention weights with gradient information to identify which attended tokens actually influence the output [20]:
This addresses the criticism that high attention high influence (a token can receive high attention but be processed through a near-zero-weight path).
Individual neurons in transformer MLPs and residual streams are typically polysemantic—a single neuron activates for multiple unrelated concepts (e.g., “the colour blue AND academic citations AND the word ‘the’”). This makes direct neuron-level interpretation unreliable.
Cunningham et al. [63] and Bricken et al. [30] demonstrated that training a sparse autoencoder (SAE) on model activations can decompose polysemantic representations into monosemantic features—interpretable directions that each correspond to a single concept:
where with (overcomplete basis), and the ReLU + sparsity penalty ensures only a few features activate per input.
- Features are monosemantic: each encodes a single human-interpretable concept (“code in Python,” “mentions of the Golden Gate Bridge,” “first-person narrative”) [30].
- Features are steerable: clamping a feature’s activation high/low directly controls model behaviour (e.g., forcing the “Golden Gate Bridge” feature on makes the model mention it in every response) [353].
- Features compose: complex behaviours emerge from combinations of simple features.
- SAEs scale: Templeton et al. [353] trained SAEs with up to 34M features on Claude 3 Sonnet, finding interpretable features for safety-relevant concepts (deception, sycophancy, dangerous requests).
While SAEs decompose activations into interpretable vectors, their features still require human inspection of max-activating examples to understand. Anthropic’s Natural Language Autoencoders (NLAEs) [12] take a fundamentally different approach: they replace the sparse bottleneck with natural language descriptions, making interpretability automatic.
- Encoder: A language model reads the hidden activations (or the input text) and produces a natural language description of the active concepts: e.g., “The text discusses French cuisine and uses formal academic tone.”
- Decoder: A second language model reads the natural language description and reconstructs the original activations (or predicts the next token).
- Training: Both encoder and decoder are trained end-to-end to minimize reconstruction loss, with the bottleneck being a variable-length natural language string rather than a sparse vector.
- Self-interpreting: Features are literally natural language—no manual labelling needed.
- Compositional: Can express complex, relational concepts (“a sarcastic response to a factual claim”) that SAE features cannot represent as single directions.
- Hierarchical: Descriptions can capture both fine-grained (word-level) and coarse (document-level) properties in the same representation.
- Auditable: The bottleneck description is human-readable, enabling direct inspection of what information the model “thinks” is present.
NLAEs introduce a language-model-in-the-loop, making them computationally expensive and potentially subject to the same faithfulness concerns as any model-generated explanation. They also cannot easily represent sub-symbolic features (geometric patterns, exact numerical values) that SAEs handle naturally as activation magnitudes.
Prediction Heads: What Transformers Output
The transformer body produces contextual hidden states for each position. What we do with these hidden states—the prediction head—defines the task. The same transformer backbone can serve radically different purposes simply by swapping the head.
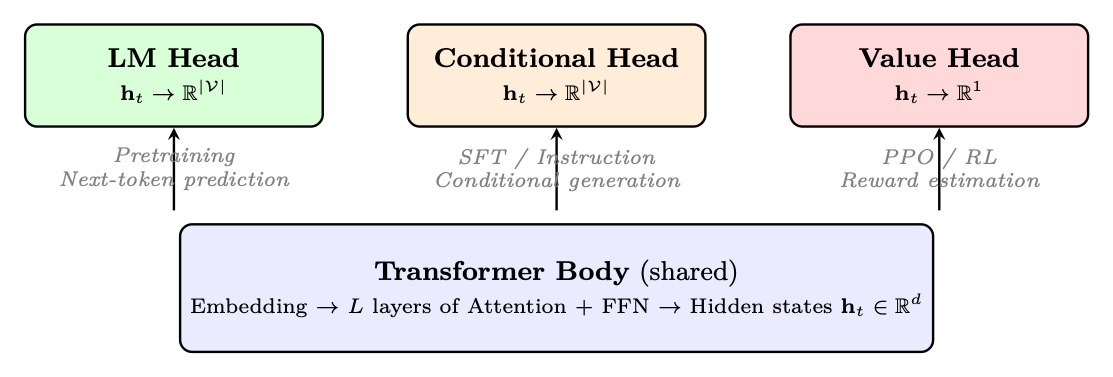
Language Modeling Head (Pretraining)
The standard LM head projects the final hidden state to vocabulary logits and trains with cross-entropy loss over the next token:
where (often tied with the embedding matrix: ).
Conditional Generation Head (SFT / Instruction Following)
For supervised fine-tuning (SFT), the architecture is identical to the LM head—the same linear projection to vocabulary logits. The difference is purely in what we compute loss on:
Value Head (Regression for RL)
In reinforcement learning (PPO, GRPO), we need to estimate how good a state is—this requires a scalar output, not vocabulary logits. The value head replaces the LM projection with a simple regression layer:
where and .
Head Selection Summary
| Head | Output | Loss | Stage | Purpose |
|---|---|---|---|---|
| LM Head | Cross-entropy (all tokens) | Pretraining | Learn language from raw text | |
| Conditional Head | Cross-entropy (response only) | SFT | Learn to follow instructions | |
| Value Head | MSE | RL (PPO) | Estimate state value for advantage | |
| Reward Head | Pairwise ranking | RM training | Score response quality |
Table 1.9:Prediction heads used throughout this paper and their training contexts.
HuggingFace Implementation
from transformers import (
    AutoModelForCausalLM,          # LM head (pretraining + SFT)
    AutoModelForSequenceClassification,  # Reward head
    AutoTokenizer,
)
from trl import AutoModelForCausalLMWithValueHead  # Value head (PPO)
import torch

model_name = "meta-llama/Llama-3.1-8B-Instruct"
tokenizer = AutoTokenizer.from_pretrained(model_name)

# === 1. LM Head (Pretraining / SFT) ===
# The default CausalLM model -- projects hidden states to vocab logits
lm_model = AutoModelForCausalLM.from_pretrained(
    model_name,
    torch_dtype=torch.bfloat16,
    device_map="auto",
)
# lm_model.lm_head: Linear(hidden_size -> vocab_size)
# Output: logits of shape (batch, seq_len, vocab_size)

inputs = tokenizer("The capital of France is", return_tensors="pt")
outputs = lm_model(**inputs)
next_token_logits = outputs.logits[:, -1, :]  # (batch, vocab_size)
probs = torch.softmax(next_token_logits, dim=-1)

# === 2. Conditional Head (SFT) ===
# Architecturally identical to LM head -- difference is in loss masking
# During SFT, we only compute loss on response tokens:
messages = [
    {"role": "user", "content": "What is 2+2?"},
    {"role": "assistant", "content": "4"},
]
formatted = tokenizer.apply_chat_template(messages, return_tensors="pt")
labels = formatted.clone()
# Mask prompt tokens (set to -100 so cross-entropy ignores them)
prompt_len = len(tokenizer.apply_chat_template(messages[:1]))
labels[:, :prompt_len] = -100
loss = lm_model(input_ids=formatted, labels=labels).loss

# === 3. Value Head (PPO Critic) ===
# Adds a Linear(hidden_size -> 1) on top of the LM backbone
value_model = AutoModelForCausalLMWithValueHead.from_pretrained(
    model_name,
    torch_dtype=torch.bfloat16,
    device_map="auto",
)
# value_model.v_head: Linear(hidden_size -> 1)
# Returns both LM logits AND per-token value estimates

inputs = tokenizer("Explain quantum computing", return_tensors="pt")
lm_logits, loss, values = value_model(
    **inputs, return_dict=False
)
# values shape: (batch, seq_len, 1) -- scalar estimate per token

# === 4. Reward Head (Reward Model) ===
# Classification head: Linear(hidden_size -> 1) on last token
reward_model = AutoModelForSequenceClassification.from_pretrained(
    model_name,
    num_labels=1,              # single scalar output
    torch_dtype=torch.bfloat16,
    device_map="auto",
)
# Scores entire sequence by pooling the last token's hidden state
inputs = tokenizer("Good response here", return_tensors="pt")
reward_score = reward_model(**inputs).logits  # shape: (batch, 1)
Listing 3:Loading and using different prediction heads with HuggingFace.
Optimization Theory for LLM Training
Training a large language model means finding the set of parameters (billions of weights) that minimizes the loss function — typically the negative log-likelihood of the next token. This is an optimization problem in extraordinarily high-dimensional space, and the algorithm used to navigate this space determines whether training succeeds, diverges, or stalls.
Gradient Descent: The Foundation
The gradient is a vector that points in the direction of steepest increase of the loss. Each component tells us how much the loss would change if we slightly increased parameter . To decrease the loss, we move in the opposite direction:
where is the learning rate — the step size. This is gradient descent[310].
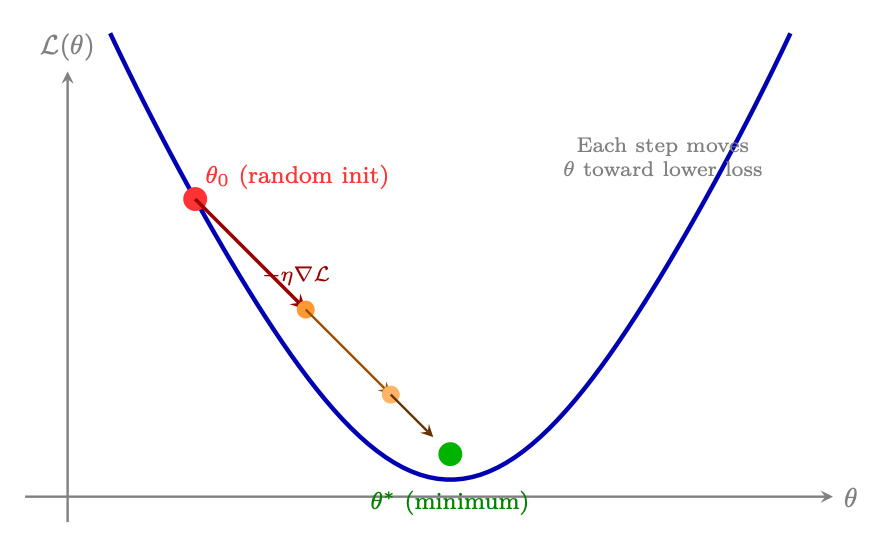
Computing the exact gradient requires evaluating the loss over the entire training dataset (trillions of tokens for LLMs). This is computationally prohibitive — a single gradient step would require a full pass over all data.
The solution: estimate the gradient from a small random subset (mini-batch) of the data [308]:
where is the batch size (typically 1K–4M tokens for LLMs). The mini-batch gradient is a noisy but unbiased estimate of the true gradient.
While SGD with momentum works well for vision models (CNNs), LLM training requires adaptive optimizers — algorithms that maintain a per-parameter learning rate.
Why Vanilla SGD Fails for LLMs
Stochastic Gradient Descent updates weights as:
Adam – Adaptive Moment Estimation
Adam [185] maintains per-parameter estimates of the first moment (mean of gradients) and second moment (uncentered variance of gradients).
AdamW – Decoupled Weight Decay
AdamW [239] fixes a subtle but important issue with how weight decay interacts with adaptive optimizers.
Muon: Beyond AdamW
For nearly a decade, AdamW was the unchallenged default optimizer for neural network training. Muon [225] (Liu et al., 2025) is the first serious challenger to that dominance. Its core insight is that the momentum buffer accumulated by Adam carries directional information that is obscured by the adaptive scaling step—and that orthogonalizing that momentum before applying it produces a fundamentally better update direction.
The Newton-Schulz iteration is a matrix polynomial that converges to the orthogonal factor of the polar decomposition of . Concretely, starting from , the iteration
converges rapidly (typically 5–10 steps) to a matrix satisfying . Orthogonality ensures that the update moves weight matrices in a direction that is maximally spread across all singular value directions—preventing the optimizer from collapsing updates onto a low-rank subspace, which is a known failure mode of Adam on weight matrices with highly skewed singular value spectra.
Muon claims approximately 2 compute efficiency relative to AdamW: the same validation loss is reached in roughly half the gradient steps. This is not a marginal improvement—it represents a qualitative shift in the optimizer’s sample efficiency on the loss landscape.
The momentum is clearly shifting toward Muon in large-scale pretraining:
- GLM-4.5 / GLM-5 (Zhipu AI) [434, 435]: adopted Muon for pretraining
- Kimi K2 (Moonshot AI) [17]: uses MuonClip, a variant that adds QK-Clip—rescaling query and key projections to cap attention logits and prevent loss spikes. Kimi K2 trained over 15.5T tokens with zero loss spikes, a stability record for models at that scale.
- DeepSeek-V4 (2026) [72]: adopted Muon for its pretraining run
Learning Rate – The Most Important Hyperparameter
Learning Rate Warmup
- Linear warmup:
- Typical warmup duration: 1–5% of total steps for pretraining; 3–10% for fine-tuning (shorter runs need proportionally more warmup)
- For SFT: 50–200 warmup steps is typical
Learning Rate Schedules
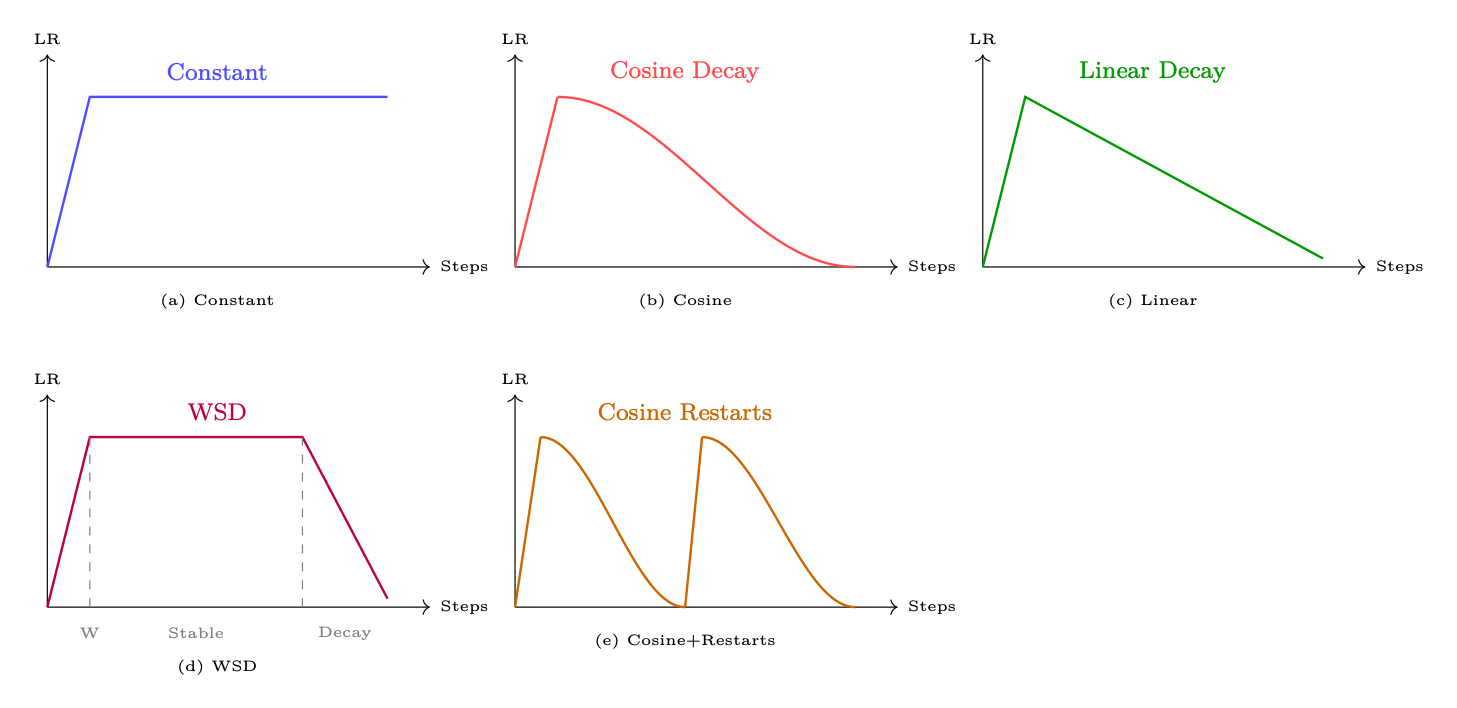
Simplest schedule. Good for short fine-tuning runs where you want to avoid over-decaying the LR. Risk: no annealing means the model may not converge to the sharpest minimum.
Standard for pretraining and SFT. Smooth decay avoids abrupt LR changes. is typically .
Simpler than cosine, similar empirical results. Preferred when you want predictable LR at any step.
The new standard for large-scale pretraining [150, 118]. Three phases:
- Warmup: Linear ramp to (1–5% of steps)
- Stable: Constant for the majority of training
- Decay: Fast cosine or linear decay to (last 10–20% of steps)
Key advantage: the stable phase allows checkpointing at any point and continuing training. The decay phase can be applied at the end of any run.
Periodic restarts reset the LR to . Can help escape local minima. Less common for LLMs; more useful for smaller models.
Gradient Clipping
The following snippet shows how the concepts from this section—AdamW with decoupled weight decay (§1.6.6), cosine learning-rate scheduling with linear warmup (§1.6.7), and gradient clipping (§1.6.8)—come together in practice using the HuggingFace transformers library.
from transformers import TrainingArguments, Trainer
from transformers import get_cosine_schedule_with_warmup
import torch

# --- Option 1: Using TrainingArguments (recommended) ---
training_args = TrainingArguments(
    output_dir="./checkpoints",

    # AdamW optimizer (decoupled weight decay, S1.6.6)
    optim="adamw_torch",
    learning_rate=2e-5,           # peak LR after warmup
    adam_beta1=0.9,               # first moment decay
    adam_beta2=0.999,             # second moment decay
    adam_epsilon=1e-8,            # numerical stability
    weight_decay=0.01,           # decoupled L2 penalty

    # Learning rate schedule (S1.6.7)
    lr_scheduler_type="cosine",  # cosine decay to 0
    warmup_ratio=0.1,            # 10% of steps = linear warmup

    # Gradient clipping (S1.6.8)
    max_grad_norm=1.0,           # clip by global L2 norm

    # Mixed precision (S1.6.9)
    bf16=True,                   # use BFloat16 on Ampere+ GPUs

    # Training duration
    num_train_epochs=3,
    per_device_train_batch_size=8,
    gradient_accumulation_steps=4,  # effective batch = 8*4 = 32
)

trainer = Trainer(
    model=model,
    args=training_args,
    train_dataset=dataset,
)
trainer.train()

# --- Option 2: Manual control (for custom training loops) ---
from torch.optim import AdamW

# Separate weight-decay groups (don't regularize biases/norms)
no_decay = ["bias", "LayerNorm.weight", "layernorm.weight"]
param_groups = [
    {
        "params": [p for n, p in model.named_parameters()
                   if not any(nd in n for nd in no_decay)],
        "weight_decay": 0.01,
    },
    {
        "params": [p for n, p in model.named_parameters()
                   if any(nd in n for nd in no_decay)],
        "weight_decay": 0.0,
    },
]

optimizer = AdamW(param_groups, lr=2e-5, betas=(0.9, 0.999))

# Cosine schedule with linear warmup
total_steps = len(train_dataloader) * num_epochs
warmup_steps = int(0.1 * total_steps)
scheduler = get_cosine_schedule_with_warmup(
    optimizer,
    num_warmup_steps=warmup_steps,
    num_training_steps=total_steps,
)

# Training loop with gradient clipping
for batch in train_dataloader:
    outputs = model(**batch)
    loss = outputs.loss
    loss.backward()

    # Clip gradients before optimizer step
    torch.nn.utils.clip_grad_norm_(model.parameters(), max_norm=1.0)

    optimizer.step()
    scheduler.step()
    optimizer.zero_grad()
Listing 4:Complete optimizer configuration combining AdamW – cosine schedule – and gradient clipping.
Mixed Precision Training
- Multiply loss by scale factor (e.g., )
- Compute gradients in FP16 (scaled by )
- Before optimizer step, divide gradients by
- Check for overflow (NaN/Inf); if found, skip step and reduce
- If no overflow for consecutive steps, increase
In mixed precision training, weights are stored in FP32 (master copy) and cast to BF16/FP16 for the forward/backward pass. The optimizer step is done in FP32. This is important because:
- Small gradient updates () would be lost in BF16 precision (7 mantissa bits 0.8% relative precision)
- FP32 master weights ensure accurate accumulation of small updates over many steps
- Memory cost: 2 weight storage (FP32 + BF16 copy)
# === HuggingFace TrainingArguments (simplest approach) ===
from transformers import TrainingArguments

# BF16 on Ampere+ GPUs (A100, H100, RTX 30xx/40xx)
args_bf16 = TrainingArguments(
    output_dir="./out",
    bf16=True,               # BF16 forward/backward; FP32 master weights
    bf16_full_eval=True,     # also use BF16 during evaluation
    # No loss scaling needed -- BF16 has FP32-equivalent range
)

# FP16 on older GPUs (V100, T4, RTX 20xx)
args_fp16 = TrainingArguments(
    output_dir="./out",
    fp16=True,               # FP16 forward/backward
    fp16_full_eval=False,    # keep eval in FP32 for accuracy
    # Loss scaling is automatic via PyTorch GradScaler
)

# === Manual PyTorch AMP (for custom training loops) ===
import torch

# Setup (PyTorch 2.x API)
use_fp16 = not torch.cuda.is_bf16_supported()
scaler = torch.amp.GradScaler("cuda", enabled=use_fp16)  # only needed for FP16
optimizer = torch.optim.AdamW(model.parameters(), lr=2e-5)
dtype = torch.float16 if use_fp16 else torch.bfloat16

for batch in train_dataloader:
    optimizer.zero_grad()

    # Autocast: run forward pass in reduced precision
    with torch.autocast("cuda", dtype=dtype):
        outputs = model(**batch)
        loss = outputs.loss

    if use_fp16:
        # FP16 path: scale loss to prevent gradient underflow
        scaler.scale(loss).backward()
        scaler.unscale_(optimizer)          # unscale before clipping
        torch.nn.utils.clip_grad_norm_(model.parameters(), 1.0)
        scaler.step(optimizer)              # skips step on overflow
        scaler.update()                     # adjust scale factor
    else:
        # BF16 path: no scaling needed
        loss.backward()
        torch.nn.utils.clip_grad_norm_(model.parameters(), 1.0)
        optimizer.step()

    scheduler.step()
Listing 5:Mixed precision training with HuggingFace and manual PyTorch AMP.
DeepSeek-V3 [71] demonstrated that 671B-parameter training in FP8 (E4M3 for forward pass, E5M2 for backward) with fine-grained tile-wise scaling achieves less than 0.25% relative loss degradation versus BF16—at a total training cost of approximately $5.6M. Key techniques include stochastic rounding to reduce quantization bias, per-tile scaling factors that adapt to local activation magnitudes, and keeping the first and last layers in higher precision where quantization sensitivity is greatest. NVIDIA’s Nemotron 3 pushes further to NVFP4 (4-bit), demonstrating stability over 25T training tokens by maintaining approximately 15% of layers in BF16. The economic implication is profound: careful precision engineering reduces frontier training costs by 3–5, making billion-parameter training accessible beyond the largest labs.
Practical Optimizer Settings by Training Phase
Flash Attention – Algorithm and Hardware Awareness
Flash Attention [64, 65] is one of the most impactful algorithmic innovations in deep learning since the transformer itself. It does not change the mathematical result of attention – it computes exactly the same output – but it restructures the memory access pattern so that the GPU’s limited fast SRAM does all the heavy lifting, cutting HBM footprint from to and delivering 2–4 end-to-end wall-clock gains on typical workloads.
The Standard Attention Memory Problem
Standard scaled dot-product attention is:
The Flash Attention Key Insight – Tiling and Online Softmax
The core insight is: we never need the full matrix in memory at once. We can compute the output block-by-block if we use the online softmax trick.
Recall that softmax requires a global maximum for numerical stability:
The trick: we can update the running maximum and normalization factor as we process new blocks, without ever materializing the full row.
The Flash Attention Algorithm
Flash Attention 2 – Better Parallelism
Flash Attention 2 [65] made three key improvements:
- Reduced non-matmul FLOPs: The original FA had unnecessary rescaling operations in the inner loop. FA2 restructures the loop to minimize these. On A100, Tensor Core matrix multiplications outpace scalar operations by roughly 16, so even a small fraction of non-matmul work in the inner loop becomes the latency bottleneck.
- Better parallelism across sequence dimension: FA1 parallelized over batch and heads only. FA2 also parallelizes over the query sequence dimension, enabling better GPU utilization for long sequences with small batch sizes.
- Causal masking optimization: For autoregressive (causal) attention, roughly half the blocks are fully masked. FA2 skips these blocks entirely, giving 2 speedup for causal attention vs. bidirectional.
Flash Attention 3 – Hopper Architecture
Flash Attention 3 [322] is designed specifically for H100 and exploits three Hopper-specific features:
- TMA (Tensor Memory Accelerator): H100 has a dedicated hardware unit for asynchronous bulk data movement between HBM and SRAM. FA3 uses TMA to overlap data loading with computation, hiding memory latency.
- Warp-specialization: FA3 assigns different warps to different roles (producer warps load data via TMA; consumer warps compute MMA). This is a software pipelining technique that keeps both the memory system and Tensor Cores busy simultaneously.
- FP8 support: H100 supports FP8 (E4M3/E5M2) Tensor Core operations at 2 the throughput of BF16. FA3 supports FP8 attention with per-block quantization to maintain accuracy.
FA3 achieves up to 75% of H100 theoretical peak for FP16 attention, compared to 35% for FA2.
Flash Attention 4 – Blackwell Architecture
Flash Attention 4 [415] targets NVIDIA’s Blackwell GPUs (B200/GB200), which double Tensor Core throughput to 2.25 PFLOP/s (BF16) while non-matmul units (exponential, shared memory bandwidth) scale at a slower rate. This asymmetric hardware scaling means that the bottleneck shifts: on Blackwell, attention is limited not by matmul but by the softmax exponentials and shared memory traffic surrounding them.
FA4 addresses this with four key techniques:
- Fully asynchronous MMA pipelines: Blackwell’s MMA instructions are fully asynchronous (unlike Hopper’s wgmma which still blocked on completion). FA4 redesigns the pipeline to overlap MMA, TMA loads, and softmax rescaling across larger tile sizes, keeping all hardware units saturated.
- Software-emulated exponential: Instead of calling the hardware
ex2unit (which is the throughput bottleneck), FA4 emulates using polynomial approximations executed on the much faster Tensor Cores themselves. This trades extra matmul instructions for exponential-unit stalls. - Conditional softmax rescaling: Standard FlashAttention rescales the running every tile. FA4 skips the rescaling when the new tile’s max does not exceed the running max (common in practice), saving both register shuffles and synchronization barriers.
- Tensor Memory + 2-CTA MMA mode (backward pass): The backward pass uses Blackwell’s Tensor Memory (a per-SM scratchpad larger than shared memory) and a 2-CTA cooperative mode that fuses accumulation across two thread-block clusters, halving shared memory round-trips.
On B200 with BF16 head-dim 128 (causal, seq-len 8K):
- 1613 TFLOP/s – 71% of Blackwell peak utilization
- 1.3 faster than cuDNN 9.13 (NVIDIA’s proprietary fused kernel)
- 2.7 faster than Triton on the same hardware
Pretraining: Best Practices
Pretraining is the most expensive phase of LLM development—consuming millions of GPU-hours and requiring careful orchestration of data, compute, and hyperparameters. This section distills key lessons from Llama-3 [118], Chinchilla [140], and GPT-4 [274].
Training Objective
All modern decoder-only LLMs use causal language modeling (CLM):
This simple objective—with enough data and scale—produces emergent capabilities (in-context learning, reasoning, instruction following) without explicit supervision [32].
Data Pipeline
Scaling Laws
Hoffmann et al. [140] showed that compute-optimal training requires balancing model size and data size : , . A 70B model is compute-optimal at 1.4T tokens. In practice, models are over-trained (more tokens than Chinchilla-optimal) because inference cost scales with model size, not training tokens—smaller over-trained models are cheaper to deploy.
Key Hyperparameters
| Setting | Llama-3 405B | Llama-3 8B | Qwen-2.5 72B | Mistral 7B |
|---|---|---|---|---|
| Tokens | 15T | 15T | 18T | 8T |
| Batch size (tokens) | 16M | 4M | 4M | 4M |
| Peak LR | ||||
| Schedule | WSD | WSD | Cosine | Cosine |
| Weight decay | 0.1 | 0.1 | 0.1 | 0.1 |
| Context length | 8192 | 8192 | 409632K | 8192 |
Table 1.10:Pretraining hyperparameters from published models.
Common Failure Modes
Mid-Training: Preparing for Reinforcement Learning
A distinct pipeline stage has emerged between raw pretraining and post-training. Mid-training (sometimes called “continued pretraining” or “annealing”) up-weights STEM, mathematics, and code on high-quality curated data while extending context length to 128K–256K tokens. Its purpose is not to teach new knowledge but to prepare the model for RL: instilling the cognitive behaviors—verification, backtracking, subgoal decomposition—that reinforcement learning will later amplify.
Typical mid-training uses 100B–500B tokens of curated high-quality data with a cosine-decayed learning rate. Llama 3’s “annealing tail,” MiMo’s 3-stage mixture (ramping math+code to 70%), and MAI-Thinking-1’s explicit STEM up-weight are all instances of this pattern.
Supervised Fine-Tuning (SFT)
SFT transforms a pretrained language model into an instruction-following assistant by training on curated prompt–response pairs. This is the bridge between raw language modeling and RLHF.
SFT Objective
The loss is identical to CLM, but computed only on response tokens:
Prompt tokens provide context but receive no gradient (labels set to ).
Data Quality: The LIMA Principle
Zhou et al. [439] demonstrated that 1,000 carefully curated examples can match models trained on 50K+ noisy examples. Key requirements:
- Diversity: Cover QA, summarization, code, math, creative writing, multi-turn dialogue
- Correctness: Every response must be factually accurate and well-formatted
- Length balance: Mix short (1-sentence) and long (multi-paragraph) responses
- Decontamination: Remove overlap with evaluation benchmarks
Training Configuration
from trl import SFTTrainer, SFTConfig

sft_config = SFTConfig(
    output_dir="./sft_output",
    max_seq_length=4096,
    packing=True,              # Pack short examples into full sequences
    learning_rate=2e-5,
    lr_scheduler_type="cosine",
    warmup_ratio=0.1,
    weight_decay=0.01,
    max_grad_norm=1.0,
    num_train_epochs=3,
    per_device_train_batch_size=4,
    gradient_accumulation_steps=8,
    bf16=True,
    gradient_checkpointing=True,
)
trainer = SFTTrainer(model=model, args=sft_config,
                     train_dataset=dataset, processing_class=tokenizer)
trainer.train()
Efficient Training Solutions
Standard HuggingFace training leaves significant performance on the table. Several libraries provide drop-in efficiency gains for SFT workloads:
An open-source set of Triton-fused kernels from LinkedIn that replace standard PyTorch operators during training. Key fusions include:
- Fused Cross-Entropy: Merges the final linear projection, softmax, and loss computation into a single kernel—avoids materializing the full logit tensor.
- Fused RMSNorm / SwiGLU / RoPE: Eliminates intermediate memory allocations for common LLM building blocks.
- Chunked operations: Processes large tensors in tiles to keep peak memory bounded.
Result: 20% higher throughput and up to 60% memory reduction with a one-line integration (apply_liger_kernel_to_llama()). Compatible with FSDP, DeepSpeed, and LoRA.
A specialized fine-tuning library that combines custom CUDA/Triton kernels with aggressive memory optimization:
- Manual backpropagation through LoRA layers (avoids autograd overhead).
- 4-bit QLoRA with fused dequantization—trains 70B models on a single 48 GB GPU.
- Intelligent RoPE and attention kernel fusion specific to each architecture (Llama, Mistral, Qwen, Gemma).
Result: 2–5 faster than vanilla HuggingFace + PEFT, with 60–70% less VRAM. Particularly impactful for single-GPU and consumer-hardware workflows.
Meta’s native PyTorch fine-tuning library (development wound down in 2025), designed around composability rather than monolithic abstractions:
- Pure PyTorch—no trainer class; recipes are readable single-file scripts.
- Native integration with
torch.compile, FSDP2, and activation checkpointing. - First-class support for QLoRA, full fine-tuning, and knowledge distillation.
- Built-in quantization-aware training (QAT) for post-training compression.
Result: Comparable speed to custom solutions but with full debuggability and no framework lock-in.
Best Practices
| Practice | Details |
|---|---|
| Packing | Concatenate multiple short examples into one sequence (separated by EOS). Avoids padding waste. |
| NEFTune [159] | Add uniform noise to embeddings (). Improves MT-Bench by 5–15% at zero cost. |
| Chat template | Always use the model’s native template. Mismatched templates degrade quality. |
| Epochs | 2–3 for large datasets; up to 5 for small (10K) curated sets. Over-training causes format memorization. |
Table 1.11:SFT training guidelines.
LoRA and Parameter-Efficient Fine-Tuning
Full fine-tuning of a 70B model requires storing 70B trainable parameters plus their optimizer states (560+ GB of memory). LoRA [146] (Low-Rank Adaptation) provides a way to fine-tune with 1% of the parameters while achieving comparable quality.
The LoRA Insight
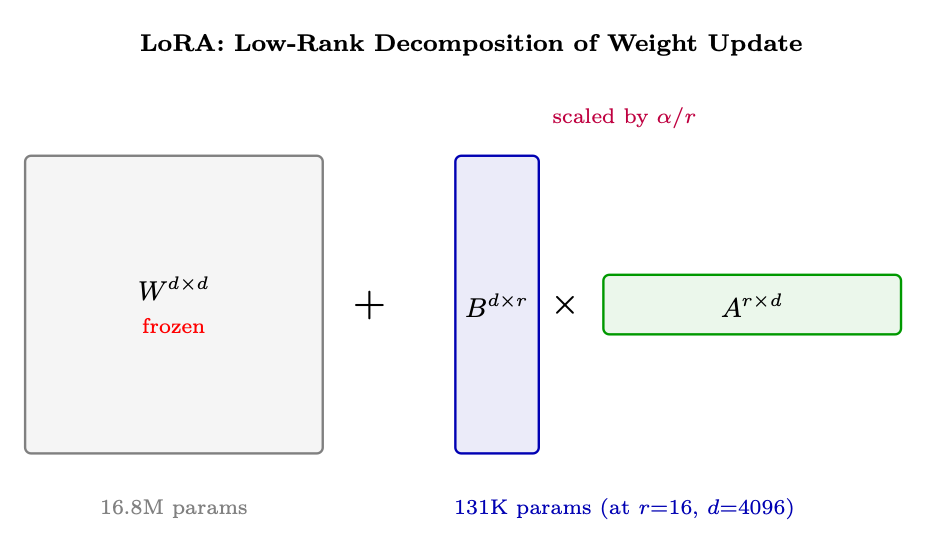
LoRA Hyperparameters
Choosing LoRA hyperparameters correctly is critical — the wrong rank or alpha can either under-fit (too constrained) or waste memory (too expressive).
| Hyperparameter | Typical Values | Guidance |
|---|---|---|
| r (rank) | 8, 16, 32, 64 | Higher = more capacity but more memory. Start with 16. |
| lora_alpha | 16, 32 (often or ) | Controls update magnitude via scaling. |
| target_modules | q_proj, k_proj, v_proj, o_proj | All attention projections. Add gate_proj, up_proj, down_proj for full coverage. |
| lora_dropout | 0.0–0.1 | Regularization. Usually 0.05 for small datasets. |
| bias | "none" | Training biases adds minimal params but rarely helps. |
| Learning rate | to | Higher than full fine-tuning (only adapters update). |
Table 1.12:LoRA hyperparameter guide.
LoRA Variants
| Method | Key Innovation | When to Use |
|---|---|---|
| QLoRA[75] | 4-bit quantized base + LoRA in BF16. NF4 data type + double quantization. | Fine-tune 70B on single 48GB GPU. |
| DoRA[229] | Decomposes into magnitude and direction; LoRA updates direction only. | Better generalization for reasoning. |
| LoRA+[136] | Different LRs for / (, ). | Free 2% gain; no extra cost. |
| AdaLoRA[424] | Dynamic rank budget across layers (SVD-based importance). | Very tight compute budget. |
| rsLoRA[176] | Scales by instead of . Stable at high ranks. | When using . |
| VeRA[190] | Shared frozen random ; trains diagonal scaling only. | Extreme param efficiency. |
| LoRA-FA | Freezes after init; only trains . Halves LoRA memory. | Memory-constrained scenarios. |
Table 1.13:LoRA variants and their innovations.
DoRA [229] observes that full fine-tuning tends to change the direction of weight vectors more than their magnitude. Standard LoRA conflates both. DoRA decomposes each weight column into magnitude and direction , then applies LoRA only to the direction:
Magnitude is a separate learnable vector (one scalar per column). This consistently outperforms LoRA by 1–3% on reasoning and instruction-following benchmarks with no additional inference cost (merged at deployment).
Hayou et al. [136] show that matrices and in LoRA have different optimal learning rates. Since is initialized to zero, it starts in a very different regime than (initialized from ). Setting improves convergence speed and final quality by 2% — a free gain requiring only a one-line config change:
# LoRA+ in PEFT: set different LRs per matrix
optimizer_grouped_parameters = [
    {"params": [p for n, p in model.named_parameters() if "lora_B" in n],
     "lr": 2e-4 * 16},   # B matrix: higher LR
    {"params": [p for n, p in model.named_parameters() if "lora_A" in n],
     "lr": 2e-4},         # A matrix: base LR
]
VeRA [190] takes parameter efficiency to the extreme: instead of learning and , it freezes them as shared random matrices across all layers and only trains two diagonal scaling vectors and :
This reduces trainable parameters by 10 vs. LoRA (only params per layer) while achieving 90–95% of LoRA quality. Best for scenarios where you need hundreds of task-specific adapters with minimal storage.
# QLoRA configuration with PEFT
from peft import LoraConfig, get_peft_model, prepare_model_for_kbit_training
from transformers import BitsAndBytesConfig
import torch

# 4-bit quantization config
bnb_config = BitsAndBytesConfig(
    load_in_4bit=True,
    bnb_4bit_quant_type="nf4",           # NormalFloat4 - optimal for weights
    bnb_4bit_compute_dtype=torch.bfloat16, # Compute in BF16
    bnb_4bit_use_double_quant=True,       # Quantize the quantization constants
)

# LoRA config
lora_config = LoraConfig(
    r=16,
    lora_alpha=32,                        # alpha/r = 2x scaling
    target_modules=["q_proj", "k_proj", "v_proj", "o_proj",
                    "gate_proj", "up_proj", "down_proj"],
    lora_dropout=0.05,
    bias="none",
    task_type="CAUSAL_LM",
)

model = prepare_model_for_kbit_training(model)  # Prepare for QLoRA
model = get_peft_model(model, lora_config)       # Add LoRA adapters
model.print_trainable_parameters()
# Output: trainable params: 83,886,080 || all params: 70,553,706,496 || 0.12%
Other PEFT Approaches
LoRA dominates modern practice, but it is not the only parameter-efficient method. For completeness, the main alternatives:
| Method | Mechanism | Pros / Cons | Status |
|---|---|---|---|
| LoRA[146] (and variants) | Low-rank matrices added to existing weights | Mergeable at inference (zero overhead); well-supported; works for all architectures | Standard |
| Adapters[144] | Small bottleneck MLPs inserted between layers | Modular; stackable; adds inference latency (extra sequential layers) | Rarely used |
| Prefix Tuning[212] | Learnable “virtual tokens” prepended to keys/values at each layer | No weight modification; effective for generation tasks; consumes context length | Niche |
| Prompt Tuning[205] | Learnable soft prompt embeddings prepended to input | Extremely few params (0.01%); weaker than LoRA for complex tasks | Niche |
| IA3[223] | Learned vectors that rescale keys, values, and FFN activations | Even fewer params than LoRA; mergeable; limited capacity | Deprecated |
| BitFit[417] | Train only bias terms | Near-zero params; surprisingly effective for simple tasks; limited expressiveness | Historical |
Table 1.14:PEFT method families. LoRA is the de facto standard for LLM fine-tuning; the others are included for historical context and niche use cases.
Mixture of Experts (MoE)
Mixture of Experts models [325, 166] scale model capacity without proportionally scaling compute cost by activating only a subset of parameters for each token.
Architecture
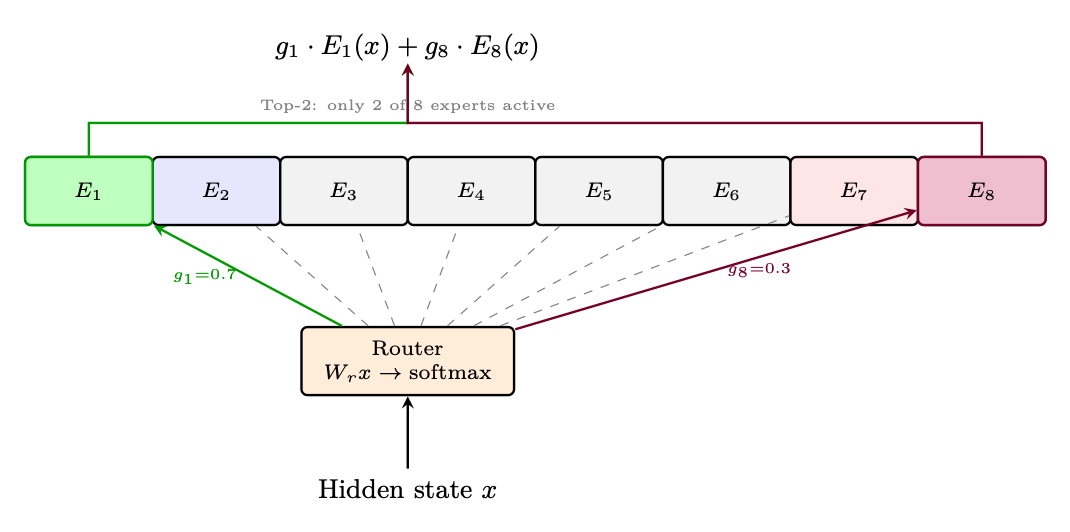
Load Balancing
Noisy Top-K Gating: Making Discrete Routing Trainable
The core challenge in MoE is that top- selection is not differentiable — you can’t backpropagate through a hard “pick the top 2” operation. The field has developed two key tricks to solve this:
Add learnable Gaussian noise to the router logits before the top- selection:
- is a learned noise magnitude — the model learns how much exploration each expert needs
- During training, noise occasionally promotes “underdog” experts into the top-, giving them gradient signal
- At inference, noise is removed: use clean logits for deterministic routing
- The Softplus ensures noise scale is always positive
An alternative from the variational inference literature [161]. The Gumbel-Max trick provides exact sampling from a categorical distribution:
where Gumbel noise is generated as .
For top- routing: taking the top- of gives samples without replacement from the categorical distribution defined by .
Since is non-differentiable, the Gumbel-Softmax relaxation replaces it with a temperature-controlled softmax:
- : approaches a hard one-hot (exact but non-differentiable)
- : approaches uniform (differentiable but uninformative)
- In practice, anneal from 1.0 down to 0.1–0.5 during training
- Straight-through estimator: use hard top- in the forward pass, but Gumbel-Softmax gradients in the backward pass — best of both worlds
The standard approach adds a balance penalty to the training loss, but DeepSeek [372] demonstrated that this fights the routing signal: the loss pushes toward uniform utilization while the router tries to specialize. Their solution moves balancing entirely out of the gradient into a per-expert routing bias updated based on observed utilization—achieving both better quality and more expert specialization. A subsequent insight from Qwen revealed that the aggregation scope matters more than the mechanism: computing balance statistics per micro-batch (the common default) silently destroys specialization because micro-batches are too homogeneous. Aggregating over the full global batch—as MAI-Thinking-1 confirms—restores the diversity signal that experts need to differentiate.
Notable MoE Models
ModelTotal ParamsActive ParamsExpertsInnovationSwitch Transformer [89]1.6T100B128, Top-1First large-scale MoE; simplified routingMixtral 8x7B [166]47B13B8, Top-2Open-weight; matches Llama-2 70B qualityDeepSeek-V2 [70]236B21B160, Top-6DeepSeekMoE with shared + routed expertsQwen-MoE [350]14.3B2.7B60, Top-4Fine-grained experts for efficiencyDBRX [67]132B36B16, Top-4Fine-grained with 4 experts per block
Diversity in LLM Training
Diversity — in training data, model outputs, and optimization trajectories — is critical for preventing mode collapse and ensuring robust, general-purpose LLMs. This section covers the key diversity mechanisms applicable to all LLM training phases.
Sampling Diversity
Training Data Diversity
- Prompt diversity: Cover different domains, difficulty levels, and formats. The Goldilocks principle: prompts should have 20–80% success rate.
- Deduplication: Remove near-duplicate training examples (MinHash, n-gram overlap). Duplicates cause overfitting to specific patterns.
- Data mixing: Balance across tasks/domains using temperature-weighted sampling or curriculum strategies.
Diversity-Promoting Methods
MethodHow It Promotes DiversityTemperature scalingHigher flattens the distribution; more tokens become plausible.Top- / Min-Adaptive thresholds allow wider sampling when the model is uncertain.Frequency penaltyPenalizes repeated tokens, forcing lexical variety within a response.Data deduplicationRemoving near-duplicates from training data prevents overfitting to specific patterns.Multi-domain mixingTemperature-weighted sampling across domains ensures broad coverage.Verbalized samplingPrompt the model to explicitly verbalize a probability distribution over responses [422]. See §7.5 GRPO Variants and Extensions.
Text Generation: Decoding Methods
A trained language model outputs a probability distribution over the vocabulary at each step: . The decoding strategy determines how we select the next token from this distribution. This choice profoundly affects output quality, diversity, and coherence.
Greedy Decoding
The simplest strategy: always pick the highest-probability token.
Intuition: Like always taking the most obvious next word in a sentence. “The capital of France is…” “Paris” (probability 0.92).
Pros: Deterministic, fast, no hyperparameters.
Cons: Produces repetitive, generic text. Misses high-quality sequences where an early low-probability token leads to a globally better output. No diversity.
Beam Search
Maintain (beam width) partial hypotheses in parallel, expanding each by the top- tokens and keeping the highest-scoring complete sequences:
With length normalization to avoid favoring short sequences:
Intuition: Like exploring multiple paths in a maze simultaneously, keeping only the most promising ones at each junction.
Pros: Finds higher-likelihood sequences than greedy; good for translation and summarization where there’s a single “correct” output.
Cons: Still tends toward generic, repetitive text for open-ended generation; more compute; all beams often converge to similar outputs.
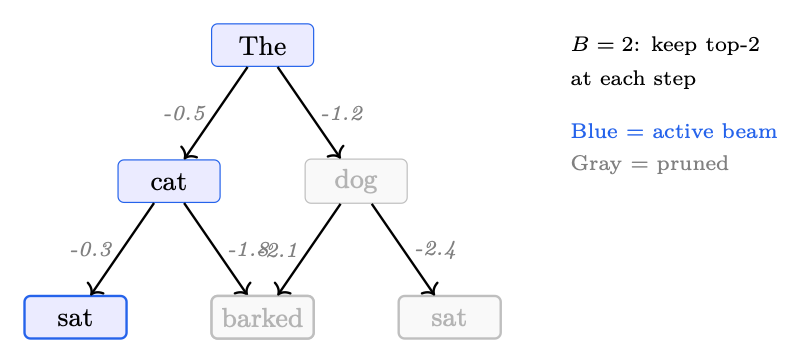
Diverse Beam Search
Standard beam search produces near-duplicate beams. Diverse beam search [360] partitions beams into groups and adds a dissimilarity penalty between groups:
where measures overlap (e.g., Hamming diversity) with tokens already selected by earlier groups, and controls diversity strength.
Intuition: Like forcing a brainstorming group to generate different ideas — each subgroup is penalized for repeating what earlier subgroups said.
Pros: Produces genuinely different candidate sequences; useful for reranking pipelines.
Cons: Diversity penalty can degrade individual beam quality; more hyperparameters (, ).
Top- kk Sampling
Sample from only the most probable tokens, redistributing probability mass:
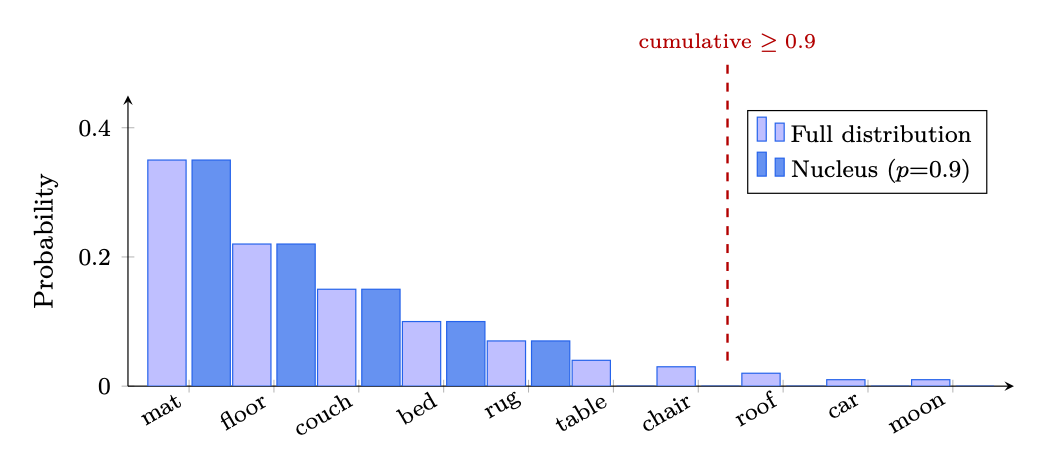
Intuition: After “The cat sat on the…”, only consider the top plausible continuations (“mat”, “floor”, “couch”, …) and ignore extremely unlikely ones (“quantum”, “archipelago”).
Pros: Removes tail noise; simple to implement.
Cons: Fixed is too restrictive for peaked distributions (wastes probability mass) and too permissive for flat distributions (lets in garbage tokens).
Top- pp (Nucleus) Sampling
Sample from the smallest set of tokens whose cumulative probability exceeds :
where tokens are sorted by descending probability and added until the threshold is reached.
Intuition: Adaptively resize the candidate pool. If the model is confident (“Paris” at 95%), the nucleus is tiny. If uncertain (“The movie was…”), the nucleus expands to include many plausible adjectives.
Pros: Adapts to distribution shape; widely used default (–).
Cons: Still includes some low-quality tokens at the tail of the nucleus; the threshold is a single global hyperparameter.
Min- pp Sampling
A recent alternative that sets a relative probability floor [266]:
Only tokens with probability at least times the top token’s probability are kept.
Intuition: “Only consider tokens that are at least 10% as likely as the best token.” If the top token has probability 0.8, only tokens above 0.08 survive. If the top token has probability 0.05 (very uncertain), tokens above 0.005 survive — naturally expanding the pool.
Pros: Scales naturally with model confidence; fewer degenerate samples than top- on peaked distributions; single intuitive parameter.
Cons: Newer, less battle-tested; not yet standard in all inference frameworks.
Temperature Scaling
Before applying any sampling strategy, logits are divided by temperature :
- : Sharpens distribution more deterministic, focused outputs.
- : Unmodified model distribution.
- : Flattens distribution more random, creative outputs.
- : Becomes greedy decoding. : Becomes uniform sampling.
Common settings: for factual tasks, – for creative writing, (greedy) for code/math.
Contrastive Decoding
Contrastive decoding [211] exploits the difference between a strong model (expert) and a weak model (amateur) to amplify the expert’s unique knowledge:
where is an adaptive plausibility constraint.
Intuition: The amateur model captures generic, obvious patterns (common words, repetition). Subtracting its log-probabilities removes this “generic signal,” leaving the expert’s distinctive knowledge and reasoning. Like removing background noise from a recording to hear the signal.
Pros: Reduces repetition and generic phrasing; improves factuality and coherence without additional training; works with any model pair.
Cons: Requires running two models (2 compute); sensitive to amateur model choice; the plausibility threshold needs tuning.
Repetition Penalties
Orthogonal to the sampling strategy, repetition penalties discourage the model from repeating tokens. Given the raw logit for token (i.e., the unnormalized score output by the LM head before softmax), the penalized logit is:
where is the penalty factor (typically 1.1–1.3). In both cases, the effect is to push the logit toward zero—reducing the probability of previously generated tokens. Frequency and presence penalties are simpler additive variants used by OpenAI APIs:
where is the frequency penalty (proportional to how many times appeared) and is the presence penalty (flat penalty for any prior occurrence).
Practical Comparison
| Method | Deterministic | Diversity | Quality | Best For |
|---|---|---|---|---|
| Greedy | Yes | None | Medium | Code, factual QA |
| Beam Search (=4–8) | Yes | Low | High (narrow) | Translation, summarization |
| Diverse Beam Search | Yes | Medium | High | Candidate generation for reranking |
| Top- (=50) | No | Medium | Medium | General-purpose generation |
| Top- (=0.9) | No | Adaptive | High | Default for open-ended tasks |
| Min- (=0.1) | No | Adaptive | High | Robust alternative to top- |
| Contrastive | Yes | Low | Very High | Factual, coherent long-form |
Table 1.15:Decoding method comparison for LLM text generation.
Constrained Decoding (Structured Generation)
All methods above sample from the full vocabulary at each step. Constrained decoding restricts the set of allowed tokens so that the output is guaranteed to conform to a formal grammar—typically a JSON schema, regex, or context-free grammar (CFG).
At each decoding step , a token mask is computed from the current parser state. Only tokens in receive their original logits; all others are set to before softmax:
where renormalizes. Because the mask changes every step (it depends on what has been generated so far), the constraint is enforced incrementally—the model cannot produce an invalid prefix at any point.
The compilation pipeline is:
The FSM states correspond to positions in the regex. For each state, all vocabulary tokens that would keep the string in the language are precomputed into an index (a one-time cost per schema). At runtime, looking up the mask is an table access—adding negligible latency to each decoding step.
- Outlines[378]: Compiles JSON schemas and regexes into interleaved FSM-guided generation. Supports any model with a logits interface.
- lm-format-enforcer: Similar FSM approach with a focus on integration with serving frameworks (vLLM, TGI).
- Guidance (Microsoft): Interleaves constrained generation with control flow (loops, conditions), enabling complex structured outputs beyond flat schemas.
- XGrammar[77]: Pushdown-automaton-based engine supporting full context-free grammars (not just regular languages), used in MLC-LLM and vLLM for grammar-mode decoding.
Constrained decoding guarantees syntactic validity—no post-hoc parsing failures, no retries. However:
- Semantic quality: Forcing structure can degrade content quality if the model’s probability mass for the “correct” answer lies outside the grammar. In practice this is rare for well-trained models on well-designed schemas.
- Compilation cost: The FSM index must be built per schema. For complex schemas this can take 1–5 s, but it is amortized over all requests using that schema.
- Grammar coverage: Regex/FSM handles JSON, YAML, SQL fragments, and most structured formats. Full CFGs (via XGrammar or LALR parsers) cover languages like Python or XML.
Prompt Engineering
Prompt engineering is the discipline of designing inputs to LLMs that reliably elicit desired behaviour—without changing model weights. While fine-tuning modifies the model, prompt engineering exploits the model’s existing capabilities through careful framing, examples, and structure. It is the fastest, cheapest, and most accessible lever for improving LLM outputs, and remains essential even when using fine-tuned models.
In-Context Learning (ICL)
In-context learning [32] is the remarkable ability of large language models to learn tasks at inference time purely from examples provided in the prompt—with no gradient updates. The model implicitly infers the task from the pattern of input–output pairs and generalizes to new inputs.
ICL emerges primarily in models above 1B parameters and improves log-linearly with model scale [32]. Smaller models can memorize examples but struggle to generalize to novel inputs within the same context window.
Zero-Shot Prompting
Zero-shot prompting provides no examples—only a task description or instruction. The model must rely entirely on its pretrained knowledge and instruction-tuning to produce the correct format and content.
- Tasks the model has seen extensively during pretraining/SFT (translation, summarization, sentiment)
- Well-specified instructions with unambiguous output format
- Instruction-tuned models (e.g., ChatGPT, Claude, Llama-3-Instruct) significantly outperform base models at zero-shot tasks [280]
Novel formats, domain-specific labeling schemes, or ambiguous tasks where the model cannot infer your exact requirements from the instruction alone.
Few-Shot Prompting
Few-shot prompting [32] provides input–output examples (“shots”) before the actual query. This is the most common form of in-context learning and remains one of the most effective prompting strategies.
- Diversity: Cover the range of expected inputs (different lengths, edge cases, categories).
- Ordering: Place harder or more representative examples last (recency bias) [242].
- Label balance: If classifying, include examples from all classes to avoid majority-class bias.
- Format consistency: Every example must follow the exact same structure. The model mimics the pattern.
- Relevance: Use examples semantically similar to the target query for best results [224].
Performance typically improves from 0 to 4–8 examples, then plateaus. Beyond 20 examples, gains are marginal and you risk filling the context window. Min et al. [257] showed that the format and label space of examples matter more than label correctness—even random labels help (though correct labels help more).
Instruction-Following Prompts
Instruction-tuned models respond best to clear, structured instructions. The key insight: treat the prompt as a specification, not a suggestion.
Modern chat APIs separate the system prompt (persistent instructions, role definition) from the user message (per-turn input). System prompts are processed with higher attention priority in most models and provide a natural place for role definitions, constraints, and output format specifications [274].
Structured Output Prompts (JSON/XML)
For programmatic use, the most critical prompting technique is enforcing structured output—particularly JSON.
- Schema-first: Show the exact JSON schema before the input. The model treats it as a template.
- Constrained decoding: Use grammar-based sampling (e.g., Outlines [378], Guidance) to guarantee syntactically valid JSON at the token level.
- XML tags: For nested or multi-part outputs, XML tags (e.g.,
<thinking>...</thinking>) provide unambiguous delimiters that models follow reliably. - Pydantic/TypeScript types: Providing type definitions helps models understand field constraints (OpenAI’s function calling uses JSON Schema internally).
A distinct but complementary technique is JSON prompting—formatting the prompt itself as JSON rather than natural language. This exploits the model’s extensive pre-training on structured data (APIs, configs, code) to improve instruction adherence, reduce ambiguity, and enable deterministic parsing of multi-field requests.
Chain-of-Thought (CoT) Prompting
Chain-of-thought prompting [374] asks the model to produce intermediate reasoning steps before giving a final answer. This simple technique dramatically improves performance on tasks requiring multi-step reasoning: arithmetic, logic, commonsense inference, and code generation.
- Serializes computation: Transformers have fixed depth but variable-length generation. CoT converts parallel (hard) problems into sequential (easy) steps, effectively increasing the model’s computational budget.
- Reduces compounding errors: Each step is a simpler sub-problem with lower per-step error rate.
- Exposes intermediate state: Makes reasoning auditable and debuggable.
Wang et al. [367] showed that sampling multiple chain-of-thought reasoning paths and taking a majority vote over final answers significantly outperforms single-path CoT. The intuition: correct reasoning paths tend to converge on the same answer, while errors are typically idiosyncratic. This trades compute (generating samples) for accuracy—practical when latency is less important than correctness.
CoT is not universally beneficial. For simple tasks (single-step classification, retrieval, formatting), CoT adds unnecessary tokens, increases latency, and can even introduce errors through overthinking. Use CoT selectively for tasks where you expect multi-step reasoning to be required.
Advanced Prompting Techniques
Rather than relying solely on the model’s parametric memory, RAG [209] retrieves relevant documents and includes them in the prompt:
Context (retrieved): [document chunks]
Question: [user query]
Answer based ONLY on the provided context.
This grounds the model’s responses in verifiable sources and dramatically reduces hallucinations for knowledge-intensive tasks.
Complex tasks benefit from being broken into a pipeline of simpler prompts, where the output of one becomes the input to the next:
- Extract key facts from document
- Reason over extracted facts
- Format final answer
Each step can use a different prompt template, model, or temperature setting. This is more controllable than a single monolithic prompt and enables targeted debugging.
Bai et al. [16] introduce prompts that ask the model to critique and revise its own output against a set of principles:
[Generate initial response]
Critique: Does this response violate any of the following
principles? [list principles]
Revision: Rewrite the response addressing the critique.
Rather than hand-crafting prompts, recent work automates prompt design:
- APE[441]: Uses an LLM to generate and score candidate prompts automatically.
- DSPy[182]: Compiles declarative task descriptions into optimized prompt pipelines with learned few-shot examples.
- OPRO[402]: Treats prompt optimization as an optimization problem, using an LLM as the optimizer.
ARQ [403] addresses a fundamental weakness of standard prompting: as context length grows, models increasingly “lose” critical information in the middle of the prompt (the lost-in-the-middle effect). ARQ mitigates this by decomposing a complex query into multiple focused sub-queries, each designed to direct the model’s attention to a specific part of the context:
- Query decomposition: Break the user question into atomic sub-questions that each target a narrow aspect.
- Attentive retrieval: For each sub-query, retrieve or highlight only the relevant context slice—forcing the model to attend to it.
- Aggregation: Combine sub-answers into a coherent final response.
This is particularly effective for long-document QA, multi-hop reasoning over large retrieval sets, and agentic tasks where the context window contains many tool outputs. ARQ can be seen as a structured form of chain-of-thought that explicitly manages where the model looks, not just how it reasons.
Best Practices: Crafting Effective Prompts
Based on empirical findings across the literature and practitioner experience, the following principles reliably improve prompt quality:
| Failure Mode | Symptom | Solution |
|---|---|---|
| Instruction amnesia | Model ignores constraints in long prompts | Move constraints to end; repeat key rules; use system prompt |
| Format drift | Output starts correct but degrades over long generations | Use constrained decoding; break into shorter chained prompts |
| Sycophancy | Model agrees with incorrect premises in the prompt | Add “challenge assumptions if incorrect”; use system-level instruction |
| Hallucinated details | Model invents facts not in provided context | Add “if unknown, say I don’t know”; use RAG with source attribution |
| Refusal over-triggering | Model refuses benign requests due to safety training | Rephrase to clarify legitimate intent; provide explicit context for why the request is appropriate |
Table 1.16:Common prompting failure modes and solutions.
Model Compression Methods
Model compression reduces model size and inference cost while preserving quality. Three main approaches: quantization (reduce precision), pruning (remove parameters), and distillation (train a smaller model to mimic a larger one).
Quantization
Quantization reduces model size and inference cost by representing weights (and optionally activations) in lower-precision formats. The core trade-off is compression ratio versus quality degradation.
| Method | Bits | Type | Key Idea |
|---|---|---|---|
| GPTQ[99] | 4-bit | PTQ, weight-only | Layer-wise quantization minimizing via optimal brain surgeon. |
| AWQ[218] | 4-bit | PTQ, weight-only | Protects salient weights (those with large activations). 1% of weights carry 99% importance. |
| GGUF[109] | 2–8 bit | PTQ, weight-only | CPU-optimized format (llama.cpp). Per-block quantization with multiple types. |
| FP8 (E4M3) | 8-bit | Training + inference | Native H100 support. 2 throughput vs BF16. |
| SmoothQuant[392] | W8A8 | PTQ, weight+act. | Smooths activation outliers into weights before quantization. Enables INT8 GEMM. |
| QAT[235] | 4-bit | QAT | Trains with simulated quantization. Highest quality but expensive. |
| AQLM[83] | 2-bit | PTQ, additive codes | Extreme compression via learned additive quantization codebooks. |
Table 1.17:Quantization methods for LLMs.
Pruning
Modern LLMs contain billions of parameters, yet empirical studies consistently show that a large fraction of these weights contribute minimally to model outputs. Pruning exploits this over-parameterization: by removing redundant weights, we reduce memory footprint (enabling deployment on smaller GPUs or edge devices), inference latency (fewer multiply-accumulate operations per forward pass), and serving cost (higher throughput per dollar). Unlike quantization, which reduces the precision of all weights uniformly, pruning selectively eliminates weights—enabling multiplicative savings when combined with quantization (e.g., a 50% sparse, 4-bit model uses less memory than the dense BF16 baseline). The challenge is achieving high sparsity without degrading generation quality, which has driven the development of principled one-shot methods that require no retraining.
Knowledge Distillation
Knowledge distillation [139] transfers the learned behaviour of a large teacher model into a smaller, cheaper student model. The core idea is that the teacher’s output distribution over tokens carries far richer signal than ground-truth hard labels alone — revealing inter-class similarities, calibration, and uncertainty that the student can exploit.
To expose the “dark knowledge” in the teacher’s logits we soften the distribution with a temperature :
At high temperature the probability mass spreads across more tokens, making near-miss alternatives visible. During training the same temperature is applied to the student; at inference the student uses .
The factor compensates for the reduced gradient magnitude of softened distributions. Typical values: , (more weight on KL when teacher quality is high).
| Paradigm | Mechanism | Pros | Cons |
|---|---|---|---|
| Offline / White-box | Teacher logits pre-computed; student trains on full distributions | Full distribution signal; one-time teacher cost | Stale data; storage heavy |
| Online / Co-training | Teacher generates on-the-fly; student sees fresh logits | Adapts to student weaknesses | compute; complex infra |
| Black-box (API) | Only teacher text outputs available (no logits) | Works with proprietary models | Loses dark knowledge; SFT-like |
| Self-distillation | Model distills into a smaller version of itself | No separate teacher needed | Teacher = student family; ceiling |
Table 1.18:Knowledge distillation paradigms for LLMs.
The teacher’s full logit vector (or top- logits for storage efficiency) is recorded for each training token. The student minimises the KL divergence against these stored distributions. This is the most data-efficient paradigm when teacher access is unrestricted.
Motivation: Decouple teacher inference from student training — run the teacher once on high-end hardware, then train many students cheaply.
Pros: Deterministic, reproducible; teacher cost is amortised; full distributional signal.
Cons: Requires storing -dimensional vectors per token (mitigated by top- pruning); teacher cannot adapt to student failures.
Teacher and student are run jointly: the teacher generates logits for the student’s current training batch.
Motivation: Let the teacher focus on inputs where the student currently struggles (curriculum-like).
Pros: Freshness; can use student-generated inputs for on-policy distillation.
Cons: Double the GPU cost; synchronisation complexity; harder to scale.
When only text outputs are available (e.g. distilling from a proprietary API), the student is trained via SFT on the teacher’s generations, optionally augmented with chain-of-thought traces.
Motivation: Practical reality — most frontier models do not expose logits.
Pros: Simple pipeline; works with any model behind an API.
Cons: No soft-label signal; prone to hallucination amplification; effectively supervised fine-tuning.
A model distils from a larger version within the same architecture family (e.g. Llama-3 70B 8B) or from its own checkpoints during training.
Motivation: Avoid training a separate teacher; leverage the model’s own capacity at different scales.
Pros: Architecture compatibility; no external dependency.
Cons: Teacher ceiling equals model ceiling; cannot introduce genuinely new knowledge.
- Sequence-level vs. token-level: Token-level KL is standard; sequence-level distillation (minimising KL over full sequences) better captures long-range coherence but is harder to optimise.
- Layer-wise hints: Matching intermediate representations (attention maps, hidden states) provides additional learning signal — especially useful when student architecture differs.
- Data selection: Distillation data quality matters; curating diverse, hard examples yields better students than random sampling.
- Student capacity: Diminishing returns below 10% of teacher parameters; at extreme compression, architecture changes (e.g. MoE dense) may be needed.
- Combining with quantization: Distillation + 4-bit quantization (e.g. QLoRA-distilled models) achieves near-teacher quality at compression.
Speculative Decoding Methods
Speculative decoding [206] accelerates autoregressive generation by predicting multiple tokens simultaneously, then verifying them in a single forward pass of the target model. It produces identical output distribution to standard decoding (no quality loss) while achieving 2–3 speedup.
Core Principle
Methods Comparison
| Method | Draft Source | Speedup | Key Idea |
|---|---|---|---|
| Standard[206] | Small model (1–7B) | 2–3 | Separate draft model generates candidates. Simple but requires loading 2 models. |
| Medusa[35] | Parallel LM heads | 2–3 | Add extra prediction heads to the target model. Each predicts token at position . |
| Eagle[213] | Feature-level | 2.5–3.5 | Lightweight decoder generates draft tokens from target model’s hidden states. Higher acceptance than Medusa. |
| Eagle-2[213] | Context-aware | 3–4 | Dynamic draft tree with confidence-based expansion. State-of-the-art acceptance rates. |
| N-gram Lookup | N-gram cache | 1.5–2 | Match prompt n-grams against previously generated text. Zero cost; great for repetitive outputs. |
| Lookahead[101] | Jacobi iteration | 2–2.5 | Parallel Jacobi decoding with n-gram verification. No draft model; uses target model itself. |
| Multi-token[111] | Modified arch. | 2–3 | Train the model to natively predict multiple tokens per step (Meta’s approach in Llama). |
Table 1.19:Speculative decoding methods supported by modern inference engines.
Medusa: Multi-Head Speculative Decoding
Eagle: Feature-Level Drafting
N-gram Speculative Decoding
Integration with vLLM
from vllm import LLM, SamplingParams

# Standard speculative decoding (separate draft model)
llm = LLM(
    model="meta-llama/Llama-3-70B",
    tensor_parallel_size=4,
    speculative_config={
        "model": "meta-llama/Llama-3-8B",
        "num_speculative_tokens": 5,
    },
)

# N-gram speculation (zero-cost, no draft model needed)
llm = LLM(
    model="meta-llama/Llama-3-70B",
    speculative_config={
        "method": "ngram",
        "num_speculative_tokens": 5,
        "prompt_lookup_max": 4,  # Match up to 4-grams from prompt
    },
)

# EAGLE-style (feature-level draft, high acceptance rate)
llm = LLM(
    model="meta-llama/Meta-Llama-3-8B-Instruct",
    tensor_parallel_size=4,
    speculative_config={
        "model": "yuhuili/EAGLE-LLaMA3-Instruct-8B",
        "num_speculative_tokens": 2,
        "method": "eagle",
        "draft_tensor_parallel_size": 1,
    },
)

# MLP speculator (IBM-style, lightweight head)
llm = LLM(
    model="meta-llama/Meta-Llama-3.1-70B-Instruct",
    tensor_parallel_size=4,
    speculative_config={
        "model": "ibm-ai-platform/llama3-70b-accelerator",
        "draft_tensor_parallel_size": 1,
    },
)
Hallucination Detection
LLMs generate fluent text that may be factually incorrect—a phenomenon called hallucination[164]. This section covers basic detection methods at the model level (without external retrieval or multi-agent verification).
Types of Hallucination
Detection Methods (Model-Level)
| Method | Mechanism | Signal |
|---|---|---|
| Token-level entropy | High entropy at generation time indicates uncertainty [175] | |
| Sequence log-prob | Low average log-probability of the output suggests confabulation | |
| Consistency sampling | Generate responses; low agreement likely hallucination [249] | Contradiction rate |
| Semantic entropy | Cluster meanings (not strings); high semantic entropy uncertain [193] | Cluster diversity |
| DoLA | Contrast logits between later vs. earlier layers; amplifies factual knowledge [58] | Layer divergence |
Table 1.20:Basic hallucination detection methods that operate at the model level.
Kuhn et al. [193] observe that token-level entropy is unreliable (paraphrases have different tokens but same meaning). Instead, they generate multiple responses, cluster them by semantic equivalence (via NLI), and compute entropy over meaning clusters:
High SE means the model produces semantically different answers—a strong hallucination signal.
Manakul et al. [249] detect hallucinations by checking self-consistency: generate multiple responses and verify whether claims in the main response are supported by the alternatives. If the model “disagrees with itself,” the claim is likely hallucinated. No external knowledge needed.
Chuang et al. [58] observe that factual knowledge emerges in later transformer layers while earlier layers retain more generic/uncertain representations. DoLA contrasts the logit distributions between a later (“mature”) layer and an earlier (“premature”) layer at each decoding step:
By amplifying the signal from factual knowledge encoded in deeper layers, DoLA reduces hallucinations at inference time without any retraining—requiring only a single additional forward pass through the contrasted layer. It is complementary to sampling-based methods and can be combined with them.
LLM Safety and Responsible AI
Safety is not an afterthought—it is an integral part of the LLM training pipeline. This section covers the key dimensions of LLM safety and the mechanisms used to enforce responsible behavior.
Threat Taxonomy
| Category | Description and Examples |
|---|---|
| Harmful content | Generating toxic, violent, or illegal instructions (bioweapons, CSAM) |
| Bias and discrimination | Perpetuating stereotypes; unfair treatment across demographics [104] |
| Privacy violations | Leaking PII from training data; memorization attacks [39] |
| Jailbreaking | Adversarial prompts that bypass safety guardrails [443] |
| Misinformation | Generating convincing but false claims (hallucination at scale) |
| Dual-use | Legitimate capabilities (coding, chemistry) weaponized for harm |
Table 1.21:LLM safety threat categories.
Safety Training Pipeline
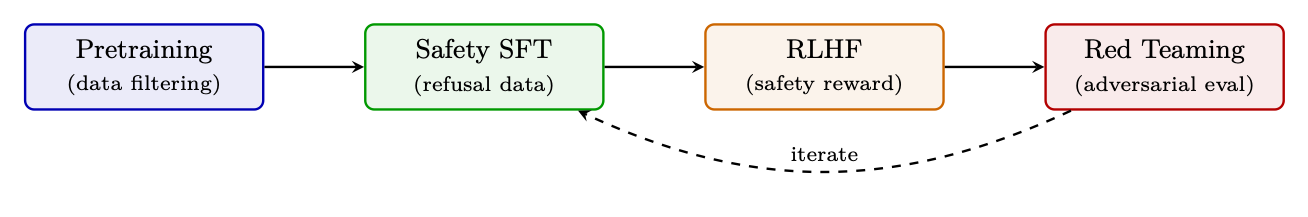
Key Safety Mechanisms
The Helpfulness–Safety Tradeoff
Evaluation
- Safety benchmarks: ToxiGen, RealToxicityPrompts, BBQ (bias), CrowS-Pairs
- Jailbreak robustness: GCG attacks [443], multi-turn jailbreaks, encoded prompts
- Over-refusal rate: Measure false-positive refusals on benign prompts (target 5%)
- Red team evaluations: Human adversarial testing with domain experts (biosecurity, cybersecurity)