
GPU Architecture – From Silicon to LLM Training
Modern large language models are trained and served almost exclusively on GPUs (Graphics Processing Units). Understanding GPU architecture is essential for making informed decisions about parallelism strategies, memory management, kernel optimization, and infrastructure sizing. This section provides a comprehensive introduction to GPU hardware as it relates to LLM workloads.
Why GPUs for Deep Learning?
GPUs and CPUs represent fundamentally different hardware philosophies. Understanding this difference explains why LLM training is 100–1000 faster on GPUs.
NVIDIA GPU Microarchitecture Generations
NVIDIA has released a series of GPU architectures, each bringing key innovations for deep learning:
| Architecture | Year | Flagship | Key Deep Learning Innovation |
|---|---|---|---|
| Pascal | 2016 | P100 | First HBM GPU; FP16 support; NVLink 1 |
| Volta | 2017 | V100 | Tensor Cores (first generation); mixed-precision training |
| Turing | 2018 | T4 | INT8 inference; RT cores (not for ML) |
| Ampere | 2020 | A100 | BF16 Tensor Cores; TF32; 3rd-gen NVLink; MIG |
| Hopper | 2022 | H100 | FP8 Tensor Cores; TMA; Transformer Engine; NVLink 4 |
| Blackwell | 2024 | B200 | 2nd-gen Transformer Engine; NVLink 5 (1.8 TB/s); FP4 |
Table 2.1:NVIDIA GPU microarchitecture timeline for deep learning.
Common GPUs for LLM Training and Inference
| GPU | Arch | HBM | BF16 TF | HBM BW | NVLink | LLM Role |
| V100-32GB | Volta | 32 GB | 125 TF* | 900 GB/s | 300 GB/s | Legacy; small model fine-tune |
| A100-40GB | Ampere | 40 GB | 312 TF | 1.5 TB/s | 600 GB/s | Budget training/inference |
| A100-80GB | Ampere | 80 GB | 312 TF | 2.0 TB/s | 600 GB/s | Standard RLHF (8–64 for 70B) |
| H100 SXM | Hopper | 80 GB | 990 TF | 3.35 TB/s | 900 GB/s | 3 faster training |
| H200 SXM | Hopper | 141 GB | 990 TF | 4.8 TB/s | 900 GB/s | Fits 70B policy+ref on fewer GPUs |
| B200 SXM | Blackwell | 192 GB | 2250 TF | 8.0 TB/s | 1800 GB/s | Next-gen; 2 over H100 |
| AMD and Google alternatives: | ||||||
| MI300X | CDNA3 | 192 GB | 1300 TF | 5.3 TB/s | N/A | Most memory; ROCm |
| TPU v5e | 16 GB | 197 TF | 1.6 TB/s | ICI 1.6 TB/s | Cloud-only; JAX/XLA | |
Table 2.2:GPU specifications relevant to LLM workloads. All bandwidth figures are bidirectional.
GPU Internal Architecture – The Streaming Multiprocessor (SM)
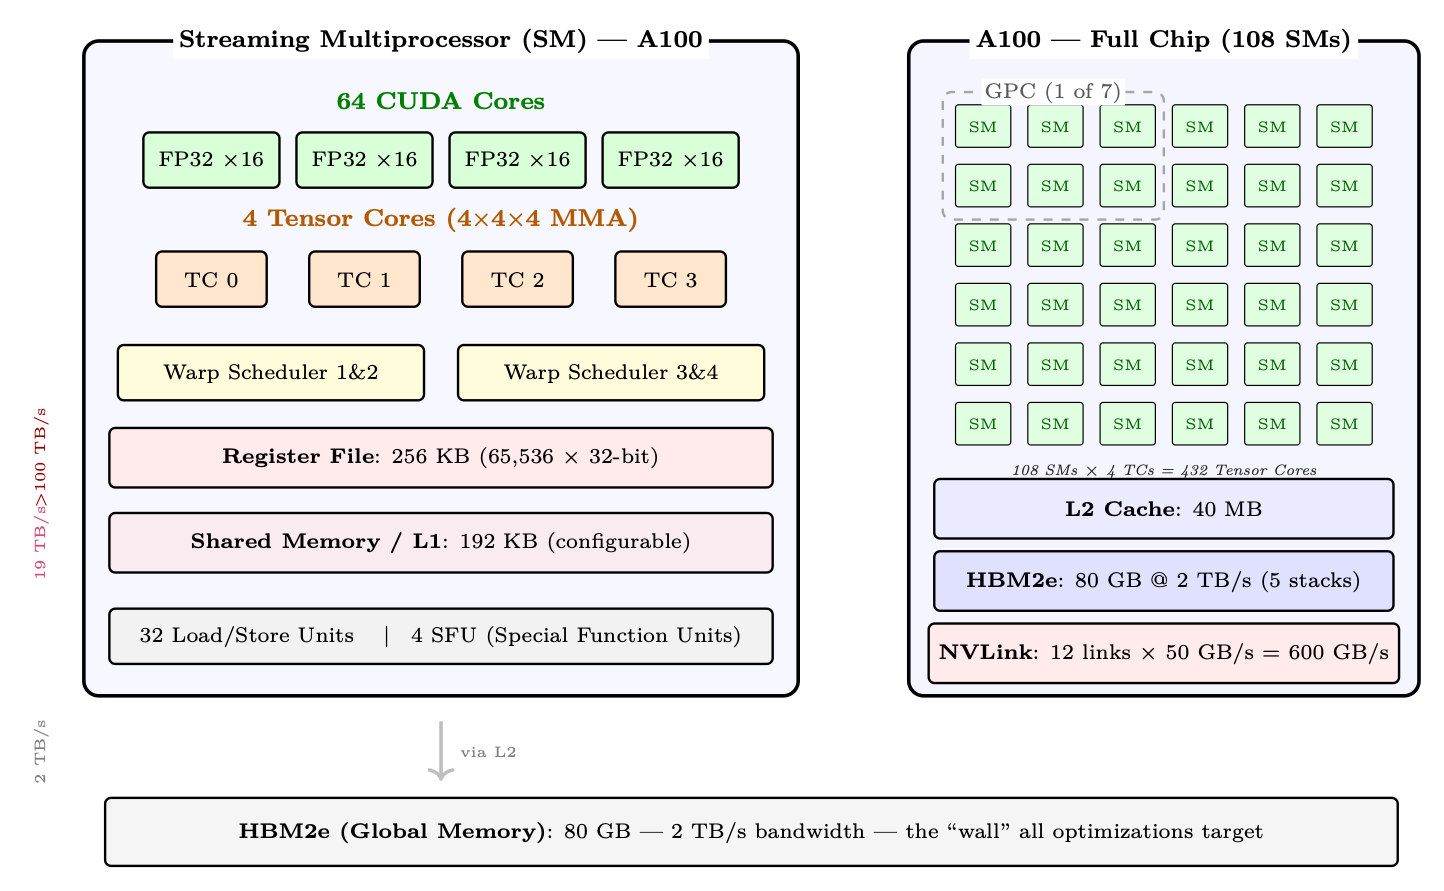
A GPU is organized as an array of Streaming Multiprocessors (SMs), each of which is an independent processor with its own register file, shared memory, and execution units. Understanding SMs is key to understanding GPU performance.
GPU Chip Scaling Across Generations
The evolution of NVIDIA’s GPU architectures shows consistent scaling of compute density, on-chip memory, and specialized units for deep learning:
| Architecture | SMs | TCs/SM | SRAM/SM | L2 | Key Change |
|---|---|---|---|---|---|
| Volta (V100) | 80 | 8 | 128 KB | 6 MB | Introduced Tensor Cores |
| Ampere (A100) | 108 | 4 | 192 KB | 40 MB | BF16/TF32; larger L2 |
| Hopper (H100) | 132 | 4 | 256 KB | 50 MB | TMA; FP8; Thread Block Clusters |
| Blackwell (B200) | 148 | 4 | 256 KB | 128 MB | 2 die; FP4; TMEM; NVLink 5 |
Table 2.3:SM-level scaling across NVIDIA architectures.
GPU Memory Hierarchy and Bandwidth
Modern GPU training and inference performance is almost entirely determined by how well you manage data movement across the memory hierarchy. Understanding the hierarchy is not optional – it is the foundation for every optimization technique discussed in later sections.
Each CUDA thread has access to a private register file. Registers are the fastest storage on the chip – reads and writes happen in a single clock cycle with no arbitration. The A100 has 65,536 32-bit registers per SM. Spilling registers to local memory (L1/L2) is a major performance hazard.
Each SM has a combined L1/shared memory pool of 192 KB on A100 (256 KB on H100), with up to 164 KB configurable as shared memory on A100. Shared memory is explicitly managed by the programmer (or by the compiler in newer CUDA versions). Flash Attention, for example, is entirely built around the insight that the attention tile computation fits in SRAM.
The 40 MB L2 on A100 is shared across all 108 SMs. It acts as a staging area between SRAM and HBM. For workloads with good spatial locality (e.g., weight matrices accessed repeatedly across a batch), L2 hit rates can dramatically reduce effective HBM traffic.
HBM is stacked DRAM mounted directly on the GPU package, connected via a wide interposer. The A100 SXM has 80 GB of HBM2e at 2 TB/s. The H100 SXM5 has 80 GB of HBM3 at 3.35 TB/s. This is the primary working memory for model weights, KV caches, activations, and optimizer states.
Data transfer between GPU HBM and CPU DRAM traverses the PCIe bus. PCIe Gen4 16 provides 32 GB/s per direction (64 GB/s bidirectional); Gen5 doubles this. This is a 60 bandwidth reduction compared to HBM (per-direction). CPU offloading (ZeRO-Infinity, DeepSpeed) exploits this link but must be used carefully to avoid becoming the bottleneck.
NVMe SSDs (e.g., Samsung 990 Pro) reach 7 GB/s sequential read. ZeRO-Infinity can offload optimizer states to NVMe, but this is only viable when the compute-to-IO ratio is very high (large batch sizes, slow training steps).
Arithmetic Intensity and the Roofline Model
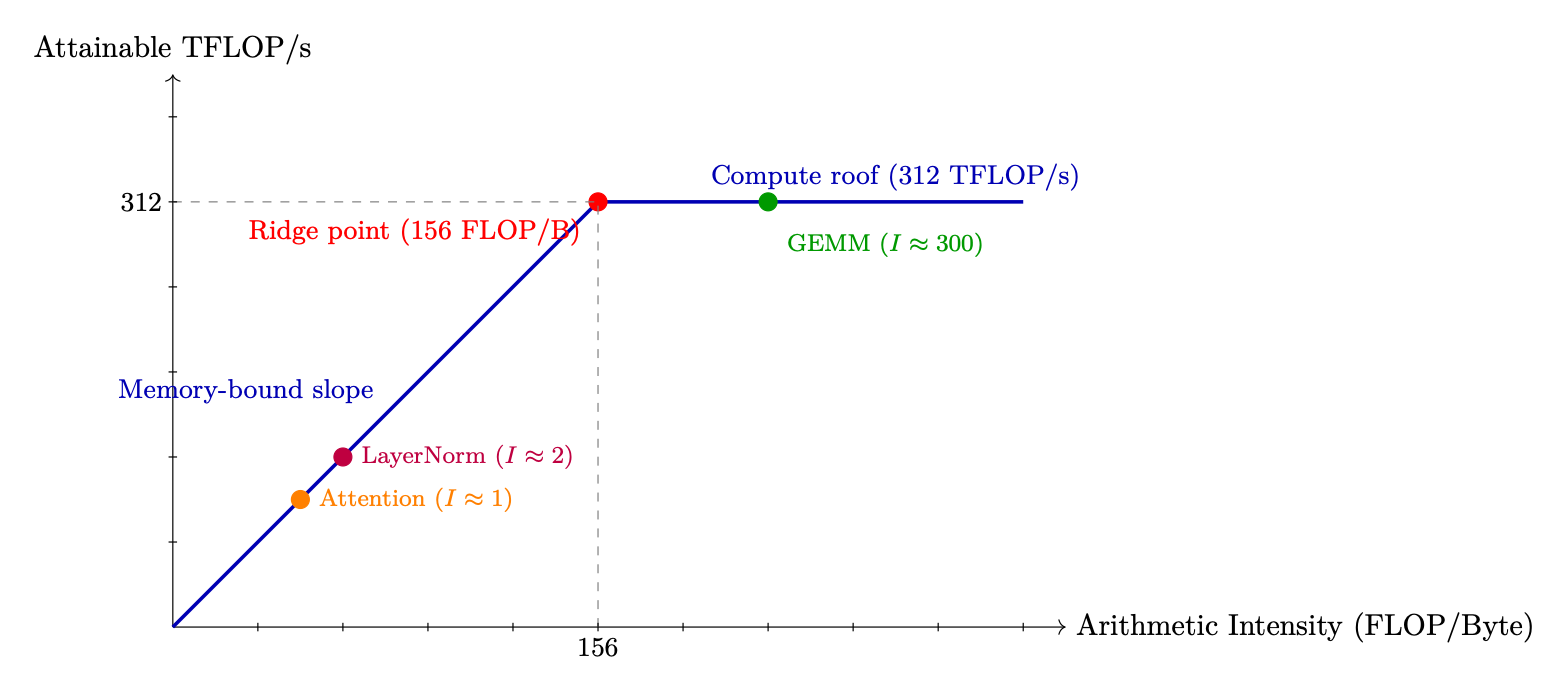
Attention is Memory-Bound; FFN is Compute-Bound
Tensor Cores
- Supported precisions: FP64, TF32, BF16, FP16, INT8, FP8 (H100+).
- Accumulation: Always in FP32 internally, even for BF16 inputs. This prevents catastrophic cancellation during the dot product.
- Requirement: Tensor Cores are most efficient when matrix dimensions are multiples of 8 (BF16) or 16 (FP8). Padding to these multiples is often worthwhile.
- WGMMA (H100): Hopper introduces warpgroup-level MMA instructions that operate on larger tiles (6425616) and can be pipelined with TMA (Tensor Memory Accelerator) data movement.
Communication Architecture – NVLink, InfiniBand, and PCIe
Distributed LLM training and inference require moving enormous amounts of data between GPUs, nodes, and storage. The communication fabric is often the bottleneck for large-scale training.
PCIe is used for:
- CPU GPU data transfers (model loading, CPU offloading)
- Cross-node GPU communication when NVLink is unavailable (rare, very slow)
- NVMe storage access (via CPU)
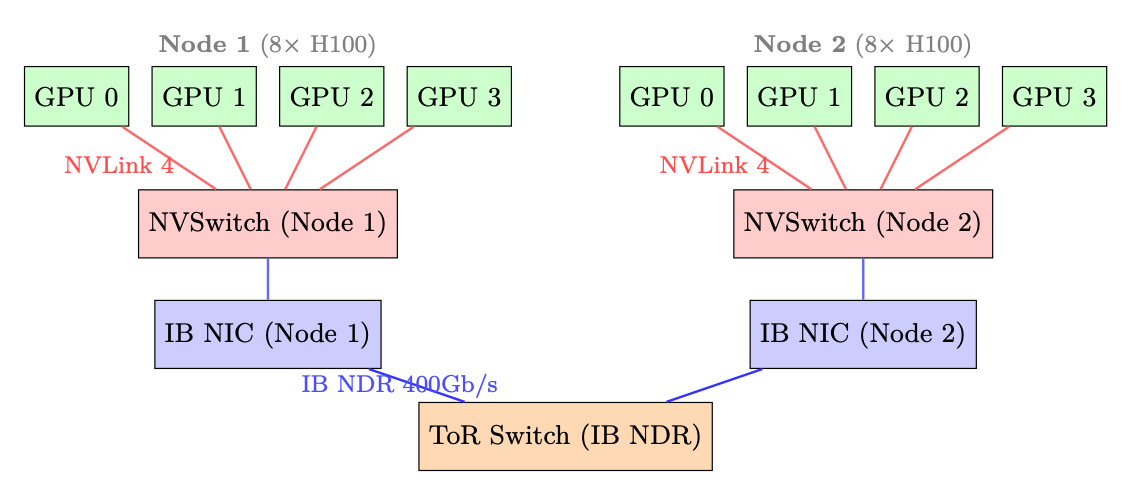
NVLink is a point-to-point interconnect between GPUs on the same node. Each link is bidirectional. The H100 SXM5 has 18 NVLink 4 links, each providing 50 GB/s bidirectional, for a total of 900 GB/s.
In DGX H100 systems, all 8 GPUs are connected via NVSwitch – a dedicated switching chip that provides full bisection bandwidth. This means any GPU can communicate with any other GPU at full NVLink speed simultaneously, not just neighbors in a ring.
For communication between nodes (servers), InfiniBand provides high-bandwidth, low-latency networking with direct GPU memory access.
Large GPU clusters use fat-tree network topologies. A 3-level fat-tree with -port switches supports nodes with full bisection bandwidth. For 400Gb/s NDR switches with ports: nodes.
In practice, clusters use rail-optimized topologies where each GPU in a node connects to a different top-of-rack switch. This ensures that AllReduce operations (which involve all GPUs) use all network links simultaneously, maximizing bandwidth.
Distributed training relies on collective communication primitives. The choice of primitive determines bandwidth requirements and scaling behavior.
The following diagram illustrates a typical two-node GPU cluster topology showing both intra-node (NVLink) and inter-node (InfiniBand) communication paths.
vLLM – PagedAttention and High-Throughput Inference
vLLM [196] introduced PagedAttention, which borrows the paging abstraction that operating systems use for RAM and applies it to the GPU’s KV cache. During LLM inference, the KV cache – the stored key and value tensors for all previous tokens – is the dominant memory consumer. Managing it efficiently is the central challenge of high-throughput inference.
The KV Cache Fragmentation Problem
PagedAttention – Virtual Memory for KV Caches
PagedAttention (Kwon et al., 2023) borrows the paging abstraction from operating systems. Instead of one contiguous block per sequence, the KV cache is carved into fixed-size pages (blocks), and an indirection table—analogous to a CPU page table—translates each sequence’s logical token positions into scattered physical GPU memory addresses.
Benefits of PagedAttention
Internal fragmentation is bounded by at most one partially-filled block per sequence (the last block). With block size 16, worst-case waste is 15 tokens per sequence – negligible. External fragmentation is eliminated because blocks are fixed-size and interchangeable.
Blocks are allocated on demand as the sequence grows. No need to know the final sequence length in advance. This is critical for generation, where output length is unknown.
Multiple sequences sharing a common prefix (e.g., a system prompt) can share the same physical blocks for that prefix. The block table simply points multiple sequences to the same physical blocks. When a sequence needs to write to a shared block (diverging from the prefix), a copy-on-write is triggered.
When GPU memory is exhausted, vLLM can preempt a sequence by swapping its KV blocks to CPU DRAM (or simply discarding them and recomputing later). This is only feasible because blocks are self-contained and non-contiguous – swapping a contiguous allocation would require copying the entire buffer.
Continuous Batching
Traditional batching (“static batching“) waits until all sequences in a batch finish before starting new ones. If one sequence generates 500 tokens and another generates 10, the GPU is idle for 490 steps on the short sequence. This is extremely wasteful.
Speculative Decoding in vLLM
Speculative decoding uses a small draft model (e.g., 1B parameters) to propose candidate tokens quickly, which the large target model verifies in a single forward pass. All tokens up to the first rejection are accepted (expected acceptance: 3–5 tokens per verification step). This yields 2–3 speedup for latency-sensitive single-sequence generation without any quality loss.
vLLM integrates speculative decoding with PagedAttention:
- Draft tokens are allocated speculative KV blocks
- On rejection, speculative blocks are freed (cheap with paged allocation)
- On acceptance, speculative blocks are promoted to the main sequence
- The block table update is – just updating a few table entries
Concrete Memory Savings – 70B Model at Scale
vLLM: End-to-End System
vLLM wraps PagedAttention inside a full serving stack: continuous batching, prefix caching, speculative decoding, and tensor-parallel model sharding all work together to maximize throughput per GPU dollar.
Architecture Overview
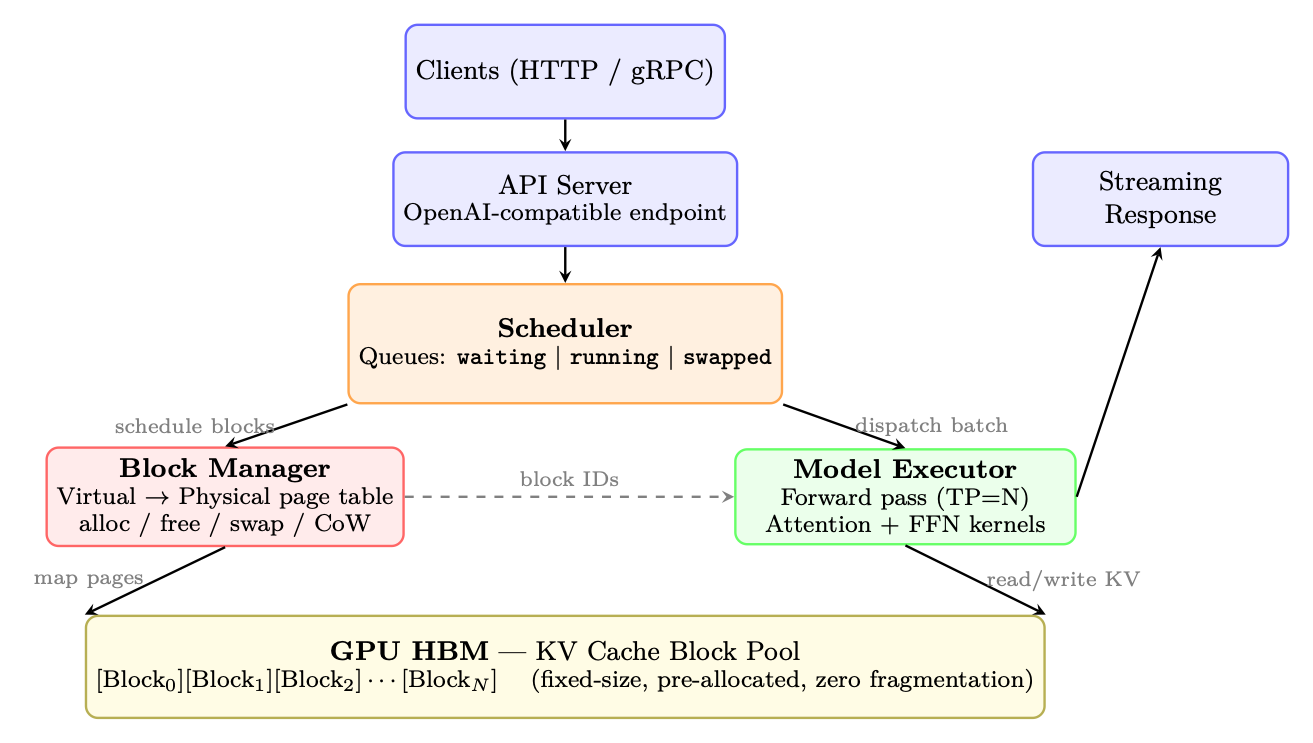
Core Components
- API Server: Accepts OpenAI-compatible requests (completions, chat). Tokenizes inputs and creates “sequence groups” (for beam search or multiple samples).
- Scheduler: The brain of vLLM. Maintains three queues:–
waiting: New requests not yet started (prefill pending)–running: Actively generating tokens (decode phase)–swapped: Preempted requests whose KV cache was offloaded to CPUEach iteration, the scheduler decides which requests to run based on available GPU memory blocks. - Block Manager: Implements the virtual memory abstraction for KV caches. Maps logical blocks (per-sequence) to physical blocks (in GPU memory pool). Handles:–Allocation (new tokens generated new blocks needed)–Copy-on-write (for beam search: multiple beams share prefix blocks, copy only on divergence)–Swap (GPU CPU migration when preempting/resuming)–Prefix caching (reuse cached blocks when prompts share common prefixes)
- Model Executor: Runs the actual LLM forward pass. Manages tensor parallelism across GPUs, dispatches attention kernels that read from paged KV cache blocks.
- KV Cache Pool: Pre-allocated GPU memory divided into fixed-size blocks (default: 16 tokens num_heads head_dim 2 bytes per block). No dynamic allocation at runtime zero fragmentation.
Request Lifecycle (End-to-End Flow)
- Arrival: Client sends prompt. API server tokenizes it, creates a
SequenceGroup, places it in thewaitingqueue. - Scheduling: At each step, the scheduler runs:(a)Check if any
swappedsequences can be resumed (enough free blocks).(b)Check if anywaitingsequences can start prefill (enough blocks for the full prompt).(c)Budget remaining blocks acrossrunningsequences (need 1 new block per sequence per step if current block is full).(d)If over budget: preempt lowest-priority running sequences (swap KV to CPU or recompute later). - Prefill (first iteration for a request): The entire prompt is processed in one forward pass. KV cache is computed for all prompt tokens and stored in allocated blocks. This is compute-bound (large batch of tokens).
- Decode (subsequent iterations): One new token generated per sequence per step. All running sequences are batched together (continuous batching). This is memory-bound (reads full KV cache, generates 1 token).
- Block Allocation: After each decode step, if the last block for a sequence is full, the Block Manager allocates a new physical block and maps it to the next logical block.
- Completion: When a sequence hits EOS or max length, it’s removed from
running. Its physical blocks are freed immediately available for other sequences. Response is streamed back to client.
Prefix Caching (Automatic Prompt Caching)
When multiple requests share a common prefix (system prompt, few-shot examples):
- Hash the token content of each logical block.
- On new request arrival, check if any prefix blocks are already in the cache.
- If hit: skip prefill for those tokens, directly reuse physical KV blocks. Time-to-first-token drops dramatically.
- Eviction: LRU policy. Cached blocks are freed only when memory pressure requires it.
Impact: For chat applications with long system prompts (2K+ tokens shared across all users), prefix caching reduces TTFT by 60–80%.
Guided (Constrained) Decoding in vLLM
vLLM natively supports constrained decoding (Section 1.12.11 Constrained Decoding (Structured Generation)) through pluggable backends, enabling guaranteed structured output at serving time with minimal performance overhead.
The OpenAI-compatible API accepts constraints via the guided_* parameters or the response_format field:
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1")

# --- JSON Schema constraint ---
response = client.chat.completions.create(
    model="meta-llama/Llama-3-70B-Instruct",
    messages=[{"role": "user",
               "content": "Extract: name, age, city from: "
                          "'John is 30 and lives in NYC'"}],
    extra_body={
        "guided_json": {
            "type": "object",
            "properties": {
                "name": {"type": "string"},
                "age": {"type": "integer"},
                "city": {"type": "string"}
            },
            "required": ["name", "age", "city"]
        }
    }
)
# Output is guaranteed valid JSON matching the schema

# --- Regex constraint ---
response = client.completions.create(
    model="meta-llama/Llama-3-70B-Instruct",
    prompt="Generate an IPv4 address: ",
    extra_body={
        "guided_regex": r"\d{1,3}\.\d{1,3}\.\d{1,3}\.\d{1,3}"
    }
)

# --- Choice constraint ---
response = client.completions.create(
    model="meta-llama/Llama-3-70B-Instruct",
    prompt="Sentiment: ",
    extra_body={"guided_choice": ["positive", "negative", "neutral"]}
)
vLLM delegates mask computation to a backend engine:
- XGrammar (default since v0.7): Pushdown-automaton engine supporting JSON schemas, regexes, and arbitrary EBNF grammars. Fastest for complex schemas due to efficient C++ core.
- Outlines[378]: FSM-based; supports JSON and regex. Used as fallback when XGrammar is unavailable.
The mask is applied after the model’s forward pass produces logits and before sampling—adding 1 ms per step in practice, since the FSM/PDA state transition and precomputed index lookup are .
Because the constraint only masks logits (no recomputation of attention or FFN), throughput loss is negligible (2% in benchmarks). The main cost is compilation of the schema into an FSM/PDA index, which takes 0.5–5 s depending on schema complexity. vLLM caches compiled schemas across requests, so this cost is paid once per unique schema.
| Metric | vLLM | HF Generate | Why |
|---|---|---|---|
| Throughput (tok/s) | 2,500–4,000 | 300–600 | Continuous batching + PagedAttention |
| Memory utilization | 90–95% | 50–60% | Zero fragmentation, dynamic block alloc |
| Max concurrent seqs | 200–500 | 16–32 | Paged KV eliminates per-seq reservation |
| Time-to-first-token | 100–300ms | 500–2000ms | Prefix caching for repeated system prompts |
Table 2.4:vLLM performance vs. alternatives (70B model, A100 4, TP=4).
Dynamo [270] is NVIDIA’s open-source orchestration layer that sits above individual inference engines (SGLang, TensorRT-LLM, vLLM) and turns them into a coordinated multi-node serving system. Key capabilities include disaggregated serving (separating prefill and decode phases across specialized node pools), intelligent request routing based on KV cache locality, multi-tier KV caching (GPU CPU SSD), and automatic scaling. It addresses the gap between single-GPU inference optimization (covered by vLLM) and production serving at datacenter scale.