
Reinforcement Learning (RL) is a paradigm where an agent learns to make sequential decisions by interacting with an environment, receiving rewards as feedback, and optimizing its policy to maximize cumulative reward over time [346]. Unlike supervised learning (which requires labeled input-output pairs), RL discovers optimal behavior through trial and error.
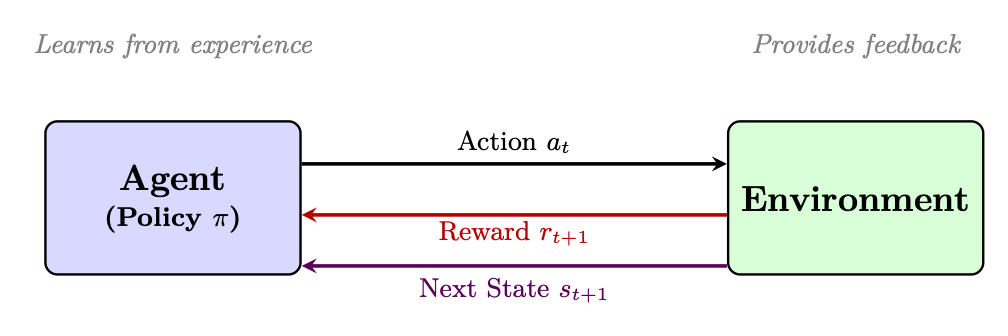
The Markov Decision Process (MDP)
An MDP is a 5-tuple :
- : State space — all possible configurations of the environment
- : Action space — all actions available to the agent
- : Transition function — probability of reaching state from state after taking action
- : Reward function — immediate scalar feedback for a transition
- : Discount factor — how much future rewards are valued relative to immediate ones
The Markov Property: The future depends only on the current state, not the history:
This makes the problem tractable.
Core Concepts and Definitions
Policy: A mapping from states to action probabilities. Deterministic: . Stochastic: .
Return (cumulative discounted reward):
Value Function (expected return from state under policy ):
Action-Value Function (expected return from state , taking action , then following ):
Advantage Function (how much better action is compared to average):
Bellman Equations (recursive relationship):
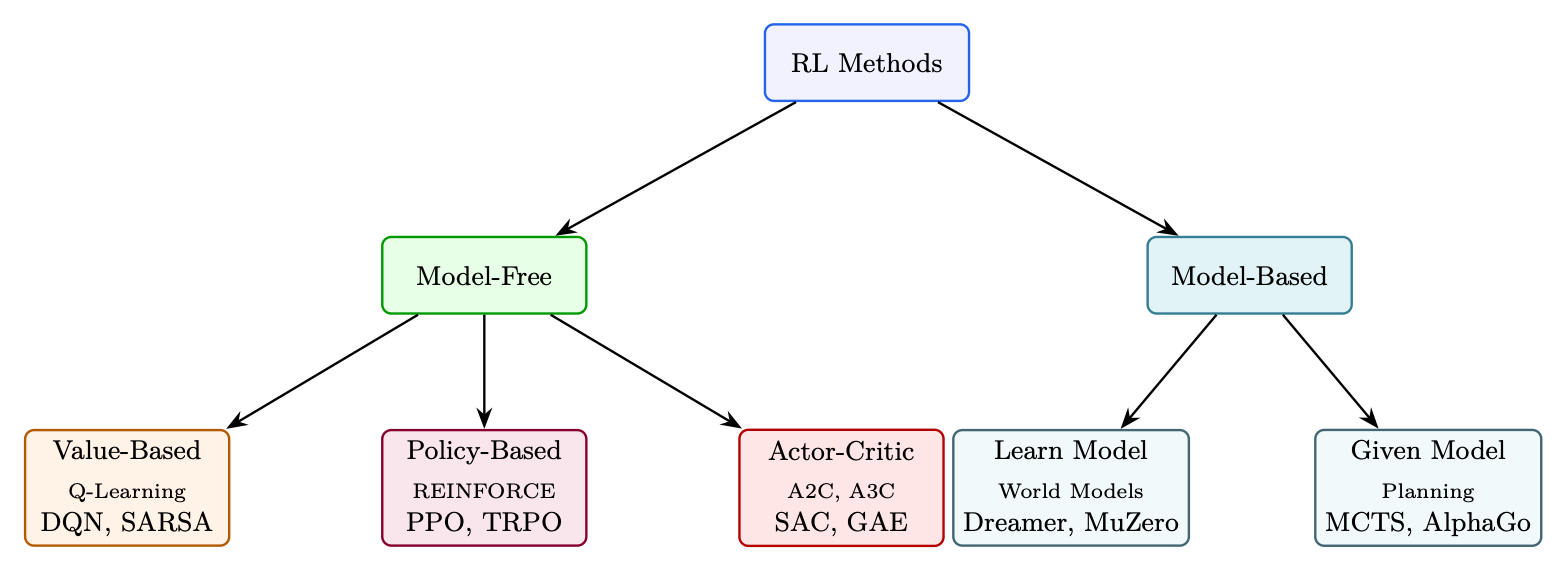
Taxonomy of RL Methods
Reinforcement learning algorithms can be classified along several axes. Understanding this taxonomy helps select the right approach for a given problem.
Temporal Difference (TD) Learning
TD learning [347] bootstraps — it updates value estimates using other value estimates, without waiting for the full episode to end.
Understanding TD Error: “Surprise” as a Learning Signal
TD error measures the discrepancy between an agent’s current estimate of future reward and a newly updated estimate after taking one step. Put simply, it is the difference between what the agent thought would happen and what actually happened plus what it expects next. It represents the agent’s “surprise.”
The TD Error Formula
- : The immediate reward received after taking an action.
- : The estimated discounted value of the next state (what the agent expects to get from the next state onward, scaled by discount factor ).
- : The original estimate of the current state’s value.
The combined term is called the TD Target. Therefore:
How the Agent Uses TD Error
The agent adjusts its value function to drive TD error toward zero:
- If : outcome was better than predicted increase so the agent seeks this state.
- If : outcome was worse than predicted decrease so the agent avoids this state.
- If : prediction was perfect no update needed (convergence).
TD Target: — the “better estimate” we move toward.
Multi-step TD (n-step returns):
Q-Learning
Q-Learning [373] is the foundational off-policy, value-based algorithm. It learns the optimal directly, regardless of the policy being followed.
Update rule:
SARSA[311] (on-policy alternative): Uses the action actually taken instead of the max:
Deep Q-Networks (DQN)[259]: Replace tabular with a neural network . Key innovations: experience replay buffer (off-policy data reuse), target network (stability), -greedy exploration.
DQN Loss Function: The network is trained to minimize the mean squared TD error over mini-batches sampled from the replay buffer:
where is the target network — a frozen copy of updated only every steps (e.g., ). This prevents the moving target problem: without it, both the prediction and the target shift simultaneously, causing divergence.
Gradient update: Taking the gradient of the loss w.r.t. (note: the target is treated as a constant — no gradient flows through ):
Learning scheme (per training step):
- Act: Select action via -greedy: with probability take random action, otherwise . Anneal from 1.0 0.01 over first 1M steps.
- Store: Save transition in replay buffer (capacity 1M).
- Sample: Draw mini-batch of 32 transitions uniformly from .
- Compute target: (zero future value if terminal).
- Update: Gradient descent on . Clip gradients to (Huber loss variant).
- Sync target: Every steps, copy .
Understanding Replay Buffers
A replay buffer[220] (experience replay) is a data storage mechanism that saves past experiences so an agent can relearn from them later. Instead of discarding data immediately after an action, the agent stores transitions in a memory bank and samples random mini-batches for training.
What’s stored: Each transition is a tuple:
where is a boolean flag indicating if the episode ended.
import random
from collections import deque

class ReplayBuffer:
    def __init__(self, capacity):
        self.buffer = deque(maxlen=capacity)  # Bounded queue

    def push(self, state, action, reward, next_state, done):
        self.buffer.append((state, action, reward, next_state, done))

    def sample(self, batch_size):
        # Break correlation by selecting random experiences
        return random.sample(self.buffer, batch_size)

    def __len__(self):
        return len(self.buffer)
Policy Gradient Methods — REINFORCE
Instead of learning a value function and deriving a policy, directly optimize the policy parameters to maximize expected return [379].
Objective:
Policy Gradient Theorem:
REINFORCE Algorithm[379] (Williams, 1992):
- Sample complete trajectory under
- Compute return for each time step
- Update:
Variance Reduction with Baseline:
Any baseline that doesn’t depend on keeps the gradient unbiased but reduces variance. Best choice: . Then = advantage.
Actor-Critic Methods
Combine policy gradient (actor) with learned value function (critic) to reduce variance while maintaining the flexibility of policy optimization.
Architecture:
- Actor: The policy. Proposes actions.
- Critic or : Evaluates how good a state/action is. Provides low-variance baseline.
Actor update (using advantage from critic):
Critic update (minimize TD error):
Generalized Advantage Estimation (GAE)
Motivation: The Actor-Critic framework needs a good estimate of the advantage — how much better was this action than average? But there’s a fundamental tension:
- 1-step TD advantage (): Low variance (only one random step), but biased — if the value function is wrong, the advantage estimate is systematically off.
- Monte Carlo advantage (): Unbiased (uses actual returns), but high variance — the sum of many random rewards fluctuates wildly between episodes.
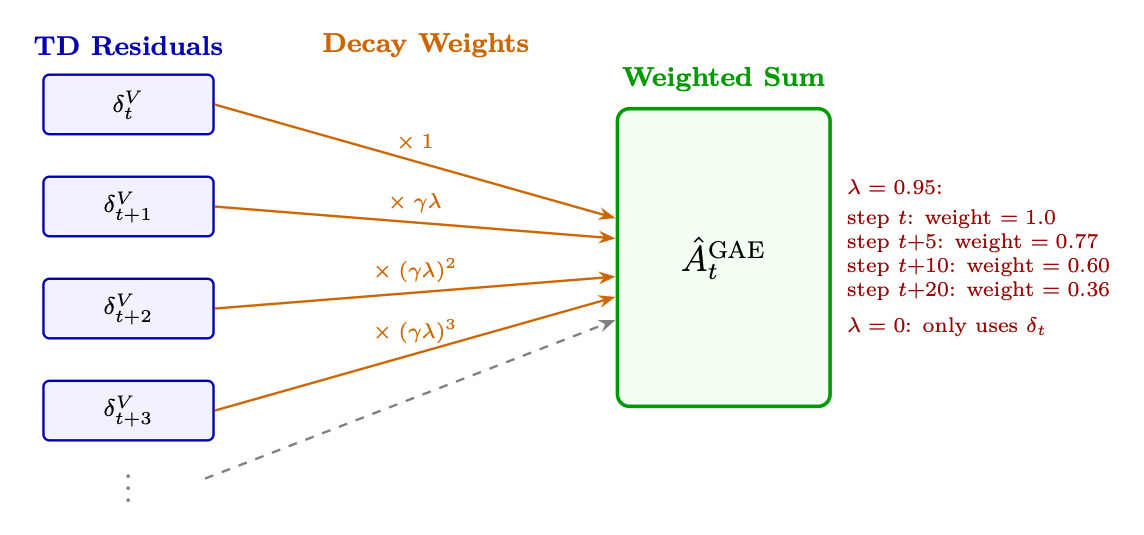
GAE [318] (Schulman et al., 2016) provides a smooth interpolation between these extremes via a single parameter . It takes an exponentially-weighted average of -step advantage estimates for all , giving a principled way to trade bias for variance.
Core idea: Compute the 1-step TD error at each timestep, then blend them with exponentially decaying weights — recent TD errors get full weight, distant ones are down-weighted:
Intuitive Mapping of Bias and Variance in GAE
In supervised learning, bias and variance stem from structural model assumptions. In reinforcement learning via GAE, they stem from how much you trust a flawed model versus how much you trust a chaotic environment:
- Bias (Systemic Misalignment): Arises when the estimator relies on the structural assumptions and imperfect predictions of the value network . If is under-trained or lacks capacity, the baseline guesses are systematically wrong.
- Variance (Sample Jitteriness): Arises when the estimator relies on long, unconstrained environmental trajectories. Stochastic transitions, random seeds, and policy execution noise accumulate over long horizons, causing empirical sample rewards to swing wildly between rollouts.
The Architectural Spectrum: Boundary Analysis
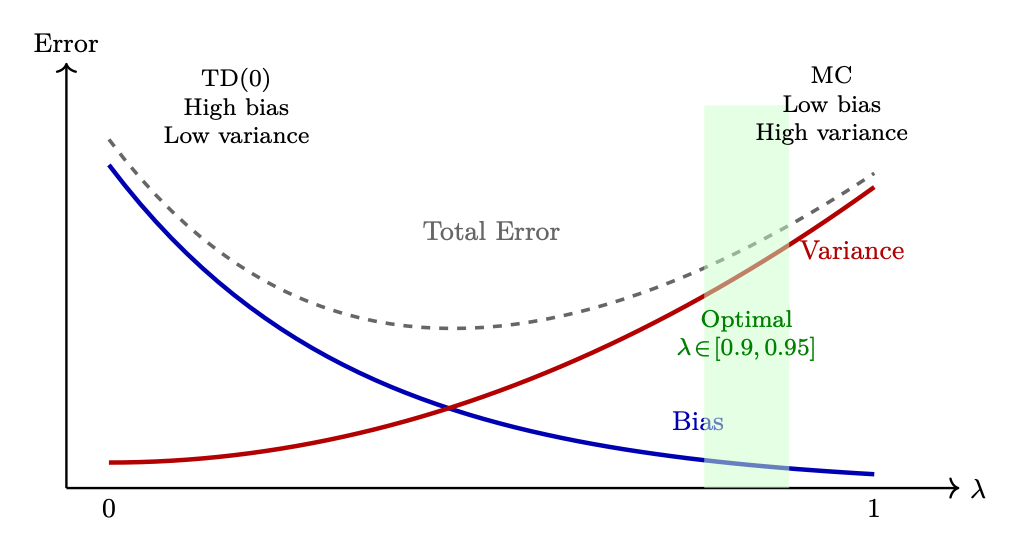
The hyperparameter serves as a slide-rule between two fundamental estimation paradigms.
The Trade-off Matrix
By selecting , GAE minimizes the total mean squared error of the advantage estimate:
| Configuration | Statistical Properties | Core Reliance | Practical Risk |
|---|---|---|---|
| High Bias, Low Variance | Model parameters () | Policy traps in sub-optimal local minima | |
| Balanced (Optimal MSE) | Hybrid blending | Requires tuning based on environment stochasticity | |
| Low Bias, High Variance | Empirical environment rollout | Destructive gradient updates; training explosion |
Table 3.1:Operational comparison of GAE parameter choices.
Diagnostics for Tuning λ\lambda
Monitoring training curves yields direct insight into whether bias or variance dominates:
- High Variance Indicators: Policy entropy drops precipitously while explained variance of the value function becomes highly negative or erratic policy updates are noisy. Remedy: Lower to smooth target updates.
- High Bias Indicators: Agent achieves early stable training but completely fails to discover complex delayed reward sequences under-estimating long-horizon dependencies due to bootstrapping. Remedy: Raise closer to to expose policy to real downstream trajectory signals.
On-Policy vs Off-Policy — Detailed Comparison
On-PolicyOff-PolicyData sourceCurrent policy onlyAny policy (replay buffer)After updateOld data is invalid, must regenerateOld data still usableSample efficiencyLow (data used once)High (data reused many times)StabilityMore stable (consistent distribution)Can diverge (distribution mismatch)ExamplesREINFORCE, PPO, A2C, GRPOQ-Learning, DQN, SAC, DPOFor LLMsPPO, GRPO (generate fresh each step)DPO (static preference dataset)
Model-Based vs Model-Free
Model-FreeModel-BasedWhat’s learnedPolicy and/or value / directlyEnvironment model PlanningNo planning, reactive decisionsCan simulate future trajectoriesSample efficiencyLow (must experience everything)High (can plan in imagination)AccuracyNo model biasModel errors compoundWhen to useComplex/unknown dynamicsSimple dynamics, need efficiencyExamplesPPO, DQN, SAC [129]MuZero [316], Dreamer [130], AlphaGo [331]
Reward Shaping
Reward shaping[265] is a technique where a developer modifies or supplements the environment’s original reward function. Its primary objective is to transform a sparse reward scenario — where the agent receives feedback only upon final task completion — into a dense reward scenario with intermediate feedback signals to accelerate convergence.
The Mathematical Framework
Let the original reward at time step be . The reshaped reward adds an auxiliary shaping function :
Potential-Based Reward Shaping (PBRS)
To mathematically guarantee that reshaping does not alter the optimal policy, use Potential-Based Reward Shaping. The shaping function is constrained to the difference in a scalar potential function across states:
where is a real-valued potential function evaluating the desirable proximity of a state to the goal, and is the discount factor.
The complete PBRS reward: