
Group Relative Policy Optimization (GRPO) [323] is a reinforcement learning algorithm designed specifically for language models that eliminates the need for a separate value network (critic). Introduced by DeepSeek as part of their DeepSeekMath work and later scaled to DeepSeek-R1 [69], GRPO has rapidly become the dominant RL method for LLM training—adopted by most open-source alignment frameworks (TRL, OpenRLHF, veRL) as the default algorithm.
The core idea is deceptively simple: instead of training a neural network to predict expected reward (the critic in PPO), GRPO estimates it empirically by generating multiple responses to the same prompt and using the group’s reward statistics as a baseline. This removes an entire model from memory, halves the engineering complexity, and—surprisingly—often outperforms PPO because empirical baselines are more accurate than a poorly-trained value function.
GRPO is particularly effective for:
- Reasoning tasks with verifiable rewards (math, code) where binary correctness provides a clean signal.
- Large models (70B+) where the memory savings from removing the critic are critical.
- Multi-turn and agentic settings where value estimation across tool calls is intractable.
This chapter covers GRPO’s motivation, algorithm, key variants (Dr. GRPO, DAPO, 2-GRPO, GDPO), and practical implementation with TRL.
Motivation
PPO’s value model (critic) has three major problems for language:
- Memory: The value head shares the policy backbone (140GB for 70B). Doubles memory if separate.
- Accuracy: Predicting expected reward for a partial sequence is extremely hard. The value function is often wrong wrong advantages wrong gradient direction.
- Training: Value head needs many samples to converge. During early RL, it gives noisy predictions that destabilize policy learning.
GRPO’s key insight[323]: Instead of learning , estimate it empirically from a group of samples. Generate responses to the same prompt, compute their rewards, and use the group statistics as the baseline.
Algorithm
- For each prompt , sample completions:
- Score each:
- Normalize within group: where ,
- Apply PPO-style clipped update using these advantages
TRL Implementation
The following shows a minimal working example using HuggingFace TRL.
from trl import GRPOConfig, GRPOTrainer
from transformers import AutoModelForCausalLM, AutoTokenizer

model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen2.5-7B-Instruct",
    torch_dtype=torch.bfloat16, attn_implementation="flash_attention_2")
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2.5-7B-Instruct")

grpo_config = GRPOConfig(
    output_dir="./grpo_output",
    num_generations=8,           # G = group size
    temperature=1.0,             # High temp for diversity within group
    max_completion_length=2048,  # Max response length
    beta=0.04,                   # KL penalty coefficient
    learning_rate=1e-6,
    per_device_train_batch_size=2,  # Prompts per device (x8 gens = 16 responses)
    gradient_accumulation_steps=8,
    num_train_epochs=2,
    bf16=True,
    gradient_checkpointing=True,
    max_grad_norm=0.5,
    logging_steps=10,
    # vLLM generation for speed (critical for GRPO due to 8x generation)
    use_vllm=True,
    vllm_gpu_memory_utilization=0.7,
)

# Reward function: binary correctness for math
def reward_fn(completions, prompts, **kwargs):
    """Return list of floats: 1.0 if correct, 0.0 if wrong."""
    rewards = []
    for completion, prompt in zip(completions, prompts):
        answer = extract_answer(completion)
        expected = get_ground_truth(prompt)
        rewards.append(1.0 if answer == expected else 0.0)
    return rewards

# Can combine multiple reward functions!
def format_reward_fn(completions, **kwargs):
    """Bonus for using proper LaTeX formatting."""
    return [0.5 if "\\boxed{" in c else 0.0 for c in completions]

trainer = GRPOTrainer(
    model=model,
    args=grpo_config,
    reward_funcs=[reward_fn, format_reward_fn],  # Multi-objective!
    train_dataset=math_dataset,
    tokenizer=tokenizer,
)
trainer.train()
Group Size Analysis
Signal QualityComputeWhen to Use2Very noisy (coin flip)LowNever recommended — too noisy for stable learning4ModerateModerateQuick experiments, easy tasks (pass rate 50%)8Good (standard)HighDefault. Good balance for most tasks16ExcellentVery highHard tasks (pass rate 20%), need many attempts to get positives32Near-perfectExtremeOnly if you have massive compute and very hard task
GRPO Variants and Extensions
Diversity in GRPO Groups
| Method | How It Promotes Diversity |
|---|---|
| Entropy bonus | Add to the reward. Directly penalizes low-entropy (deterministic) policies. |
| KL penalty | prevents collapse toward a single mode. |
| Rejection sampling | Generate many candidates, keep top- by reward. Naturally selects for diverse high-quality responses. |
| Best-of-N | At inference: generate responses, score all, return the best. Diversity comes from sampling. |
| DPO with diverse pairs | Train on pairs where chosen/rejected differ in approach, not just quality. |
| Multi-reward | Use multiple reward models (safety, helpfulness, code quality). Prevents collapsing to one dimension. |
Table 7.1:Diversity-promoting methods for RL training.
Post-training alignment (RLHF, DPO) often reduces output diversity due to typicality bias: human annotators systematically prefer familiar, “typical” text over novel alternatives. This mode collapse is a data-level phenomenon, not purely algorithmic.
Verbalized Sampling (VS) [422] is a training-free prompting strategy that circumvents this collapse by asking the model to explicitly verbalize a probability distribution over multiple responses in a single generation.
# Verbalized Sampling: prompt model to output distribution
def verbalized_sample(model, tokenizer, task, n=5):
    prompt = (
        f"{task}\n\n"
        f"Generate {n} different responses and assign a probability "
        f"to each (probabilities should sum to 1.0). "
        f"Format: [response] (probability: X.XX)"
    )
    output = model.generate(
        tokenizer(prompt, return_tensors="pt").input_ids,
        max_new_tokens=1024,
        temperature=0.7,
        do_sample=True,
    )
    # Parse responses and probabilities from output
    responses, probs = parse_verbalized_distribution(
        tokenizer.decode(output[0])
    )
    # Sample from the verbalized distribution
    import random
    chosen = random.choices(responses, weights=probs, k=1)[0]
    return chosen
Before diving into the extensions, let us briefly recap the base GRPO algorithm established in the previous sections. The core mechanism—sampling a group of completions, normalizing their rewards, and applying a clipped policy gradient—is elegant in its simplicity. However, practitioners quickly discovered specific failure modes: pretraining bias diluting gradients (Dr. GRPO), symmetric clipping limiting exploration (DAPO), wasteful large group sizes (2-GRPO), and reward-scale imbalance in multi-objective settings (GDPO). The following sections address each of these in turn.
DAPO – Dynamic Adaptive Policy Optimization
Standard PPO/GRPO clips the importance ratio symmetrically at . DAPO replaces this with an asymmetric band:
where (typical values: , ). When the advantage is positive the policy is allowed to move further toward the good token; when the advantage is negative the usual conservative clipping applies to avoid over-suppression.
Base GRPO divides the loss by the number of sequences. DAPO divides by the total number of tokens across all sequences:
This prevents long completions from dominating the gradient signal simply because they contain more tokens.
When a completion is truncated (no EOS token within the maximum length budget), it provides misleading signal: the model is penalised for tokens that were generated correctly but happened to appear before the truncation boundary. DAPO masks these completions entirely:
Rather than a hard mask, a softer variant applies a length penalty that grows smoothly as completions approach the maximum length :
where is a “safe” length threshold.
DAPO re-samples prompts whose entire group of completions receives the same reward (all correct or all incorrect), because such groups contribute zero gradient after normalisation. This keeps the effective batch size stable throughout training.
GSPO – Group Sequence Policy Optimization
GSPO [51] defines a sequence-level importance weight as the geometric mean of per-token ratios, which equals the -th root of the full sequence probability ratio:
This is the length-normalised sequence probability ratio. The GSPO loss clips this single scalar per sequence:
Dr. GRPO – Debiased Reward GRPO
Dr. GRPO modifies the per-token gradient weight to account for the token’s marginal contribution to the reward signal. Tokens that the model already assigns high probability to (regardless of the reward) are down-weighted:
where is the reference (pretrained) model. This is a form of token efficiency: the gradient is concentrated on tokens where the policy genuinely needs to change.
2-GRPO – Minimal Two-Rollout GRPO
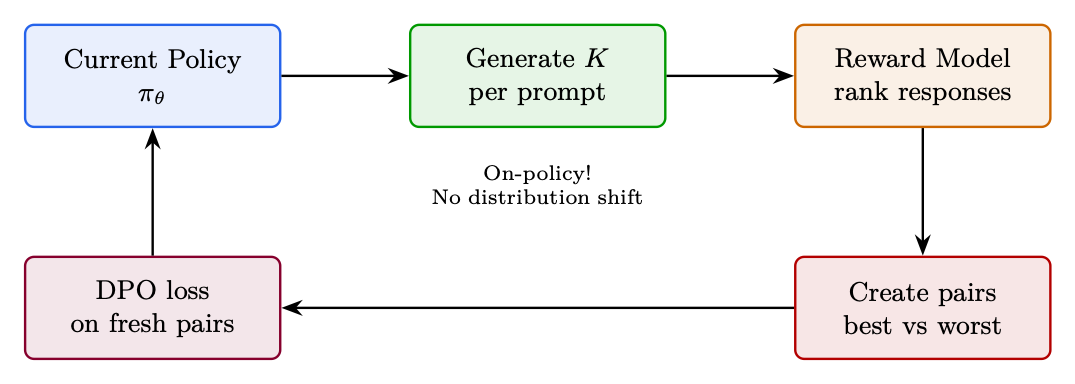
The key insight is that GRPO’s effectiveness does not primarily come from accurate advantage estimation (which requires large ). Instead, it comes from an implicit contrastive objective that is structurally similar to DPO:
where is the higher-reward completion and the lower-reward one. With , this contrastive structure is explicit. With , the same signal is present but diluted by redundant pairs.
SAPO – Soft Adaptive Policy Optimization
SAPO replaces the objective with a smooth surrogate:
where is the sigmoid function and are asymmetric temperature parameters. A higher temperature produces a softer gate (more exploration); a lower temperature approaches hard clipping.
TIS and MIS – Truncated and Masked Importance Sampling
TIS corrects the bias by multiplying the gradient by a truncated correction factor:
where is the probability from the training forward pass and is the probability reported by vLLM. The truncation at prevents extreme corrections from destabilising training.
MIS takes a harder approach: it zeros out the gradient for any sequence where the correction ratio exceeds a threshold :
This is more conservative but avoids the risk of large (even truncated) correction weights.
Both TIS and MIS can be applied at the token level or the sequence level:
- Sequence-level: compute the ratio as the geometric mean over all tokens (as in GSPO). Theoretically correct but higher variance.
- Token-level: compute a separate ratio for each token. Biased (the product of per-token corrections is not the sequence correction) but lower variance.
VESPO – Variational Sequence-Level Soft Policy Optimization
VESPO derives a weighting function for each trajectory from the variational objective. The final gradient weight takes the form:
where is the sequence-level importance weight, controls the sharpness of the weighting, and controls the exponential decay for stale (low-weight) trajectories. This kernel:
- Is smooth everywhere (no discontinuous gradient at clip boundaries).
- Naturally down-weights stale trajectories () via the exponential term.
- Is asymmetric: high-weight trajectories () are treated differently from low-weight ones.
DPPO – Direct Policy Divergence Policy Optimization
DPPO computes the trust region constraint directly using either Total Variation (TV) or KL divergence between the old and new policy distributions:
where is the chosen divergence measure. In practice, DPPO approximates this with token-level binary or top- masks:
- binary_tv: mask tokens where .
- binary_kl: mask tokens where .
- topk_tv: keep only the top- tokens by TV contribution.
- topk_kl: keep only the top- tokens by KL contribution.
ScaleRL and CISPO
Standard GRPO normalises rewards within a group of completions for a single prompt. CISPO normalises rewards across the entire batch:
where and are computed over all rewards in the current training batch. This provides a more stable baseline and prevents any single prompt from dominating the gradient.
CISPO combines batch-level scaling with DAPO’s token-level loss aggregation and asymmetric clipping:
where is the overlong-filtering mask.
GDPO – Group Reward-Decoupled Policy Optimization
The core mechanism normalises each reward independently before aggregating:
where is the -th reward for completion , and are the mean and standard deviation of reward within the group, and are user-specified weights.
GOPO – Group Ordinal Policy Optimization
GOPO [54] starts from a simple observation: reward models are trained with pairwise comparisons (“is A better than B?”), so only the rank order of their outputs is trustworthy—the raw numeric scores carry no inherent meaning. Yet GRPO feeds those raw magnitudes directly into the advantage calculation. For tasks with non-verifiable rewards—summarization, open-ended chat, instruction following—this mismatch introduces noise, because a gap of 0.6 reward points might reflect genuine quality in one region of the output space and mean nothing in another.
Key Insight: Discard reward magnitudes entirely. Use only the ordinal ranking of rewards within a group.
Algorithm: Given a group of responses with rewards :
- Rank responses by reward: assign rank (1 = worst, = best).
- Replace raw advantages with rank-based scores:(7.2)where is a monotonic transformation (e.g., linear mapping to or quantile normalization).
- Apply PPO-style clipped objective using rank-based advantages.
Comparison with GRPO:
AspectGRPOGOPOAdvantage signal (uses magnitudes) (uses ordinal rank only)Sensitivity to reward scaleHigh — miscalibrated RM scores distort advantagesNone — invariant to monotonic reward transformationsBest forVerifiable rewards (binary, well-calibrated)Non-verifiable rewards (RM-based, noisy magnitudes)
Empirical gains (over GRPO on non-verifiable tasks):
- Reward curves (both training and held-out) sit above GRPO throughout optimization
- Win-rates judged by a separate LLM evaluator improve at most training checkpoints
- Convergence is markedly faster—matching GRPO’s final quality with fewer gradient steps
- The advantage grows as the reward model becomes noisier or more poorly calibrated