
Motivation: From Chatbots to Autonomous Agents
Modern LLMs are increasingly deployed not just as conversational assistants but as autonomous agents that interact with external tools, APIs, databases, and environments over multiple steps. This shift—from single-turn chatbots to multi-step agents—introduces fundamentally new RL challenges that require rethinking how we train, evaluate, and deploy language models.
The key differences that demand new RL approaches:
- Multi-step reasoning: Agents must plan across 10–100+ tool calls, not just generate a single response.
- External environment feedback: Rewards come from real-world execution (test suites pass, web pages load, code compiles) — not just human preference scores.
- Structured actions: Actions are not just tokens but structured outputs (JSON tool calls, API payloads, code blocks).
- Long horizons with sparse rewards: Success/failure may only be determined after many intermediate steps.
Trajectory Buffers for LLM Agents
In the context of LLM agents, traditional RL replay buffers undergo a structural transformation. Instead of storing low-dimensional numerical tensors, agentic buffers — often called Trajectory Buffers, Experience Pools, or Memory Banks — manage complex textual histories, tool execution outputs, and explicit reasoning steps.
Mathematical Structure of an LLM Agent Buffer
In classic RL, a replay buffer stores a flat tuple . For an LLM agent, this expands into high-dimensional tokenized text structures:
- : The complete context state — system prompt, user objective, conversation history, and current environmental variables (e.g., HTML source code, directory structures, database schemas).
- : The agent’s generated output, typically composed of a Chain-of-Thought (CoT) reasoning string followed by a structured tool call:(12.2)
- : Evaluation signals derived from external execution environments (unit test passes, compiler flags, API response codes) or verified by an LLM-as-a-judge system.
- : The updated context window, which appends tool output text or error logs directly into the conversation history.
Operational Paradigms
LLM agents leverage specialized trajectory buffers through three primary optimization methodologies:
A. Self-Correction and Thought Refinement
Two representative methods in this category are STaR [419] and Reflexion [326]. When an agent fails a multi-step execution trace, the sub-optimal sequence is saved to the buffer. The framework later samples this trajectory and prompts the LLM to generate an explicit textual critique of its past performance:
Once a corrected trajectory achieves a positive reward, it is moved to an optimal experience pool used to update the network weights via fine-tuning (SFT on successful trajectories) or RL (GRPO [323] with binary pass/fail rewards).
B. Off-Policy Exploration
This paradigm, exemplified by ReAct [409] and related tool-use frameworks, involves extensive autonomous exploration. During autonomous exploration (web navigation, database querying, code generation), agents log thousands of exploratory execution paths. The trajectory buffer acts as a filter:
- Success filtering: Only trajectories achieving the goal are kept for training.
- Efficiency ranking: Among successful traces, prefer the shortest/most efficient tool-use paths.
- Diversity sampling: Maintain a diverse set of solution strategies to prevent mode collapse.
The optimization algorithm (typically GRPO [323] or filtered SFT) computes losses exclusively over efficient, successful trajectories while discarding meandering runs.
C. Non-Parametric In-Context Learning (RAG over Experiences)
Instead of modifying neural network weights, the trajectory buffer can function as a vector database. Given a new user goal , the system retrieves the most relevant past experiences:
The top- similar successful historical runs are injected directly into the prompt context as few-shot demonstrations. This approach:
- Requires zero training — pure retrieval-augmented generation
- Adapts instantly to new tasks if similar experiences exist in the buffer
- Scales with buffer size (more experiences = better coverage)
- Complements parametric learning (use retrieval for rare cases, weights for common patterns)
Paradigm Comparison
| Feature | Traditional RL Buffer | LLM Agent Buffer |
|---|---|---|
| Data Format | Continuous vectors / tensors | Tokenized text, JSON, code blocks, tool outputs |
| Data Volume | Massive (– items) | Small to medium (– traces) |
| Primary Goal | Breaking data correlation | Providing reasoning demonstrations |
| Sampling | Random uniform / PER | Semantic retrieval / success priority / diversity |
| State Size | Fixed (e.g., 8484 pixels) | Variable (1K–128K tokens per state) |
| Action Space | Discrete/continuous vectors | Structured text (reasoning + tool calls) |
| Reward Source | Environment simulator | External execution / LLM judge / unit tests |
Table 12.1:Traditional RL Buffers vs. LLM Agent Buffers
Major Techniques in Agentic RL
| Method | Type | Key Idea |
|---|---|---|
| STaR[419] | Iterative SFT | Bootstrap reasoning by fine-tuning on own successful traces |
| Reflexion[326] | In-context RL | Verbal self-critique stored as episodic memory; no weight updates |
| ReAct[409] | Prompting | Interleave reasoning (“think”) and acting (“tool call”) in a single generation |
| LATS[438] | Tree search | Monte Carlo Tree Search over action sequences; backpropagate rewards |
| AgentQ[294] | Off-policy RL | DPO on agent trajectories with AI-generated preference pairs |
| OpenHands[366] | GRPO | Group-relative optimization with execution-based rewards (tests pass/fail) |
| Voyager[362] | Skill library | Successful code snippets stored and retrieved for compositional reuse |
| RLEF[201] | Online RL | RL from Execution Feedback — binary reward from code/test execution |
Table 12.2:Key methods for training LLM agents with RL.
STaR: Self-Taught Reasoner (Detailed)
STaR [419] is an iterative self-improvement method that bootstraps reasoning capabilities without external reward models. The core insight: if the model can occasionally solve a problem correctly, it can learn from its own successes.
Algorithm:
- Generate: For each problem in dataset , sample a reasoning trace followed by an answer .
- Filter: Keep only traces where (correct answer). Define success set .
- Rationalization (key innovation): For problems where the model failed, generate a “rationalization” — a trace conditioned on the correct answer: . This teaches the model to reason backward from solutions.
- Fine-tune: Update via SFT on .
- Iterate: Repeat from step 1 with the improved model.
Convergence dynamics: Each iteration increases the model’s solve rate . If (solves 30% of problems), after rationalization + SFT, . Typically converges in 3–5 iterations to –.
Reflexion: Verbal Reinforcement Learning (Detailed)
Reflexion [326] introduces a radical paradigm: RL without weight updates. Instead of gradient-based learning, the agent improves through natural-language self-critique stored in an episodic memory.
Full Architecture:
- Actor: The LLM agent that executes actions in the environment.
- Evaluator: A binary signal (task success/failure) or a scalar heuristic (e.g., number of test cases passed).
- Self-Reflection Generator: Given the failed trajectory and environment feedback, generates a natural-language reflection :(12.6)
- Episodic Memory: A sliding window buffer of past reflections (typically to fit in context).
- Retry Loop: On the next attempt, reflections are injected into the prompt:(12.7)
Example reflection: “In my previous attempt, I called the search API before validating the input format, which caused a 400 error. Next time, I should validate the JSON schema first, then make the API call.”
Strengths and Limitations:
StrengthsLimitationsZero gradient computation; works with frozen API models (GPT-4)Limited to context window; can’t accumulate infinite knowledgeFast iteration (seconds per retry vs. hours for RL training)No generalization to unseen tasks (memory is task-specific)Interpretable: human-readable self-correctionsRelies on the model’s existing ability to identify errorsComposes with any base agent architectureDegrades when base model is too weak to generate useful critiques
ReAct: Reasoning + Acting (Detailed)
ReAct [409] establishes the dominant prompting paradigm for tool-using agents by interleaving explicit reasoning steps with environment actions in a single generation stream.
Generation format:
Formal definition: A ReAct trajectory is where:
- : Thought (internal reasoning, not executed)
- : Action (tool call, executed in environment)
- : Observation (environment response, appended to context)
Why it works: Thoughts create an “inner monologue” that helps the model plan before acting, reducing impulsive tool calls. The explicit reasoning trace also makes the agent’s decision process auditable and debuggable.
Training ReAct agents with RL:
- Action-level rewards: Only actions receive reward signals (thoughts are auxiliary).
- Thought quality: Implicitly optimized — better thoughts better actions higher rewards.
- Format enforcement: Include format penalties in the reward for malformed actions (missing JSON, hallucinated tools).
- RL objective:
LATS: Language Agent Tree Search (Detailed)
LATS [438] applies Monte Carlo Tree Search (MCTS) to LLM agent action selection, trading inference compute for significantly better trajectories.
Algorithm (adapted for LLM agents):
- Selection: Starting from root (initial state), traverse the tree using UCB1:(12.8)where = average reward of subtree, = visit counts, = exploration constant.
- Expansion: At a leaf node, generate candidate actions via LLM sampling (temperature ):
- Simulation: For each candidate, execute the action in the environment and continue with a fast rollout policy (greedy decoding) until terminal state or depth limit.
- Backpropagation: Propagate the terminal reward up through all ancestor nodes, updating and counts.
- Repeat: Run steps 1–4 for a fixed computation budget (e.g., 50–200 iterations).
- Action selection: Choose the most-visited child of the root.
LLM-specific adaptations:
- Value function: Use a separate LLM call to estimate state value: “On a scale of 0–1, how likely is this state to lead to task success?”
- Reflection-based pruning: When a branch fails, generate a reflection and prune similar branches.
- Caching: Store LLM outputs at each node to avoid redundant generation during backtracking.
- Depth budget: Limit tree depth to 10–20 steps (agents rarely need more).
Performance: On WebShop (web navigation), LATS achieves 75% success vs. ReAct’s 40%. On HumanEval (code), pass@1 improves from 68% 94% with tree search. The cost: 10–50 more inference FLOPs per task.
AgentQ: DPO on Agent Trajectories (Detailed)
AgentQ [294] bridges offline preference learning (DPO) with online agent execution by automatically generating preference pairs from trajectory outcomes.
Pipeline:
- Rollout: Execute trajectories per task using the current policy .
- Evaluate: Score each trajectory with execution-based reward (binary pass/fail or scalar metric).
- Pair construction: For each task, construct preference pairs:(12.9)Among trajectories for the same task, the one with highest reward = chosen; lowest = rejected.
- DPO update: Apply standard DPO loss over trajectory-level log-probabilities:(12.10)
- Iterate: Updated generates new (better) trajectories in the next round.
Key design choices:
- MCTS-guided exploration: Use LATS during rollout phase to generate diverse, high-quality trajectories (better training data).
- Step-level DPO: Instead of comparing full trajectories, compare at the action level — given the same prefix, which next action leads to success?
- Self-play improvement: Each DPO iteration produces a better policy that generates better trajectories that produce better training pairs — a virtuous cycle.
Results: On WebShop, AgentQ achieves absolute 50% 82% success rate improvement over the base policy in 3 DPO iterations.
Voyager: Lifelong Learning via Skill Libraries (Detailed)
Voyager [362] introduces compositional skill accumulation — the agent builds a growing library of reusable code functions that serve as high-level actions.
Architecture:
- Automatic Curriculum: An LLM proposes progressively harder tasks based on the agent’s current skill inventory: “You can now mine wood and craft planks. Next challenge: build a crafting table.”
- Skill Generation: For each task, the agent writes a JavaScript function (executable code) that solves it:(12.11)
- Verification: Execute the code in the environment. If it succeeds, add to the skill library. If not, iterate with error feedback (up to 5 retries).
- Skill Library (vector DB): Each verified skill stored with:•Function signature + docstring (for retrieval)•Embedding of the task description (for semantic search)•Dependencies (which other skills it calls)
- Retrieval + Composition: For new tasks, retrieve the top- most relevant skills and compose them:(12.12)
Key insight: Skills are compositional — complex behaviors emerge from combining simple verified functions. The agent never forgets (library is persistent) and improves monotonically (only verified skills are added).
RLEF: RL from Execution Feedback (Detailed)
RLEF [201] applies online RL with deterministic execution-based rewards to code generation agents, establishing the simplest effective paradigm for agentic training.
Training loop:
- Sample task: Draw a coding problem with test cases from the training set.
- Generate: The agent produces a solution trajectory (reading files, writing code, running tests) using the current policy .
- Execute: Run the test suite in a sandboxed environment. Reward:(12.13)
- Update: Apply GRPO/PPO using as the reward signal.
- Repeat: Thousands of iterations with fresh tasks.
Why execution feedback is ideal for RL:
- Zero noise: Unlike human preferences, test results are deterministic. Same code same reward every time. This eliminates reward noise that destabilizes RL training.
- Infinite scale: Can generate unlimited tasks programmatically (random algorithms, API integration tests, data transformations).
- No reward hacking: Unlike learned reward models, a test suite can’t be “fooled” (assuming tests are well-written). The agent must actually solve the problem.
- Dense signal: Partial test passage () provides richer gradient than binary pass/fail.
OpenHands / SWE-Agent: GRPO for Software Engineering
OpenHands [366] and SWE-Agent [404] apply GRPO to train agents that autonomously resolve GitHub issues — reading code, writing patches, and running test suites.
Training specifics:
- Environment: Docker container with full repo, test suite, and developer tools (git, grep, lint).
- Action space: Bash commands, file edits, git operations, test execution.
- Trajectory length: 15–50 actions typical for resolving a GitHub issue.
- Reward: Binary — does the generated patch pass the issue’s regression tests?
- Group size: – trajectories per issue for GRPO normalization.
- Curriculum: Start with issues labeled “good first issue”, progress to complex multi-file refactors.
State-of-the-art results: SWE-bench Verified: 30% 55% resolve rate after RL training (vs. SFT-only baseline).
Use Case: Agentic RL for a Productivity Co-pilot
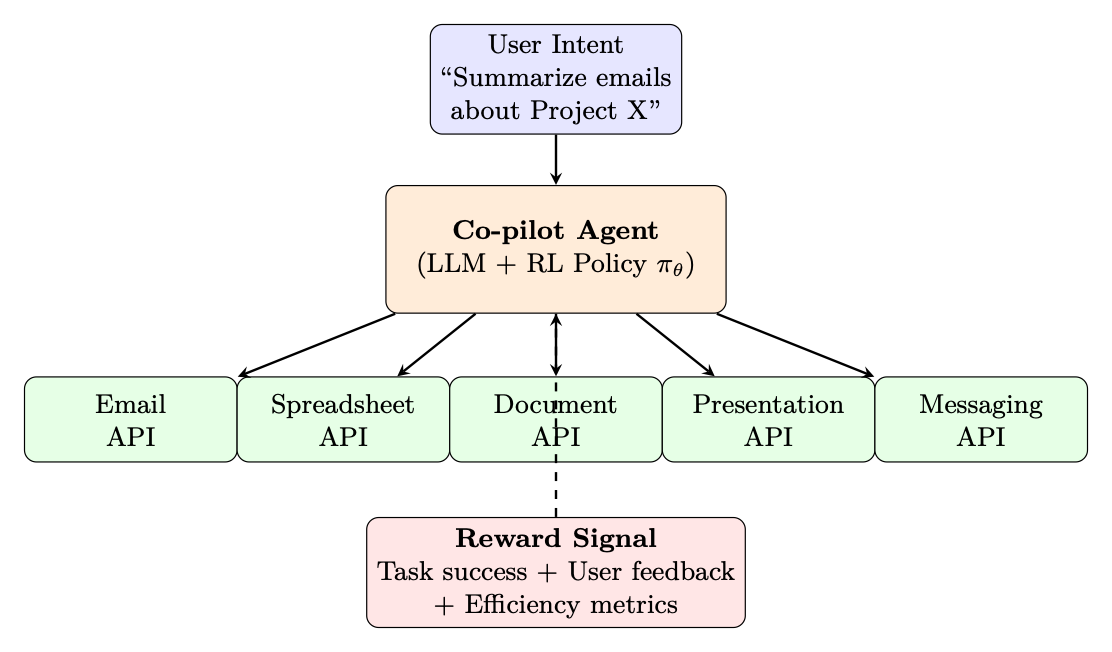
This section provides a complete blueprint for applying agentic RL techniques to train an LLM-based co-pilot that operates across a productivity application suite (documents, spreadsheets, presentations, email, messaging, cloud storage).
Architecture Overview
Formal MDP Definition for a Productivity Co-pilot
The productivity co-pilot environment is formalized as a Partially Observable Markov Decision Process (POMDP):
- : State space — Full workspace environment state: document contents, email threads, calendar events, file system, user permissions. Not fully observable: agent sees only what API queries return.
- : Action space — Structured API calls (see below). Each action is a JSON object specifying the target app, operation, and parameters.
- : Transition function — Deterministic for most operations (write to document document updated), but stochastic for network-dependent actions (email delivery time, Teams availability).
- : Reward function — Multi-component (see Reward Design section).
- : Observation space — API responses, rendered document views, error messages.
- : Observation function — Maps state to observation (API response formatting, truncation for context window limits).
- : Discount factor (long horizons, 10–50 steps typical).
Action Space Design
The action space must be structured, type-safe, and composable:
Action taxonomy by application:
AppComplexityKey ActionsOutlookMediumsearch, read, draft, send, move, flag, create_ruleExcelHighread_range, write_range, insert_formula, create_chart, pivot_table, run_macroWordMediumread_paragraphs, insert_text, format_section, find_replace, insert_tablePowerPointMediumadd_slide, insert_shape, set_text, set_layout, add_image, apply_themeTeamsLowsend_message, create_meeting, search_chat, add_members, post_to_channelSharePointMediumlist_files, upload, download, search, create_page, set_permissions
State Representation
The agent’s observation (context window) at each step:
Context budget management (critical for 128K window):
- System prompt: 2K tokens (capabilities, safety rules, output format)
- User intent + conversation: 4K tokens
- Tool history (sliding window): Last 8–12 actions + observations, summarizing older ones. Total: 80K tokens max.
- Current observation: Up to 32K tokens (large spreadsheets, email threads)
- Reserve: 10K tokens for agent’s reasoning + next action generation
State compression strategies:
- Selective inclusion: Only include API responses relevant to the current sub-goal (use an auxiliary “relevance scorer”).
- Structured summaries: Represent large spreadsheets as schema + sample rows rather than full data.
- Hierarchical memory: Store full trajectory externally; inject compressed summaries into context.
Reward Design: Multi-Objective Signal
The reward function for a productivity co-pilot must balance multiple objectives:
| Component | Weight | Signal Type | Definition |
|---|---|---|---|
| 0.40 | Binary/scalar | Task completed successfully (email sent, document created, formula correct) | |
| 0.25 | LLM judge | Output quality: formatting, clarity, correctness of content | |
| 0.15 | Scalar | Penalty for excessive steps: | |
| 0.15 | Binary | No unsafe actions (delete without confirmation, send to wrong recipient, permission violations). if any violation. | |
| 0.05 | Sparse | Explicit user feedback (thumbs up/down) when available |
Table 12.3:Reward components for productivity co-pilot training.
Intermediate rewards (dense signal):
- Successful API call (200 response): +0.05
- Correct information retrieval (verified by downstream use): +0.10
- Recovers from error gracefully (retries with corrected params): +0.08
- API error (4xx/5xx): –0.03
- Repeated identical action (loop detection): –0.10
- Asks clarifying question when intent is genuinely ambiguous: +0.05
Training Pipeline: End-to-End
Simulation Environment Architecture
Task Curriculum Design
Training effectiveness depends critically on task difficulty progression:
| Level | Steps | Apps | Example Tasks |
|---|---|---|---|
| L1: Single-step | 1–2 | 1 | “Read my latest email from Bob”, “What’s in cell A1?” |
| L2: Single-app | 3–5 | 1 | “Draft a reply to the budget email summarizing key points” |
| L3: Multi-step | 5–10 | 1 | “Create a pivot table from sales data and format top performers in bold” |
| L4: Cross-app | 5–15 | 2–3 | “Find Q4 budget emails, extract the numbers, put them in a new Excel sheet” |
| L5: Complex workflow | 10–30 | 3+ | “Prepare a weekly report: pull metrics from Excel, summarize email updates, create PowerPoint slides, share in Teams” |
Table 12.4:Productivity co-pilot curriculum levels.
Curriculum strategy:
- Start with 80% L1–L2 tasks, 20% L3 in early training.
- Advance to next level when success rate exceeds 70% on current level.
- Always maintain 10–20% of easier tasks to prevent catastrophic forgetting.
- Final mix (after convergence): 10% L1, 15% L2, 25% L3, 30% L4, 20% L5.
Safety and Guardrails
Credit Assignment in Multi-App Workflows
The key challenge: in a 20-step cross-app workflow, which steps contributed to success or failure?
Approach: Hierarchical Reward Decomposition
- Sub-goal detection: Decompose the user’s instruction into verifiable sub-goals:•“Find Q4 budget emails” Sub-goal 1 (verified: relevant emails retrieved)•“Extract numbers” Sub-goal 2 (verified: correct values parsed)•“Create Excel sheet” Sub-goal 3 (verified: sheet exists with correct data)
- Sub-goal rewards: Assign intermediate rewards at each sub-goal completion ( each).
- Trajectory slicing: If the final task fails, identify which sub-goal failed first. Apply negative reward only to the actions within that sub-goal’s span.
- Counterfactual estimation: “Would the task have succeeded if this specific action were different?” — use the value function to estimate.
Scaling and Infrastructure
Compute requirements (estimated for 70B parameter model):
ComponentResourcesNotesPolicy model (70B)8 A100 80GB (TP=8)BF16, generates trajectoriesReference model (70B)8 A100 80GB (TP=8)Frozen, for KL computationEnvironment workers128 CPU workersEach runs sandbox instanceReward model / Judge4 A100 (if LLM judge)Or zero if using execution-based rewardsTraining (GRPO updates)16 A100 (FSDP)Gradient accumulation over trajectory batchesTotal40 A100 GPUs + 128 CPUs5,000 GPU-hours for full training run
Throughput optimization:
- Async rollouts: Decouple trajectory generation from gradient updates. Generate continuously while training on previous batch.
- Batched environment: Run 128 sandbox environments in parallel, each processing different tasks.
- KV-cache sharing: For the trajectories per task, they share the same prompt prefix — use prefix caching to avoid redundant computation.
- Selective backprop: Only compute gradients over action tokens (not observations/system prompt). Reduces backward pass FLOPS by 40–60%.
Evaluation Framework
| Metric | Target | Measurement |
|---|---|---|
| Task completion rate | (L1–L3), (L4–L5) | Automated verification in sandbox |
| Safety violation rate | Count of hard constraint violations per 1000 tasks | |
| Average steps to completion | Within optimal | Compare to shortest known successful trajectory |
| User satisfaction (dogfood) | Post-task survey from internal users | |
| Cross-app success | (L4–L5) | Tasks requiring 2+ applications |
| Recovery rate | % of failed API calls where agent retries successfully | |
| Latency (time to first action) | seconds | Model inference + action planning time |
Table 12.5:Productivity co-pilot evaluation dimensions.
Benchmark suite (proposed):
- ProdBench-Easy (200 tasks): Single-app, 1–3 steps. Baseline establishment.
- ProdBench-Hard (200 tasks): Cross-app workflows, 10–30 steps. End-to-end capability.
- ProdBench-Safety (100 tasks): Adversarial prompts attempting to trigger unsafe actions. Must maintain violation rate.
- ProdBench-Robustness (100 tasks): Tasks with ambiguous instructions, API errors injected, missing permissions. Tests graceful degradation.
Lessons from Production Deployments
Complete Training Recipe
| Parameter | Value | Rationale |
|---|---|---|
| Base model | 70B Llama/Mistral | Sufficient capacity for complex multi-step reasoning |
| RL algorithm | GRPO | No critic needed; memory-efficient for long trajectories |
| Group size | 8 | Balance between variance reduction and compute cost |
| Clip | 0.1 | Tighter than standard (0.2) due to long trajectory sensitivity |
| KL coefficient | 0.04 | Moderate constraint to SFT policy |
| Learning rate | Conservative; agentic tasks are sensitive to large updates | |
| Batch size | 256 tasks 8 trajs = 2048 | Large batch for stable GRPO normalization |
| Max trajectory length | 50 steps | Covers 95% of productivity tasks |
| Context window | 128K tokens | Required for long multi-app workflows |
| Training iterations | 3000–5000 | Monitor eval metrics; early-stop on safety degradation |
| Curriculum warmup | 500 iterations (L1–L2 only) | Establish basic API usage before complex tasks |
Table 12.6:Recommended hyperparameters for productivity co-pilot RL training.
Use Case: Building a Research Agent from Scratch
This use case demonstrates how to build a fully autonomous research agent — an LLM that can formulate hypotheses, search literature, analyze data, write code, run experiments, and produce a final report — using the techniques discussed throughout this paper.
Problem Definition
MDP Formulation
Action Space
| Tool | Category | Description |
|---|---|---|
| search_papers | Literature | Query Semantic Scholar/arXiv. Returns titles, abstracts, citations. |
| read_paper | Literature | Fetch full text or specific sections of a paper. |
| write_code | Experiment | Write Python/training scripts to a workspace. |
| execute_code | Experiment | Run scripts in a sandboxed environment. Returns stdout/stderr. |
| read_file | Analysis | Read logs, CSVs, or intermediate results. |
| plot_data | Analysis | Generate matplotlib/seaborn visualizations. |
| compute_stats | Analysis | Run statistical tests (t-test, confidence intervals). |
| write_report | Output | Write sections of the final research report (LaTeX/Markdown). |
| think | Reasoning | Internal reasoning step (no external tool call). |
| submit | Terminal | Submit final report. Ends the episode. |
Table 12.7:Research Agent tool/action space.
Architecture: Model and Infrastructure Choices
Reward Design
Training Pipeline
- Phase 1 — SFT Warmup (500 steps):•Collect 200 expert research trajectories (human researchers using the tools)•SFT on successful trajectories with completion-only masking (mask tool outputs)•This teaches the agent tool-use syntax and basic research workflow
- Phase 2 — GRPO Training (3000 steps):•Prompt pool: 500 research questions across 10 domains (ML, NLP, CV, systems, etc.)•Per question: generate complete research trajectories•Score each trajectory with multi-component reward•GRPO advantage: •Update policy with clipped objective (clip , KL )•Curriculum: start with simple “summarize findings on X” tasks, progress to “design and run experiment on X”
- Phase 3 — Rejection Sampling Fine-Tuning (200 steps):•Generate 16 trajectories per hard question, keep top-2 by reward•SFT on these high-quality trajectories•Stabilizes performance on the hardest research tasks
Example Trajectory: Full MDP Trace
To illustrate how all the MDP components work together in practice, we trace a complete research episode from question to submission, annotating each step with its formal MDP elements.
Key Design Decisions and Tradeoffs
| Decision | Paper Section | Rationale |
|---|---|---|
| QLoRA () | LoRA section | 72B model; full fine-tune too expensive. for complex reasoning. |
| GRPO (not PPO) | GRPO section | No value model needed; research quality is hard to predict mid-trajectory. |
| Sparse terminal reward | Reward Shaping | Research quality only measurable at completion; intermediate shaping minimal. |
| trajectories | GRPO Group Size | Balance: enough diversity for ranking, not too expensive (100-step trajectories). |
| 128K context | Flash Attention | Long trajectories with paper contents + code + results. |
| vLLM + prefix caching | vLLM section | System prompt + research question shared across 4 rollouts. |
| Curriculum training | Agentic RL | Start simple (literature review) hard (design + execute experiments). |
| LLM-as-judge reward | Reward Models | Research quality is subjective; LLM judge is more flexible than rule-based. |
Table 12.8:Design decisions for the research agent, mapped to paper sections.
Evaluation
Lessons and Failure Modes
State-of-the-Art RL for LLM Agents
RL techniques for LLM agents focus on on-policy policy gradients combined with fine-grained credit assignment. Because agents execute complex multi-turn trajectories involving tool interactions, API queries, and code execution, standard single-turn alignment algorithms must be heavily modified.
Dominant Baseline: GRPO for Agents
Popularized by DeepSeek-R1 [69], GRPO[323] is rapidly becoming the standard for agentic training. It samples a group of complete trajectories per task, eliminating the memory-intensive critic network:
For a task prompt , GRPO samples agentic trajectories from . The advantage for each trajectory is computed by normalizing its reward relative to the group:
The GRPO objective with KL regularization:
PPO for Interactive Agents
PPO[319] remains valuable for agents operating in highly stochastic environments where step-level value estimation helps. The critic provides per-step advantage signals, enabling finer credit assignment when tool outputs are unpredictable:
- Step-level advantage estimation via GAE handles variable-length tool outputs
- Value head learns to predict “how likely is this trajectory to succeed from here”
- More stable when external tools return catastrophic errors that spike reward variance
- Trade-off: requires memory (critic) but provides denser learning signals
Fine-Grained Turn-Level Credit Assignment
The core challenge in agentic RL is the sparse reward problem. If an agent executes 20 tool actions and finally fails a unit test, a terminal reward of punishes all 20 actions equally. Modern solutions:
Alternative Paradigms
- Iterative STaR (Self-Taught Reasoner)[419]: Rather than continuous RL, use iterative offline loops. Generate trajectories filter failures SFT on successes repeat. Simple to scale, avoids RL instability. Each iteration bootstraps reasoning ability.
- Reinforcement World Model Learning (RWML)[414]: To combat reward hacking, train agents to predict the semantic consequence of their actions. The agent receives an auxiliary reward for accurately predicting how environment state will change (e.g., predicting database table changes before executing SQL). This forces genuine understanding over superficial reward-gaming.
- LATS (Language Agent Tree Search)[438]: Apply Monte Carlo Tree Search over agent action sequences. At each step, expand multiple candidate actions, simulate their outcomes, and backpropagate rewards through the tree. Combines RL value estimation with search-time compute scaling.
Core Methodology Comparison
| Method | Reward Density | Memory Cost | Primary Advantage |
|---|---|---|---|
| GRPO[323] | Sequence / final metric | Low (no critic) | Massive GPU memory reduction; simple implementation |
| PPO[319] | Step-by-step (GAE) | High (critic needed) | Fine-grained credit assignment; stable in noisy envs |
| Iterative STaR[419] | Sparse (filtered binary) | Minimal (SFT only) | Simple to scale; avoids RL optimization instability |
| RWML[414] | Dense (predictive) | Medium | Mitigates reward hacking via world modeling |
| LATS[438] | Backpropagated | High (tree expansion) | Best quality per task; scales with inference compute |
Table 12.9:Comparison of RL paradigms for LLM agents.
Interactive RL Environments for Agent Training
The dominant paradigm in early agentic RL relied on static datasets: curated trajectories, offline preference pairs, or fixed benchmark suites. While tractable, this approach has a fundamental limitation—agents trained on static data cannot discover novel strategies through environment interaction, and reward signals are limited to what was anticipated at dataset creation time. The field has shifted decisively toward interactive RL environments: live simulators where agents execute actions, receive feedback, and update policies based on real outcomes.
NeMo Gym (NVIDIA)
NeMo Gym[271] is NVIDIA’s framework for interactive RL environments designed specifically for LLM agent training. Its architecture cleanly separates the agent (the LLM policy) from the environment (the task simulator), enabling independent scaling of each component.
Key design principles:
- Multi-turn rollouts: Environments support extended interaction sequences, not just single-step queries. The agent can call tools, receive results, and continue reasoning across many turns.
- Tool-calling verification: Rewards are computed by executing the agent’s tool calls and verifying outcomes against ground truth—providing dense, reliable signal.
- Decoupled agent/environment: The environment runs as a separate service, allowing heterogeneous compute allocation (e.g., GPU for the agent, CPU for environment simulation).
Nemotron 3 Super was trained using NeMo Gym with 21 environment configurations spanning math, code, tool use, and multi-turn dialogue, generating 1.2M rollouts. The diversity of environments is critical: agents trained on a single environment type tend to overfit its reward structure.
RLFactory
RLFactory[369] is a plug-and-play framework for multi-round tool-use RL, designed to minimize the engineering overhead of connecting LLM policies to diverse tool environments.
MOSAIC: Safety in Agentic Training
As agentic RL environments become more capable, safety becomes a first-class concern. MOSAIC[50] (March 2026) addresses the problem of training agents that are both capable and safe in interactive environments.
The core MOSAIC framework introduces a plan check act or refuse loop:
- Plan: The agent generates a candidate action sequence.
- Check: A safety verifier evaluates the plan against a constraint set (harm categories, policy rules).
- Act or Refuse: If the plan passes, execute; otherwise, generate a refusal with explanation.
Safety is trained via trajectory-level preference learning: rather than labeling individual actions as safe/unsafe, MOSAIC labels entire trajectories, capturing the cumulative safety impact of multi-step plans. This is critical because individual actions that appear benign can compose into harmful sequences.
xAI’s Grok 4.5 (July 2026) [389] introduced a novel data source: anonymized developer-session traces from Cursor—the actual keystrokes, navigation patterns, and editing sequences of engineers working in real codebases. Mid-trained on these traces, Grok 4.5 achieved top rankings on agentic tool-use benchmarks. This signals a “compute + traces” paradigm: once compute is scaled, the scarce input becomes recordings of target behavior—analogous to how AlphaGo was bootstrapped from human games before transitioning to self-play. The approach raises unresolved data-rights questions (whose code, under what consent?) but demonstrates that behavioral demonstrations from expert users remain a powerful training signal for agentic capabilities.