
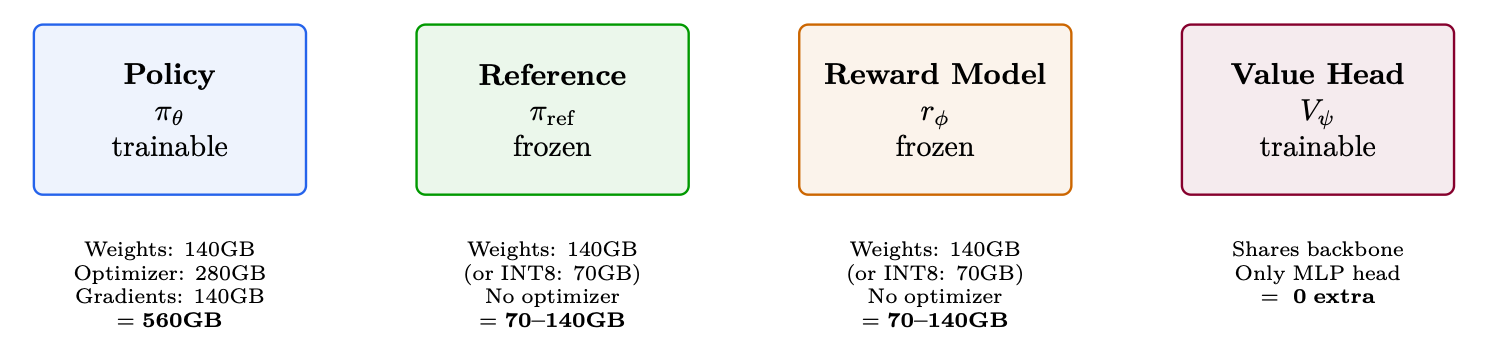
Training LLMs with reinforcement learning from human feedback is as much a systems engineering challenge as it is an algorithmic one. Unlike standard supervised fine-tuning—which involves a single model, a single forward-backward pass, and well-understood scaling—RLHF requires multiple models (policy, reference, reward model, value head) to be loaded simultaneously, coordinated through a complex rollout-scoring-training loop, and distributed across dozens to hundreds of GPUs. This chapter covers the systems-level details that make large-scale RLHF training possible: memory budgeting, parallelism strategies (Data, Tensor, Pipeline, Sequence, and their combinations), the generation bottleneck, decoupled architectures, weight synchronization, fault tolerance, and production monitoring.
The 4-Model Memory Challenge
Parallelism Strategies in Detail
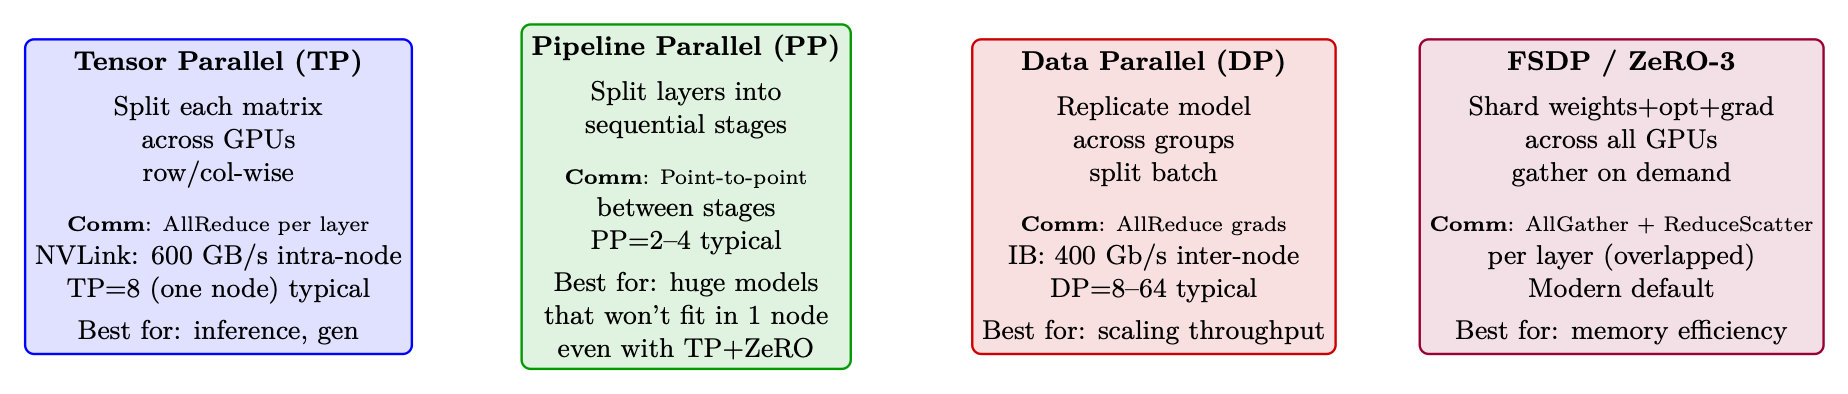
Training large language models requires distributing computation across many GPUs. There are fundamentally different axes along which to parallelize, each with distinct trade-offs. This section provides detailed coverage of each strategy with mathematical formulations, diagrams, and practical guidance.
Data Parallelism (DP) and Distributed Data Parallelism (DDP)
Data Parallelism is the simplest and most common form of distributed training [210]. Each GPU holds a complete copy of the model, processes a different mini-batch, and synchronizes gradients.
A single-process approach where one “master” GPU scatters input, gathers outputs, and broadcasts gradients. Limited by GIL and PCIe bandwidth to the master GPU.
Multi-process: each GPU runs its own process. Gradients are synchronized via ring-AllReduce [321] in the background while backward computation continues.
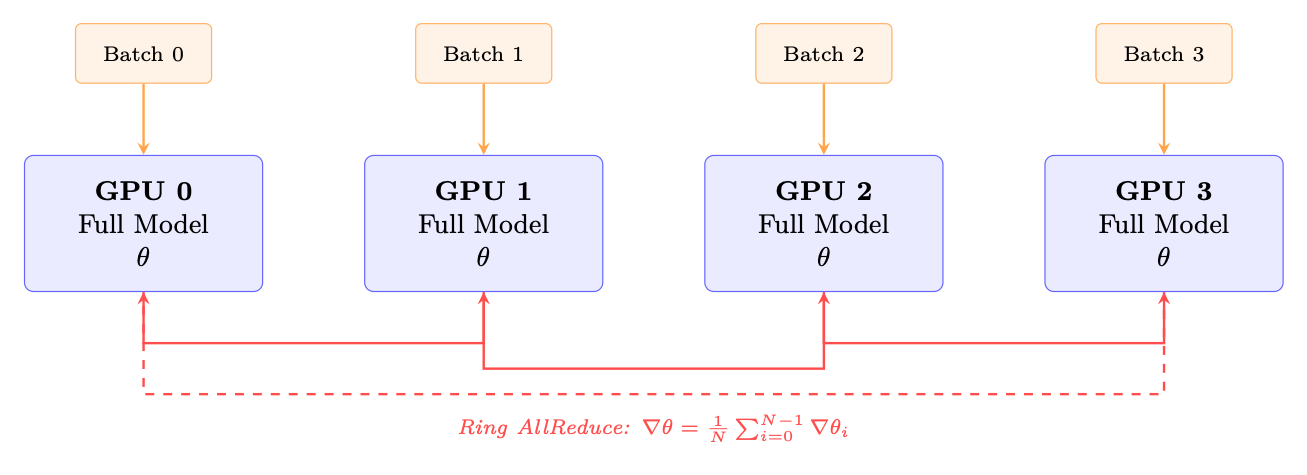
Key properties of DDP:
- Memory: Each GPU stores full model + optimizer + gradients. For 70B BF16: 560 GB/GPU—impossible without memory optimizations.
- Communication: One AllReduce of gradient tensor per step. Size = model parameters 2 bytes (BF16). Ring AllReduce cost: bytes transferred per GPU.
- Scaling: Near-linear up to 64 GPUs. Beyond that, communication starts to dominate.
- Gradient bucketing: DDP groups parameters into buckets (default 25 MB) and starts AllReduce as soon as a bucket’s gradients are ready—overlapping communication with backward computation.
import torch.distributed as dist
from torch.nn.parallel import DistributedDataParallel as DDP

dist.init_process_group(backend="nccl")  # NCCL for GPU communication
model = model.to(local_rank)
model = DDP(model, device_ids=[local_rank],
            gradient_as_bucket_view=True,    # Memory optimization
            static_graph=True)               # Enable comm optimizations
Tensor Parallelism (TP)
Tensor Parallelism (Megatron-LM style [327]) splits individual weight matrices across GPUs. Each GPU computes a partial result, and an AllReduce combines them.
The weight matrix is split column-wise across GPUs:
Each GPU computes independently (no communication). The output is split along the hidden dimension.
The weight matrix is split row-wise: where . Input must also be split. Each GPU computes a partial sum, then an AllReduce produces the final output.
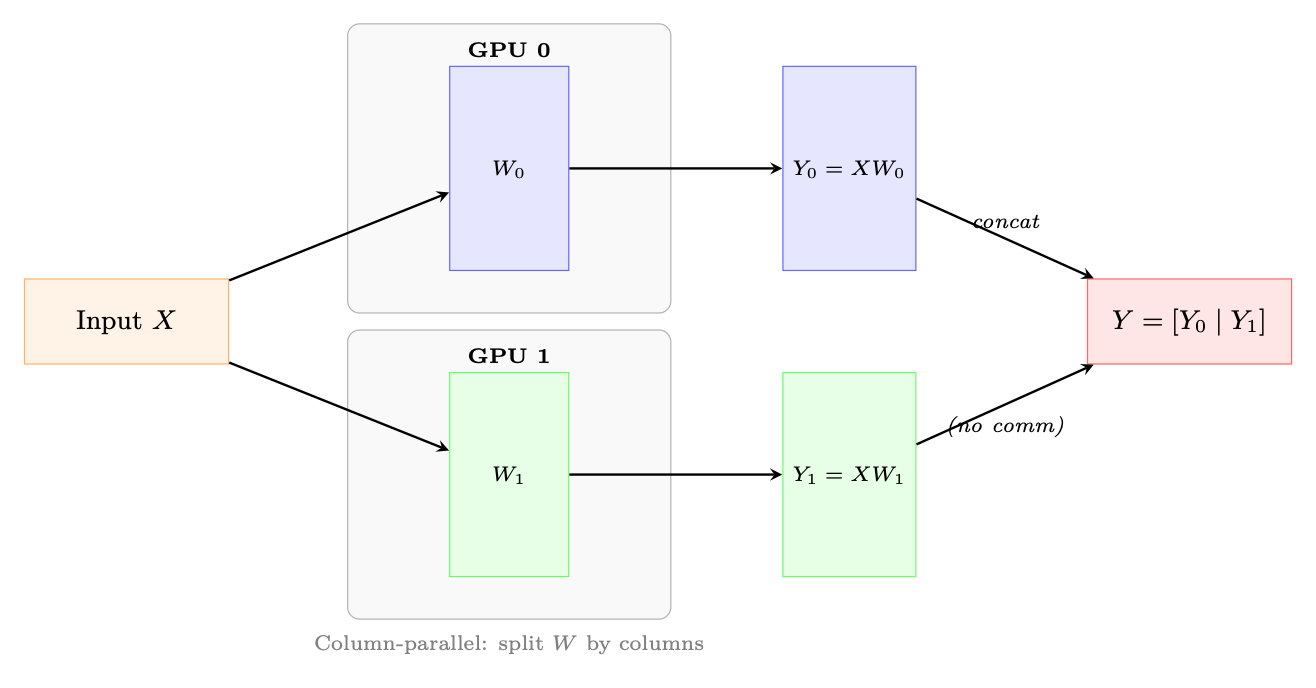
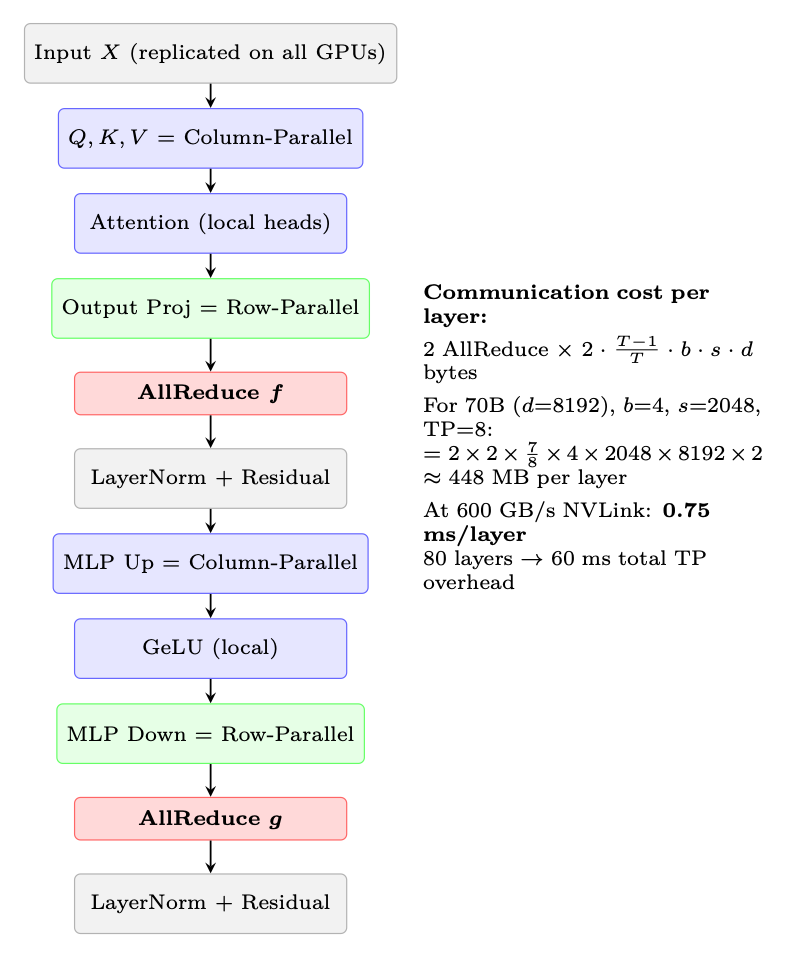
In a Transformer layer, Megatron-LM applies TP as follows:
- MLP: Column-parallel for the first linear (), row-parallel for the second (). One AllReduce after the row-parallel layer.
- Attention: , , projections are column-parallel (split heads across GPUs). Output projection is row-parallel. One AllReduce after output projection.
- Total: 2 AllReduce per transformer layer (one for attention, one for MLP).
Sequence Parallelism (SP)
Sequence Parallelism [191] addresses a memory bottleneck that Tensor Parallelism alone cannot solve: the activation memory in LayerNorm and Dropout layers.
With TP, weight memory is split across GPUs. But LayerNorm and Dropout operate on the full hidden dimension and are replicated on every GPU. Their activations (needed for backward pass) consume memory proportional to —the same on every GPU, unreduced by TP.
Split the sequence dimension for operations that don’t require cross-GPU communication (LayerNorm, Dropout, residual connections). Each GPU processes a slice of the sequence for these operations, then gathers the full sequence only where needed (attention, linear layers).
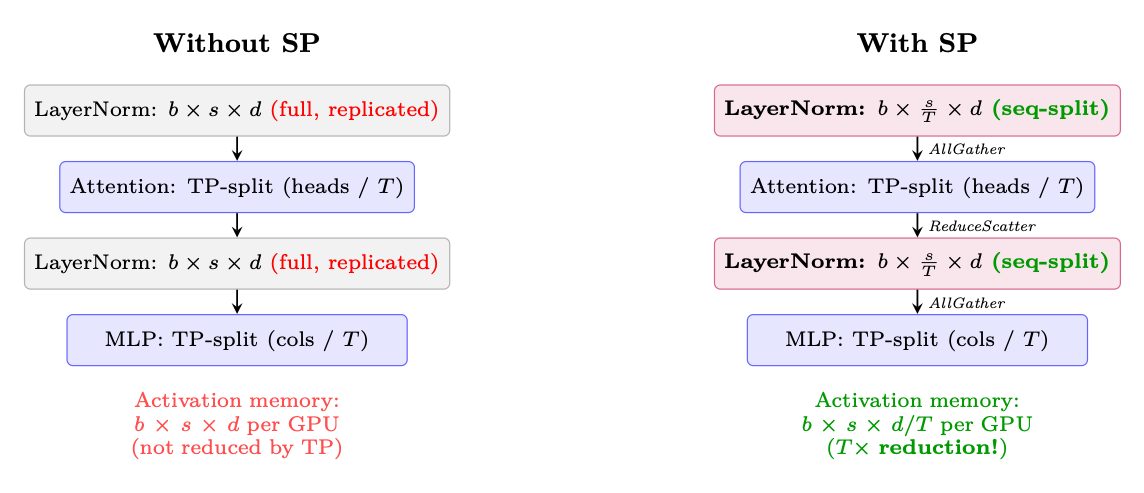
Memory savings from SP (70B model, TP=8, batch=4, seq=2048):
Pipeline Parallelism (PP)
Pipeline Parallelism splits the model vertically by layers, assigning consecutive groups of layers to different devices (stages). Activations flow forward through stages; gradients flow backward.
Naive pipeline execution creates “bubbles”—idle time while a stage waits for input from the previous stage or gradients from the next:
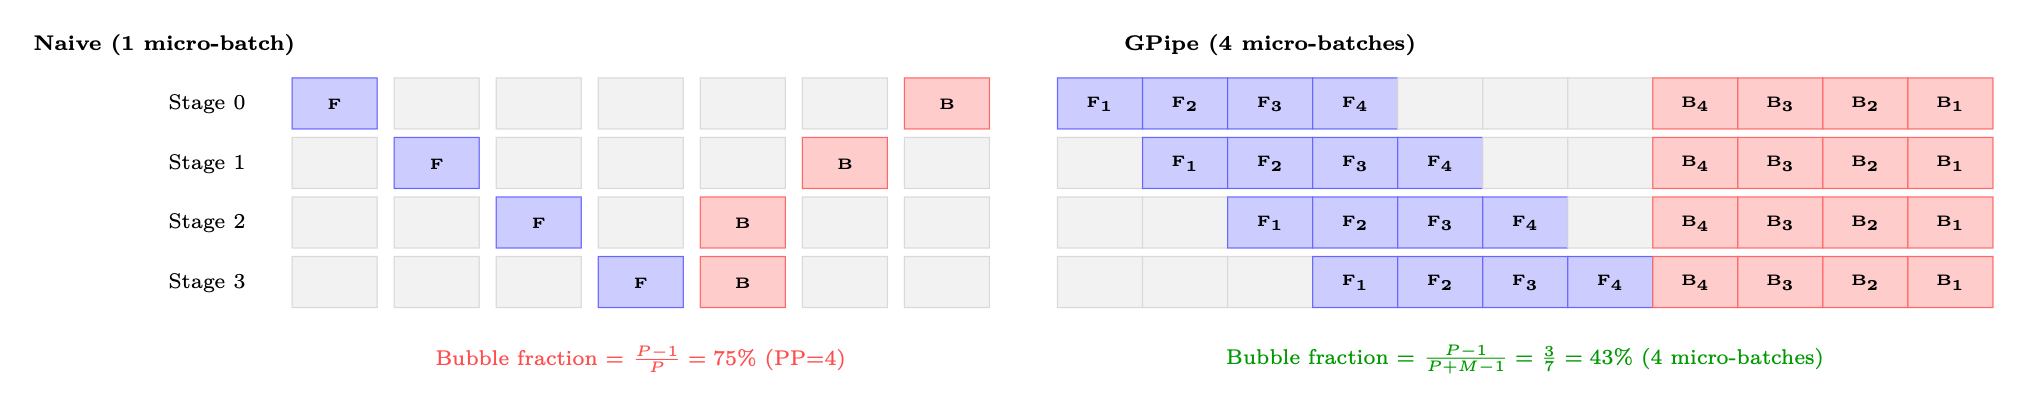
For pipeline stages and micro-batches per step:
To keep bubble overhead 10%, you need . For PP=4: at least 30 micro-batches.
| Schedule | Bubble | Memory | Characteristics |
|---|---|---|---|
| GPipe | activations | Simple; all-forward then all-backward [152] | |
| 1F1B | activations | Interleaved; steady-state memory bounded [263] | |
| Interleaved 1F1B | activations | Virtual stages (); further reduces bubble [264] | |
| Zero-Bubble (ZB-H1) | activations | Splits backward into B and W phases [296] |
Table 11.1:Pipeline scheduling strategies
Unlike TP (AllReduce), PP only requires point-to-point communication of activations between adjacent stages:
For micro-batch=4, seq=2048, =8192: MB per transfer. At InfiniBand 50 GB/s: 2.6 ms per transfer—small relative to compute per stage.
Not all layers have equal compute:
- Embedding layer: Very cheap (lookup table).
- Transformer blocks: Uniform compute.
- Final LM head: Moderate (large matrix multiply for vocabulary projection).
Assign more transformer layers to middle stages and fewer to the first/last stages to balance compute.
Fully Sharded Data Parallelism (FSDP / ZeRO-3)
FSDP [431] (PyTorch) and ZeRO-3 [304] (DeepSpeed) address the memory duplication inherent in DDP: instead of every GPU holding a full copy of parameters, gradients, and optimizer states, each GPU owns only a slice and reconstructs the full tensor on-the-fly when needed.
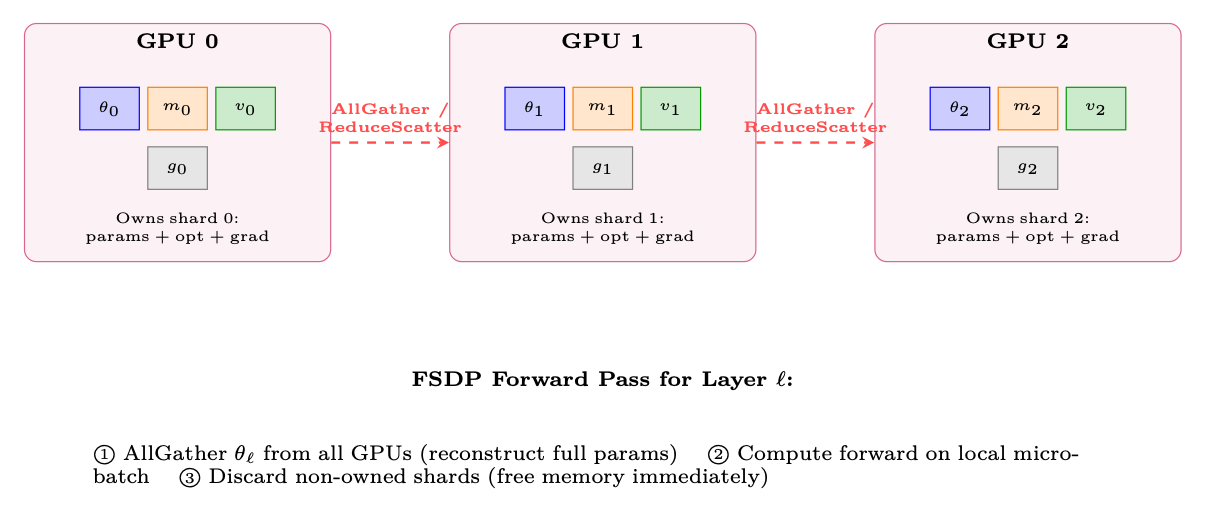
FSDP execution flow per layer:
- Forward: AllGather parameters compute discard non-owned shards.
- Backward: AllGather parameters (again) compute gradients ReduceScatter gradients (each GPU gets its gradient shard) discard non-owned parameter shards.
- Optimizer step: Each GPU updates only its owned shard using its gradient shard and optimizer states.
| Strategy | Sharded | Memory/GPU | Communication |
|---|---|---|---|
| DDP (no sharding) | Nothing | 1120 GB | AllReduce (gradients only) |
| ZeRO-1 | Optimizer states | 385 GB | AllReduce (gradients) |
| ZeRO-2 | Optimizer + gradients | 368 GB | AllReduce (gradients) |
| ZeRO-3 / FSDP | Everything | 140 GB ✓ | AllGather + ReduceScatter (per layer) |
Table 11.2:Memory comparison: DDP vs FSDP/ZeRO stages (70B model, 8 GPUs). Baseline: BF16 params (140 GB) + BF16 grads (140 GB) + FP32 master+m+v (840 GB) = 1120 GB per GPU.
from functools import partial
from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
from torch.distributed.fsdp import ShardingStrategy, MixedPrecision, BackwardPrefetch
from torch.distributed.fsdp.wrap import transformer_auto_wrap_policy
from transformers.models.llama.modeling_llama import LlamaDecoderLayer

# Wrap model with FSDP
auto_wrap = partial(transformer_auto_wrap_policy,
                    transformer_layer_cls={LlamaDecoderLayer})
mp_policy = MixedPrecision(
    param_dtype=torch.bfloat16,
    reduce_dtype=torch.bfloat16,
    buffer_dtype=torch.bfloat16,
)

model = FSDP(
    model,
    sharding_strategy=ShardingStrategy.FULL_SHARD,  # ZeRO-3
    mixed_precision=mp_policy,
    auto_wrap_policy=auto_wrap,  # Wrap each transformer layer
    use_orig_params=True,        # Required for torch.compile compatibility
    limit_all_gathers=True,      # Bound peak memory (1 AllGather in flight at a time)
    forward_prefetch=True,       # Prefetch next layer's params during current layer
    backward_prefetch=BackwardPrefetch.BACKWARD_PRE,  # Prefetch during backward
)
3D Parallelism: Combining Strategies
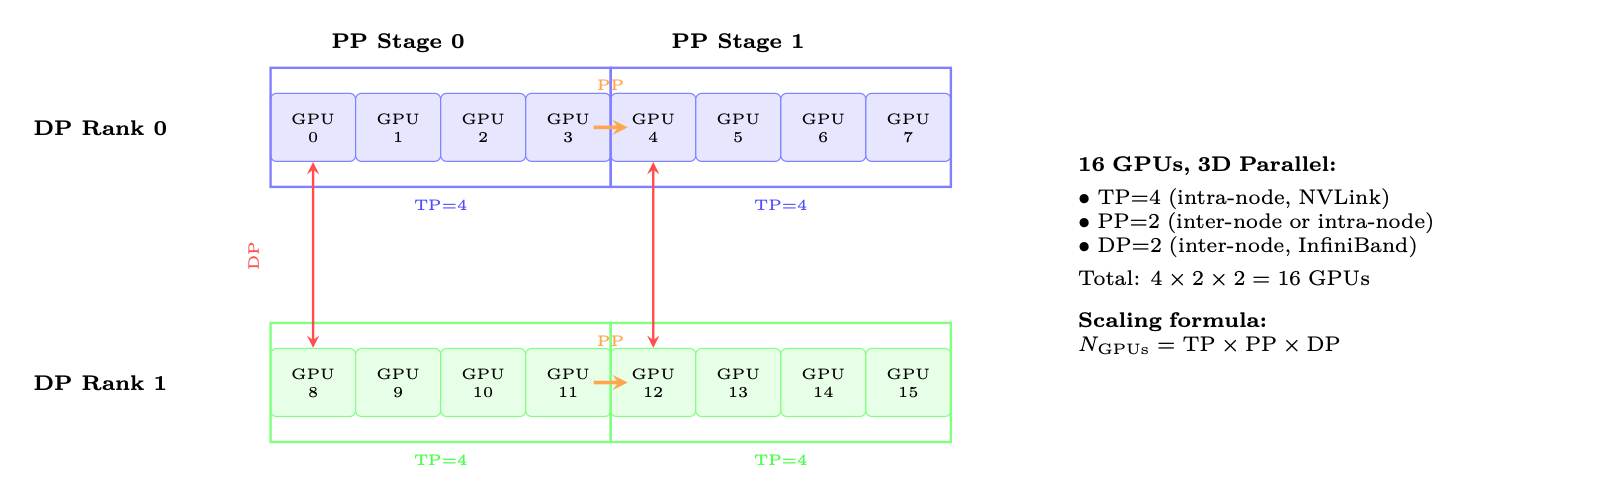
Production systems at scale (70B+) combine TP, PP, and DP/FSDP simultaneously:
| Strategy | Splits | Communication | Scaling Limit | Overhead | When to Use |
|---|---|---|---|---|---|
| DP/DDP | Batch | AllReduce (grads) | 64 GPUs | 5–10% | Model fits on 1 GPU |
| FSDP | Params+Opt+Grad | AllGather+RS | 100s of GPUs | 10–20% | Default for 13B |
| TP | Weight matrices | AllReduce (2/layer) | 8 GPUs (1 node) | 12–18% | Large model inference+train |
| SP | Activations (seq) | Reuses TP comms | Same as TP | 0% extra | Always with TP |
| PP | Layers (stages) | Point-to-point | 16 stages | 15–30% | 100B+ models only |
Table 11.3:Parallelism strategy comparison summary
Decoupled DiLoCo: Training Across Datacenters
Conventional distributed training assumes high-bandwidth interconnects—100+ Gbps InfiniBand within a single datacenter. This requirement makes it impossible to train across geographically distributed datacenters using standard internet links. Decoupled DiLoCo[113] (Google DeepMind, April 2026) breaks this assumption, enabling large-scale training across regions with commodity bandwidth.
Decoupled DiLoCo extends this by further decoupling the outer synchronization: workers do not need to synchronize simultaneously. Instead, updates are asynchronous across regions, with a coordinator applying outer updates as they arrive. This tolerates the variable latency of wide-area networks.
The Generation Bottleneck: Quantitative Analysis
| Config | Batch | Time/batch | Tok/s/GPU | Notes |
|---|---|---|---|---|
| TP=1, batch=1 | 1 | 36s | 14 | Baseline, worst case |
| TP=4, batch=1 | 1 | 9s | 57 | Linear TP scaling for gen |
| TP=4, batch=32 | 32 | 15s | 1092 | Near-optimal batching |
| TP=4, batch=128, vLLM | 128 | 45s | 1456 | Continuous batching |
| TP=4, batch=128, INT8 | 128 | 25s | 2621 | 2 bandwidth savings |
Table 11.4:Generation throughput for 70B model (512 tokens, various configurations)
Optimization stack (cumulative speedup):
- vLLM + PagedAttention[196] (2–4): Eliminates KV cache fragmentation, enables larger batches
- Continuous batching[412] (1.5–2): Don’t wait for longest sequence; start new ones as others finish
- Speculative decoding[206] (2–3): Small draft model proposes 5 tokens, large model verifies in one forward pass. Accept 3–4 on average.
- INT8/FP8 weights for gen (2): Halve bandwidth needs. Quality loss is minimal since we’re sampling (not computing exact logits for training)
- CUDA graphs (1.1–1.3): Eliminate kernel launch overhead for fixed-shape operations
- Prefix caching (1.5 for shared-prefix prompts): Don’t recompute system prompt KV cache
# Production vLLM generation setup
from vllm import LLM, SamplingParams

engine = LLM(
    model="./policy_checkpoint",
    tensor_parallel_size=4,           # TP=4 per instance
    gpu_memory_utilization=0.92,      # Leave headroom for KV cache
    max_num_batched_tokens=16384,     # Max tokens in flight
    max_num_seqs=256,                 # Max concurrent sequences
    dtype="bfloat16",
    enable_prefix_caching=True,       # Cache system prompt KV
    speculative_model="./draft_1B",   # Speculative decoding
    num_speculative_tokens=5,
    block_size=16,                    # PagedAttention block size
    swap_space=4,                     # GB swap space for preemption
)

# Generate responses for RLHF batch
sampling_params = SamplingParams(
    temperature=0.7, top_p=0.9, max_tokens=512,
    logprobs=1,  # Need log-probs for PPO ratio calculation
)
outputs = engine.generate(prompts, sampling_params)
# Extract: responses, log_probs for each token (needed for PPO/GRPO)
Decoupled Architecture: Production Design
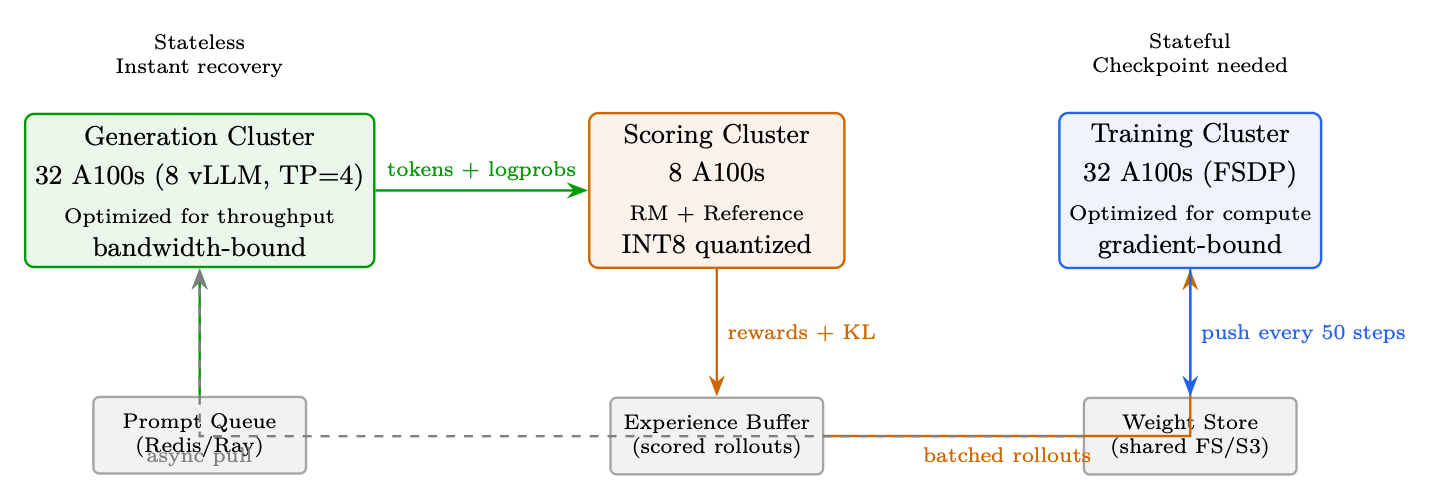
Production RLHF systems such as DeepSpeed-Chat [410] and OpenRLHF [148] use a decoupled architecture that separates generation, scoring, and training into independently scalable clusters.
Weight Synchronization Strategies
StrategyStalenessBandwidthQuality ImpactSynchronous (every step)0 steps140 GB/stepPerfect but too slowPeriodic (every 50 steps)25 avg2.8 GB/step amortized2% quality lossDelta compression (INT8)25 avg0.4 GB/step3% quality lossAsync streaming5–10 steps14 GB/step (background)1% quality loss
Memory Optimization Techniques
ZeRO StageWhat Gets ShardedMemory/GPU (70B, 8 GPUs)None (Data Parallel)Nothing (full replica)560GB per GPU (impossible)ZeRO-1Optimizer states only175GBZeRO-2Optimizer states + Gradients105GBZeRO-3 (FSDP)Optimizer + Gradients + Parameters70GB (fits in A100-80GB!)
Additional techniques:
- Gradient checkpointing[49]: Don’t store all activations; recompute during backward pass. Saves 60% activation memory, costs 33% extra compute. Selective: only checkpoint attention layers (memory-heavy), keep FFN activations (compute-heavy to recompute).
- Mixed precision[255]: Forward in BF16 (2 bytes/param), optimizer states in FP32 (4 bytes each for m,v). Master weights in FP32 for accumulation.
- CPU offloading (ZeRO-Infinity [305]): Move optimizer states to CPU RAM. 50% memory savings but 2–3 slower (PCIe 64GB/s bottleneck).
- Activation offloading: Move activations to CPU during forward, bring back for backward. Only when memory is truly critical.
- Flash Attention[64, 65]: O() memory instead of O() for attention. 2–4 faster + massive memory savings for long sequences.
Flash Attention’s Impact on RLHF
# DeepSpeed ZeRO-3 configuration for 70B RLHF training
ds_config = {
    "bf16": {"enabled": True},
    "zero_optimization": {
        "stage": 3,
        "overlap_comm": True,                    # Overlap communication with compute
        "contiguous_gradients": True,            # Better memory layout
        "reduce_scatter": True,                  # More efficient than allreduce
        "reduce_bucket_size": 5e7,               # 50M params per bucket
        "prefetch_bucket_size": 5e7,             # Prefetch next bucket
        "param_persistence_threshold": 1e5,      # Keep small params on all GPUs
        "offload_optimizer": {"device": "cpu", "pin_memory": True},  # CPU offload
        "sub_group_size": 1e9,                   # Reduce fragmentation
    },
    "gradient_accumulation_steps": 4,
    "gradient_clipping": 1.0,
    "train_micro_batch_size_per_gpu": 2,
    "wall_clock_breakdown": True,
}
Fault Tolerance at Scale
Production fault tolerance stack:
- Detection: NCCL timeout (60s), GPU heartbeat (10s), NVML health monitoring, ECC error counting.
- Checkpointing: Async every 50–100 steps. Non-blocking (background thread). Save: model weights, optimizer states (Adam m/v), scheduler state, RNG states, KL coefficient, replay buffer. Keep last 3 checkpoints. Time: 30s for 70B (parallel write to NVMe).
- Recovery: (a) Generation cluster = stateless, just restart and load latest weights. (b) Training cluster: load checkpoint, rebuild NCCL process group excluding failed node, redistribute FSDP shards, resume from last checkpoint.
- Elastic training: Torch Elastic / Kubernetes auto-scaling. Replace failed node within minutes. Training continues with GPUs temporarily.
- Prevention: GPU health pre-screening (run GEMM stress test before starting). Hot spares on standby. Redundant network paths (dual-rail InfiniBand).
End-to-End Latency Breakdown
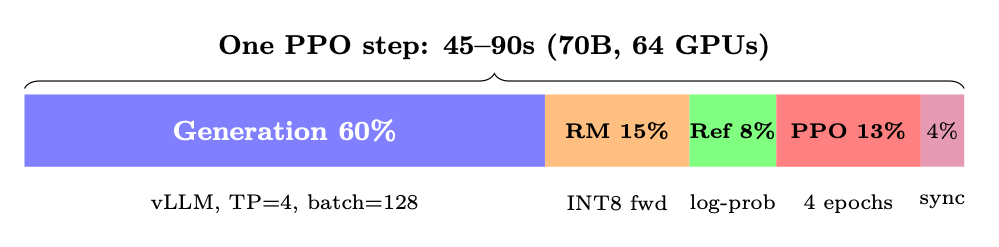
PhaseTime (70B)Bound ByOptimizationGeneration (128512 tok)30–45sMemory bandwidthvLLM, spec decoding, INT8Reward scoring5–8sCompute (batch forward)INT8 RM, batch=128Reference log-probs4–6sCompute (batch forward)INT8 ref, or LoRA (free)PPO update (4 epochs)8–12sCompute (backprop)FSDP, Flash AttentionWeight sync0–3sNetwork (async)Delta compression, asyncTotal (monolithic)50–75sTotal (decoupled, overlapped)35–50sGen overlaps with prev training
Monitoring and Observability
Network Topology and Communication Patterns
Efficient distributed training requires understanding the hierarchical communication fabric that connects GPUs. Modern clusters use a two-tier architecture: ultra-fast intra-node links and slower but scalable inter-node networks.
Intra-Node: NVLink and NVSwitch
| Generation | BW per link | Links/GPU | Total BW | Platform |
|---|---|---|---|---|
| NVLink 3.0 | 50 GB/s | 12 | 600 GB/s | A100 (DGX A100) |
| NVLink 4.0 | 50 GB/s | 18 | 900 GB/s | H100 (DGX H100) |
| NVLink 5.0 | 100 GB/s | 18 | 1800 GB/s | B200 (DGX B200) |
Table 11.5:NVLink generations and their impact on LLM training
Within a single node (typically 8 GPUs), NVSwitch provides full-bisection bandwidth between all GPU pairs. This means any GPU can communicate with any other at full NVLink speed simultaneously—critical for Tensor Parallelism where every layer requires an AllReduce across all 8 GPUs.
Inter-Node: InfiniBand and RoCE
For FSDP/ZeRO-3 AllGather and ReduceScatter operations across nodes, the inter-node network dominates.
| Technology | Bandwidth | Latency | Notes |
|---|---|---|---|
| InfiniBand NDR | 400 Gb/s (50 GB/s) | 1–2 s | Gold standard, RDMA, lossless |
| InfiniBand NDR (dual-rail) | 800 Gb/s (100 GB/s) | 1–2 s | Used in H100 clusters |
| RoCE v2 | 100–400 Gb/s | 2–5 s | Cheaper, needs PFC/ECN tuning |
| Ethernet (TCP) | 100–400 Gb/s | 10–50 s | Not suitable for 16 GPU training |
Table 11.6:Inter-node networking options for LLM training clusters
Communication Primitives and Their Costs
Understanding when each collective is used helps diagnose bottlenecks:
| Collective | Data Moved | Used By | When |
|---|---|---|---|
| AllReduce | TP, DP | Sum gradients or activations across GPUs | |
| AllGather | FSDP forward | Reconstruct full parameter tensor before matmul | |
| ReduceScatter | FSDP backward | Distribute gradient shards after backprop | |
| Broadcast | PP | Send activations to next pipeline stage | |
| Send/Recv | PP | Point-to-point between adjacent stages |
Table 11.7:NCCL collective operations in distributed LLM training
where is the message size (bytes) and is the number of participants.
Network Topology Design
Production clusters use fat-tree or rail-optimized topologies:
- Fat-tree: Full bisection bandwidth at every level. Any node can communicate with any other at full speed. Expensive (many switches) but maximally flexible.
- Rail-optimized: GPU on every node connects to the same leaf switch (“rail ”). AllReduce within a rail is cheap; cross-rail traffic is expensive. Used by Meta’s RSC and Google’s TPU pods.
- 3D torus / Dragonfly: Used in HPC clusters (Frontier, Aurora). Topology-aware job placement is critical.
Training Throughput and Model FLOPs Utilization
Measuring Training Efficiency: MFU
Model FLOPs Utilization (MFU)[55] is the standard metric for training efficiency:
For a transformer with parameters, sequence length, and batch size:
The factor of 6 comes from: 2 (multiply-add) 3 (forward + backward, where backward forward). The second term accounts for attention’s cost.
| Model | Hardware | MFU | Tokens/sec/GPU | Configuration |
|---|---|---|---|---|
| LLaMA-7B | 8A100 | 57% | 3,200 | FSDP, FlashAttn, BF16 |
| LLaMA-13B | 16A100 | 52% | 1,750 | FSDP, FlashAttn, BF16 |
| LLaMA-70B | 64A100 | 45% | 380 | FSDP+TP=8, FlashAttn |
| GPT-4 (est.) | 10,000+ H100 | 40–50% | — | 3D parallelism |
| PaLM-540B | 6144 TPUv4 | 46% | — | DP+TP+PP |
Table 11.8:MFU benchmarks across scales and hardware
Compute-Optimal Batch Sizing
The effective batch size interacts with hardware utilization in non-obvious ways:
- Too small: GPU underutilized (low arithmetic intensity), communication dominates.
- Too large: Diminishing learning per token (critical batch size exceeded), wastes compute.
- Sweet spot: The critical batch size where gradient noise equals gradient signal. For LLMs, –M tokens [250].
For RLHF specifically, the batch contains rollouts (not just tokens):
Typical production values: prompts, – generations, – tokens 32K–256K tokens per step.
Profiling and Bottleneck Diagnosis
Key profiling tools and what they reveal:
ToolCapturesBest Fortorch.profilerKernel timing, memoryFinding slow ops, memory leaksNVIDIA Nsight SystemsFull GPU timelineVisualizing overlap, gaps between kernelsnccl_debug=INFOCollective sizes/timesDiagnosing communication bottleneckstorch.cuda.memory_statsAllocation patternsFinding fragmentation, peak usageDeepSpeed Flops ProfilerPer-layer FLOPsIdentifying load imbalancepy-spy / scaleneCPU profilingData loading, tokenization bottlenecks
Cost Analysis and Cloud Deployment
Understanding the economics of RLHF training is essential for planning.
Hardware Cost Comparison
| GPU | On-Demand/hr | Spot/hr | Memory | Use Case |
|---|---|---|---|---|
| A100 80GB | $2.50–3.50 | $1.00–1.50 | 80 GB HBM2e | Budget training, gen cluster |
| H100 80GB | $4.00–6.00 | $2.00–3.00 | 80 GB HBM3 | Production training |
| H200 141GB | $6.00–8.00 | — | 141 GB HBM3e | Large context, fewer-GPU configs |
| MI300X 192GB | $3.50–5.00 | $1.50–2.50 | 192 GB HBM3 | Cost-effective alternative |
Table 11.9:Approximate cloud GPU costs for RLHF training (2024–2025 pricing)
RLHF Training Cost Estimation
Cost Optimization Strategies
- Spot/preemptible instances: 50–70% savings. Requires robust checkpointing (save every 5 minutes).
- Right-sizing: Don’t use H100 for generation (memory-bound); A100 achieves similar tokens/$ for inference.
- Quantized inference: INT8/FP8 for generation and scoring halves GPU count for those clusters.
- Progressive training: Start with 8B proxy model for reward engineering/debugging ($200), then scale to 70B.
- LoRA for reference-free: Eliminates reference model entirely (50% memory reduction).
- Shorter sequences first: Curriculum from 2565121024 token generations saves 40% compute.
Distributed Checkpointing
At scale, naive checkpointing becomes a bottleneck. A 70B model with optimizer state requires saving 840 GB per checkpoint (FP32 master weights + Adam m + v).
Checkpointing Strategies
| Strategy | Save Time (70B) | Storage/ckpt | Characteristics |
|---|---|---|---|
| Synchronous (all ranks) | 30–60s (blocking) | 420 GB | Simple, stalls training |
| Async (background copy) | 1s (non-blocking) | 420 GB | Overlaps with next step |
| Incremental (delta) | 1s | 5–20 GB | Only save changed params |
| Sharded (FSDP native) | 5–10s | 420 GB sharded | Each rank saves its shard |
Table 11.10:Checkpointing approaches for large-scale RLHF
Production Checkpointing with torch.distributed.checkpoint
import torch.distributed.checkpoint as dcp
from torch.distributed.checkpoint.state_dict import get_state_dict, StateDictOptions

# Save: each rank writes its shard in parallel
state_dict = {"model": get_state_dict(model, options=StateDictOptions(full_state_dict=False))}
dcp.save(
    state_dict=state_dict,
    storage_writer=dcp.FileSystemWriter("/mnt/checkpoints/step_5000"),
    planner=dcp.DefaultSavePlanner(),  # Handles FSDP sharding automatically
)

# Async save: non-blocking, runs in background thread
future = dcp.async_save(
    state_dict=state_dict,
    storage_writer=dcp.FileSystemWriter("/mnt/checkpoints/step_5000"),
)
# Training continues immediately; future.result() blocks only if needed
Hardware Selection Guide
Choosing the right hardware depends on model size, budget, and training phase.
| Model Size | Training Phase | Recommended | Configuration |
|---|---|---|---|
| 7B | SFT + RLHF | 1–2 A100 | Single node, no parallelism needed |
| 7–13B | SFT + RLHF | 4–8 A100 | FSDP, optional TP=2 for gen |
| 13–34B | SFT + RLHF | 8–16 A100/H100 | FSDP + TP=4 for gen |
| 70B | RLHF (full) | 32–64 A100/H100 | Decoupled, FSDP + TP=8 |
| 70B | RLHF (LoRA) | 8–16 A100/H100 | No ref model, LoRA adapters |
| 100B | RLHF | 128+ H100 | 3D parallelism (TP+PP+DP) |
Table 11.11:Hardware recommendations by model scale and training phase
Optimizer Configuration for RL Training
RL training (PPO, GRPO, DPO) imposes unique demands on the optimizer compared to pretraining or SFT. The loss landscape is non-stationary (the policy changes what data is generated), gradients are noisier (reward signal variance), and training is more prone to catastrophic forgetting or reward hacking. This section consolidates RL-specific optimizer guidance, using AdamW [239] as the default optimizer.
Why RL Requires Different Optimizer Settings
Recommended Hyperparameters by RL Method
| Method | Optimizer | LR | WD | Warmup | Schedule |
|---|---|---|---|---|---|
| DPO | AdamW | 0.0 | 50 steps | Constant or Linear | |
| PPO (policy) | AdamW | 0.0 | 20 steps | Constant | |
| PPO (critic) | AdamW | 0.0 | 20 steps | Constant | |
| GRPO | AdamW | 0.0 | 20 steps | Constant |
Table 11.12:Optimizer settings for RL training phases. All use , , , max_grad_norm=1.0, BF16.
Beta-2 = 0.95 for RL: Faster Adaptation
The default Adam gives a very long memory for the second moment (1000-step effective window). In RL training, the loss landscape changes rapidly as the policy evolves—the gradient variance from 1000 steps ago is irrelevant. Using shortens the window to 20 steps, making the adaptive learning rate respond quickly to changing gradient statistics.
Mixed Precision for RL: FP32 Master Weights Are Critical
RL training is particularly sensitive to numerical precision:
- Gradients are noisier—small updates must accumulate accurately over many steps
- Learning rates are very small (–), making
- BF16 mantissa (7 bits 0.8% relative precision) cannot represent updates of magnitude relative to weights of magnitude
Always use FP32 master weights for RL training. BF16-only training (no FP32 copy) reliably causes reward collapse in PPO/GRPO after 100–500 steps.
Gradient Clipping is Critical for RL
In PPO and GRPO, the reward signal can be highly variable, especially early in training. A single bad batch can produce gradients with norm , which would completely destroy the model weights. max_grad_norm=1.0 is the standard setting. For SFT, clipping is less critical but still recommended.
Diagnosing RL Training Instability
HuggingFace TRL Configuration for RL
The TRL library [376] provides production-ready implementations of PPO, DPO, and other RL methods for LLMs.
from trl import PPOConfig, PPOTrainer, DPOConfig, DPOTrainer

# --- PPO Configuration ---
ppo_config = PPOConfig(
    # Optimizer (AdamW with RL-specific settings)
    learning_rate=1e-6,           # 10-100x smaller than SFT

    # PPO-specific
    ppo_epochs=4,                 # mini-batch updates per rollout
    mini_batch_size=16,
    batch_size=64,                # rollout batch size

    # Gradient control
    max_grad_norm=1.0,

    # KL penalty (replaces weight decay as regularizer)
    init_kl_coef=0.2,            # initial KL penalty coefficient
    adap_kl_ctrl=True,           # adaptive KL targeting
    target_kl=6.0,               # target KL divergence

    # Mixed precision
    bf16=True,                   # BF16 compute, FP32 master weights
)

ppo_trainer = PPOTrainer(
    model=model,
    ref_model=ref_model,
    config=ppo_config,
    tokenizer=tokenizer,
    dataset=dataset,
)

# --- DPO Configuration ---
dpo_config = DPOConfig(
    output_dir="./dpo_output",

    # Optimizer
    learning_rate=5e-7,           # even smaller than PPO
    optim="adamw_torch",
    adam_beta1=0.9,
    adam_beta2=0.95,              # shorter memory for RL
    weight_decay=0.0,            # no WD -- KL provides regularization

    # Schedule
    lr_scheduler_type="constant_with_warmup",
    warmup_steps=50,

    # Gradient control
    max_grad_norm=1.0,

    # DPO-specific
    beta=0.1,                    # KL constraint strength
    loss_type="sigmoid",         # standard DPO loss

    # Mixed precision
    bf16=True,

    # Training
    num_train_epochs=1,          # DPO typically 1 epoch
    per_device_train_batch_size=4,
    gradient_accumulation_steps=8,
)

dpo_trainer = DPOTrainer(
    model=model,
    ref_model=ref_model,
    args=dpo_config,
    train_dataset=dataset,
    tokenizer=tokenizer,
)
dpo_trainer.train()
Listing 6:Complete PPO and DPO optimizer configuration using TRL.
MoE Considerations for RL Training
Miles [295] is PyTorch’s official stack for large-scale LLM RL, connecting SGLang (for high-throughput rollout generation) with Megatron-LM (for distributed training updates). It supports both disaggregated execution (separate GPU pools for rollout and training, maximizing utilization) and colocated execution (fitting both on the same nodes for smaller-scale experiments). Miles represents the standardization of what was previously ad-hoc infrastructure—analogous to how PyTorch itself standardized deep learning training a decade ago.